

The recently released Jev AI model has been quite a cultural phenomenon in technical communities in the past 2 weeks.
While Jev aims to classify things, it’s easy to dismiss Jev as “just a classifier,” and my own view of Jev has evolved quite a bit over the past few days. In particular, my thoughts went from “classifiers used to be my bread & butter; I can easily build this myself” (more on this later) to “wow, this actually works better than I thought.”
Sure, the latest state-of-the-art GPT and open-weight LLMs can do the same kinds of classification tasks as Jev, while also being capable of much more general decision-making. But Jev’s advantage is that it can handle those classification tasks much faster and more cheaply.
At the other end of the spectrum, for a narrow, well-defined problem, Jev probably won’t classify anything better, faster, or cheaper than a special-purpose classifier. But its selling point is that it is far more general than those task-specific models.
So, what is the methodology behind Jev (based on an educated guess), what can it do, and why is it so popular? I aim to answer all of these later in this article. However, I thought starting with a brief history of language models for decision-making would be a great way to begin. And it hopefully helps demystify some of the hype and show what Jev does very well (”Jev is essentially a text classifier,” but “Jev is also not ‘just’ a text classifier.”)
PS: I am not affiliated with Jev in any way. Also, I am not offered free access to Jev, and this is also not a product endorsement, just a technical article to offer some insights into the history of text classification to help you make sense of the recent hype.
Since this is a long article, I recommend reading it in your browser, where you can access the table of contents menu on the left side.
1. Language modeling and classification in the pre-transformer era
For completeness, before we put Jev in context (no pun intended), I thought it made the most sense to start chronologically. In this section, I want to take a brief tour of applied text classification via naive Bayes, logistic regression, and the more classic (deep) neural networks before transformer-based models came along.
1.1 Bag-of-words: naive Bayes, logistic regression, and XGBoost
Back in the day, when I was a grad student 15 years ago, even though recurrent neural networks already existed (more on that later), text classification was usually done with a bag-of-words representation because it was straightforward and could get good results on moderately sized datasets.
In short, we can think of the bag-of-words representation as a method that makes free-form text input of different lengths compatible with classic classifiers (naive Bayes, Logistic Regression, SVMs, Random Forest, XGBoost, to name a few), which expect a fixed-size input vector.
Popular real-world applications include anything from news article classification to email spam filtering. And yes, allegedly even Gmail’s original spam filter used a Naive Bayes model with a bag-of-words representation.
As a side note, I wrote about this approach exactly 12 years ago. It was one of the first things I shared on arXiv.
(Text classification with Naive Bayes goes back to at least 1961, where it was used to sort computer abstracts; see the Automatic Indexing: And Experimental Inquiry paper.)
So, what exactly is this bag-of-words representation? It’s a way to convert free-form texts with different lengths, e.g.,
Training example 1: “Zentropa is the most original movie I’ve seen in years. If you like unique thrillers that are influenced by film noir, then this is just the right cure for all of those Hollywood summer blockbusters clogging the theaters these days. Von Trier’s follow-ups like Breaking the Waves have gotten more acclaim, but this is really his best work.”
Training example 2: “This film is just plain horrible. John Ritter doing pratt falls, 75% of the actors delivering their lines as if they were reading them from cue cards, poor editing, horrible sound mixing”
Training example 3: “Zentropa has much in common with The Third Man, another noir-like film set among the rubble of postwar Europe.”
into a fixed-size representation for the aforementioned “classic” classifiers. (The example above is an excerpt from the popular IMDb movie review classification dataset.)
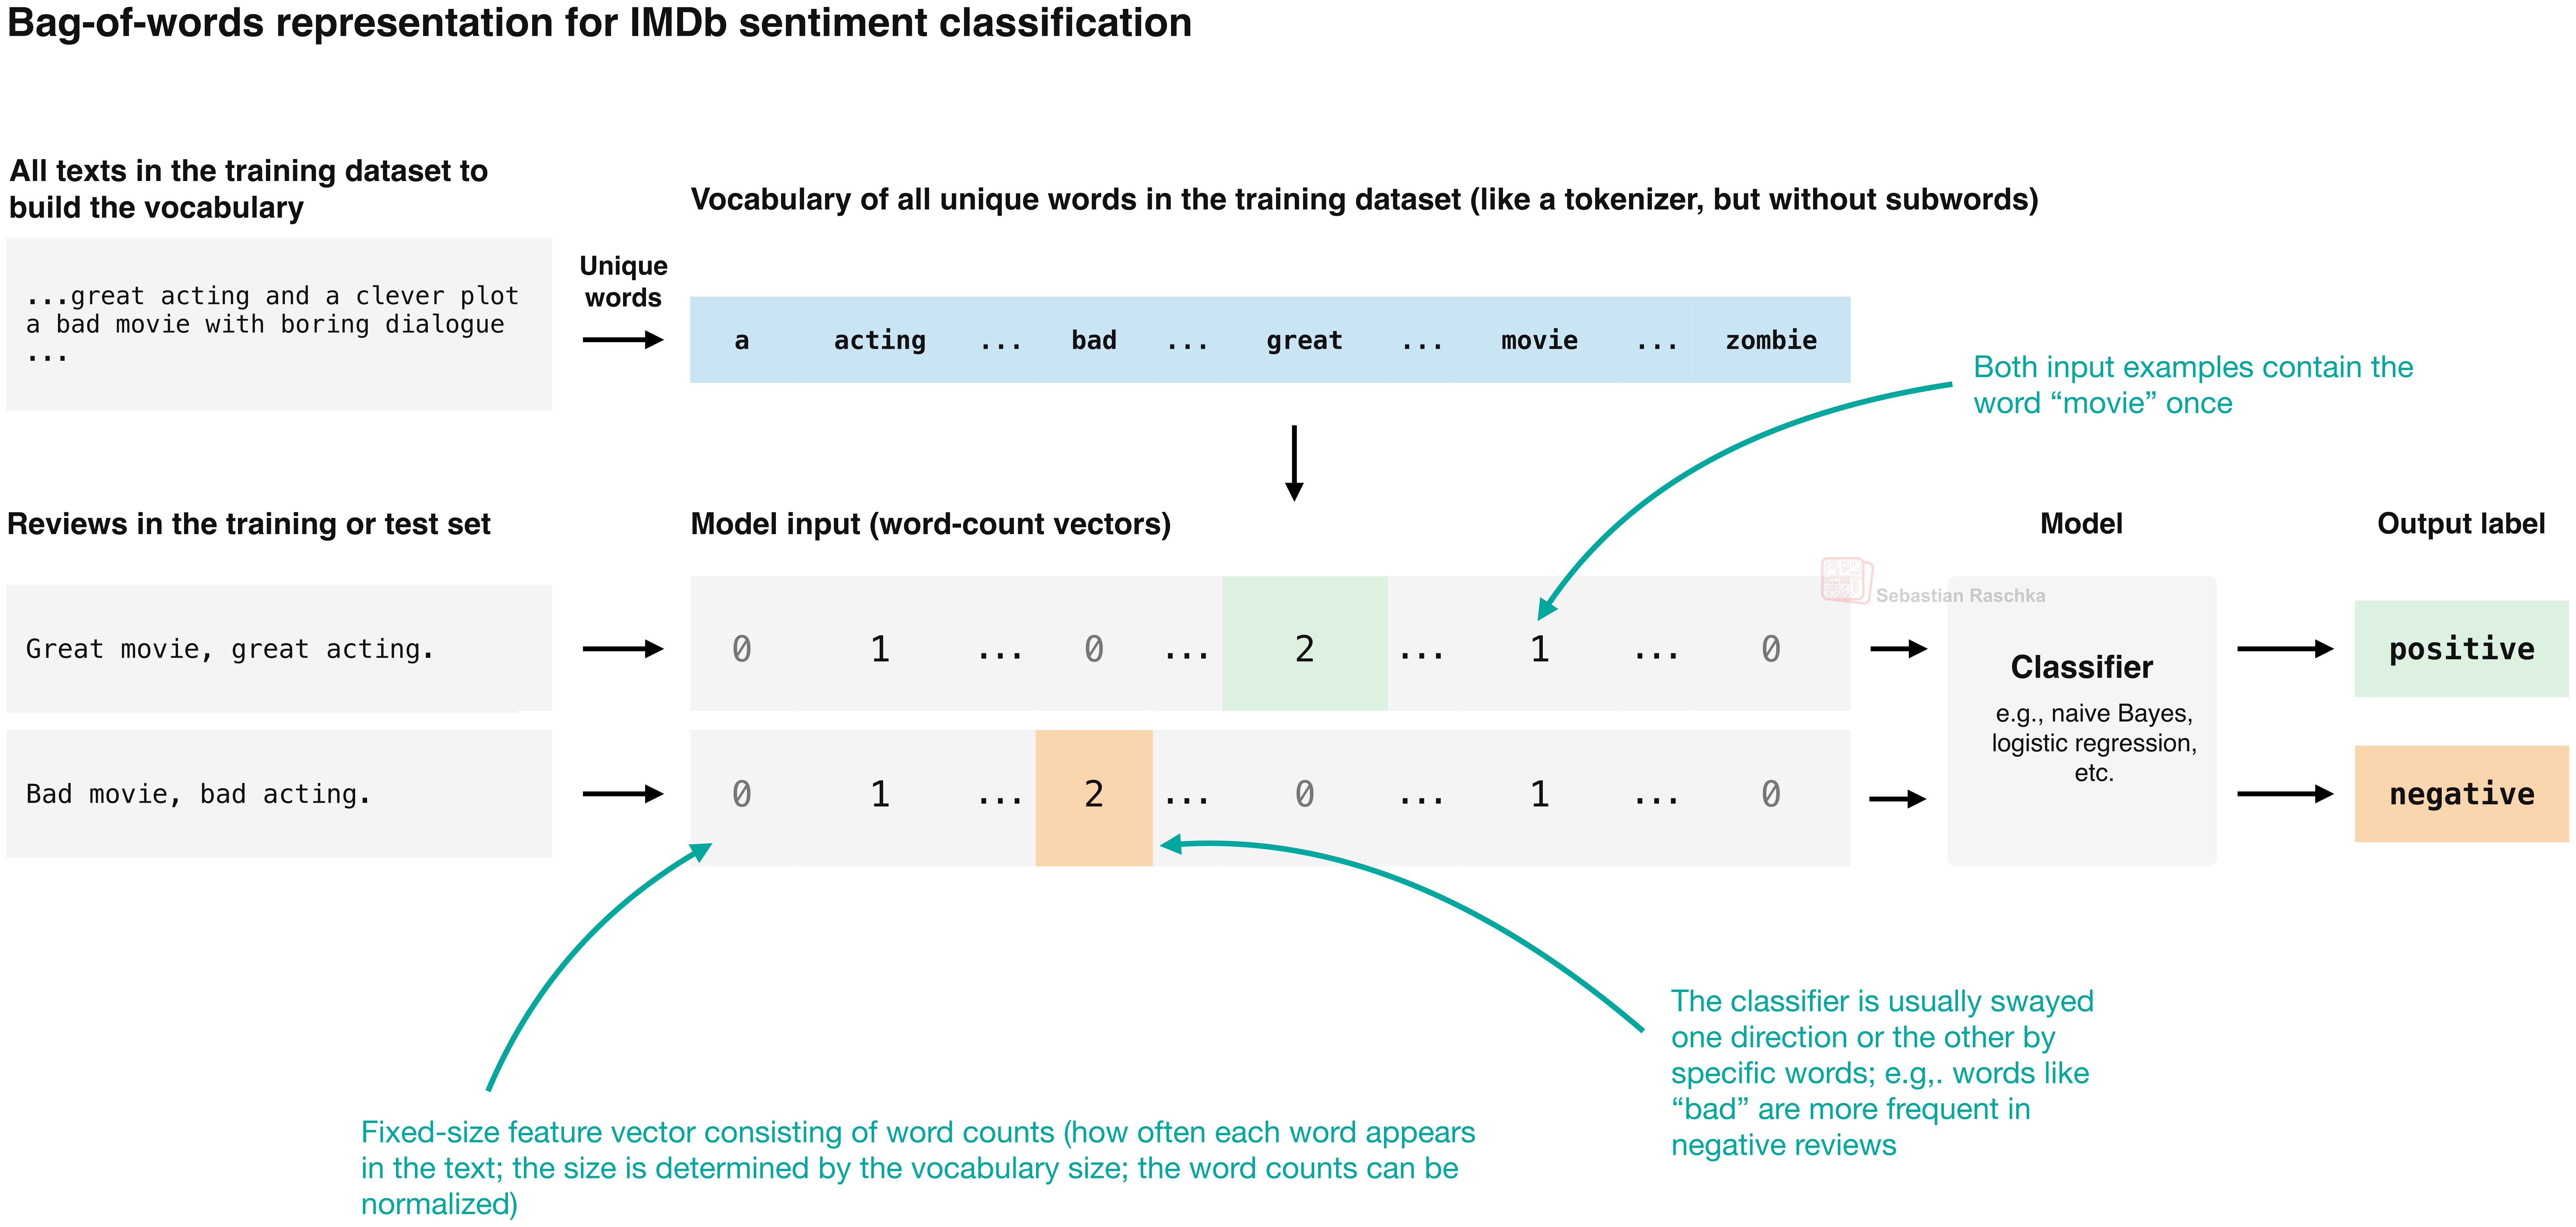
A bag-of-words model starts by building the vocabulary, which consists of all unique words in the training set (optionally, one can get rid of so-called stopwords like “a” and “the”, which are words that carry little to no semantic meaning in most contexts).
A bag-of-words representation results in these fixed-size inputs by assigning each word in a vocabulary its own position in a vector. We then count how often each word occurs in a document. For example, if we have a vocabulary of 50,000 unique words, it produces a fixed-size vector with 50,000 entries, regardless of whether the input consists of only ten words or 300k words. Note that most entries are zero because each document contains only a small subset of the vocabulary. (Instead of representing the raw counts, there are also normalization schemes like TF-IDF.)
Then, once we have these word frequency vectors, we can train a classifier on a labeled training set, such as emails labeled as spam or non-spam. For example, a logistic regression model would then learn feature weights that correlate certain words (and word counts) with particular labels. For instance, certain words might increase the predicted spam probability, and others may decrease it.
This approach is computationally cheap and can work well when particular words provide strong clues about the label. In a simple classification task such as spam classification, this is often enough to get quick, reasonably accurate results.
But one of the biggest downsides of this approach is that, because of the nature of the bag-of-words representation, it loses word order. So, for example, “the dog bites the man” and “the man bites the dog” produce identical vectors despite describing different events.
(There are some workarounds to preserve some local order by adding word pairs or longer sequences, called n-grams, as features, although this increases the vocabulary size.)
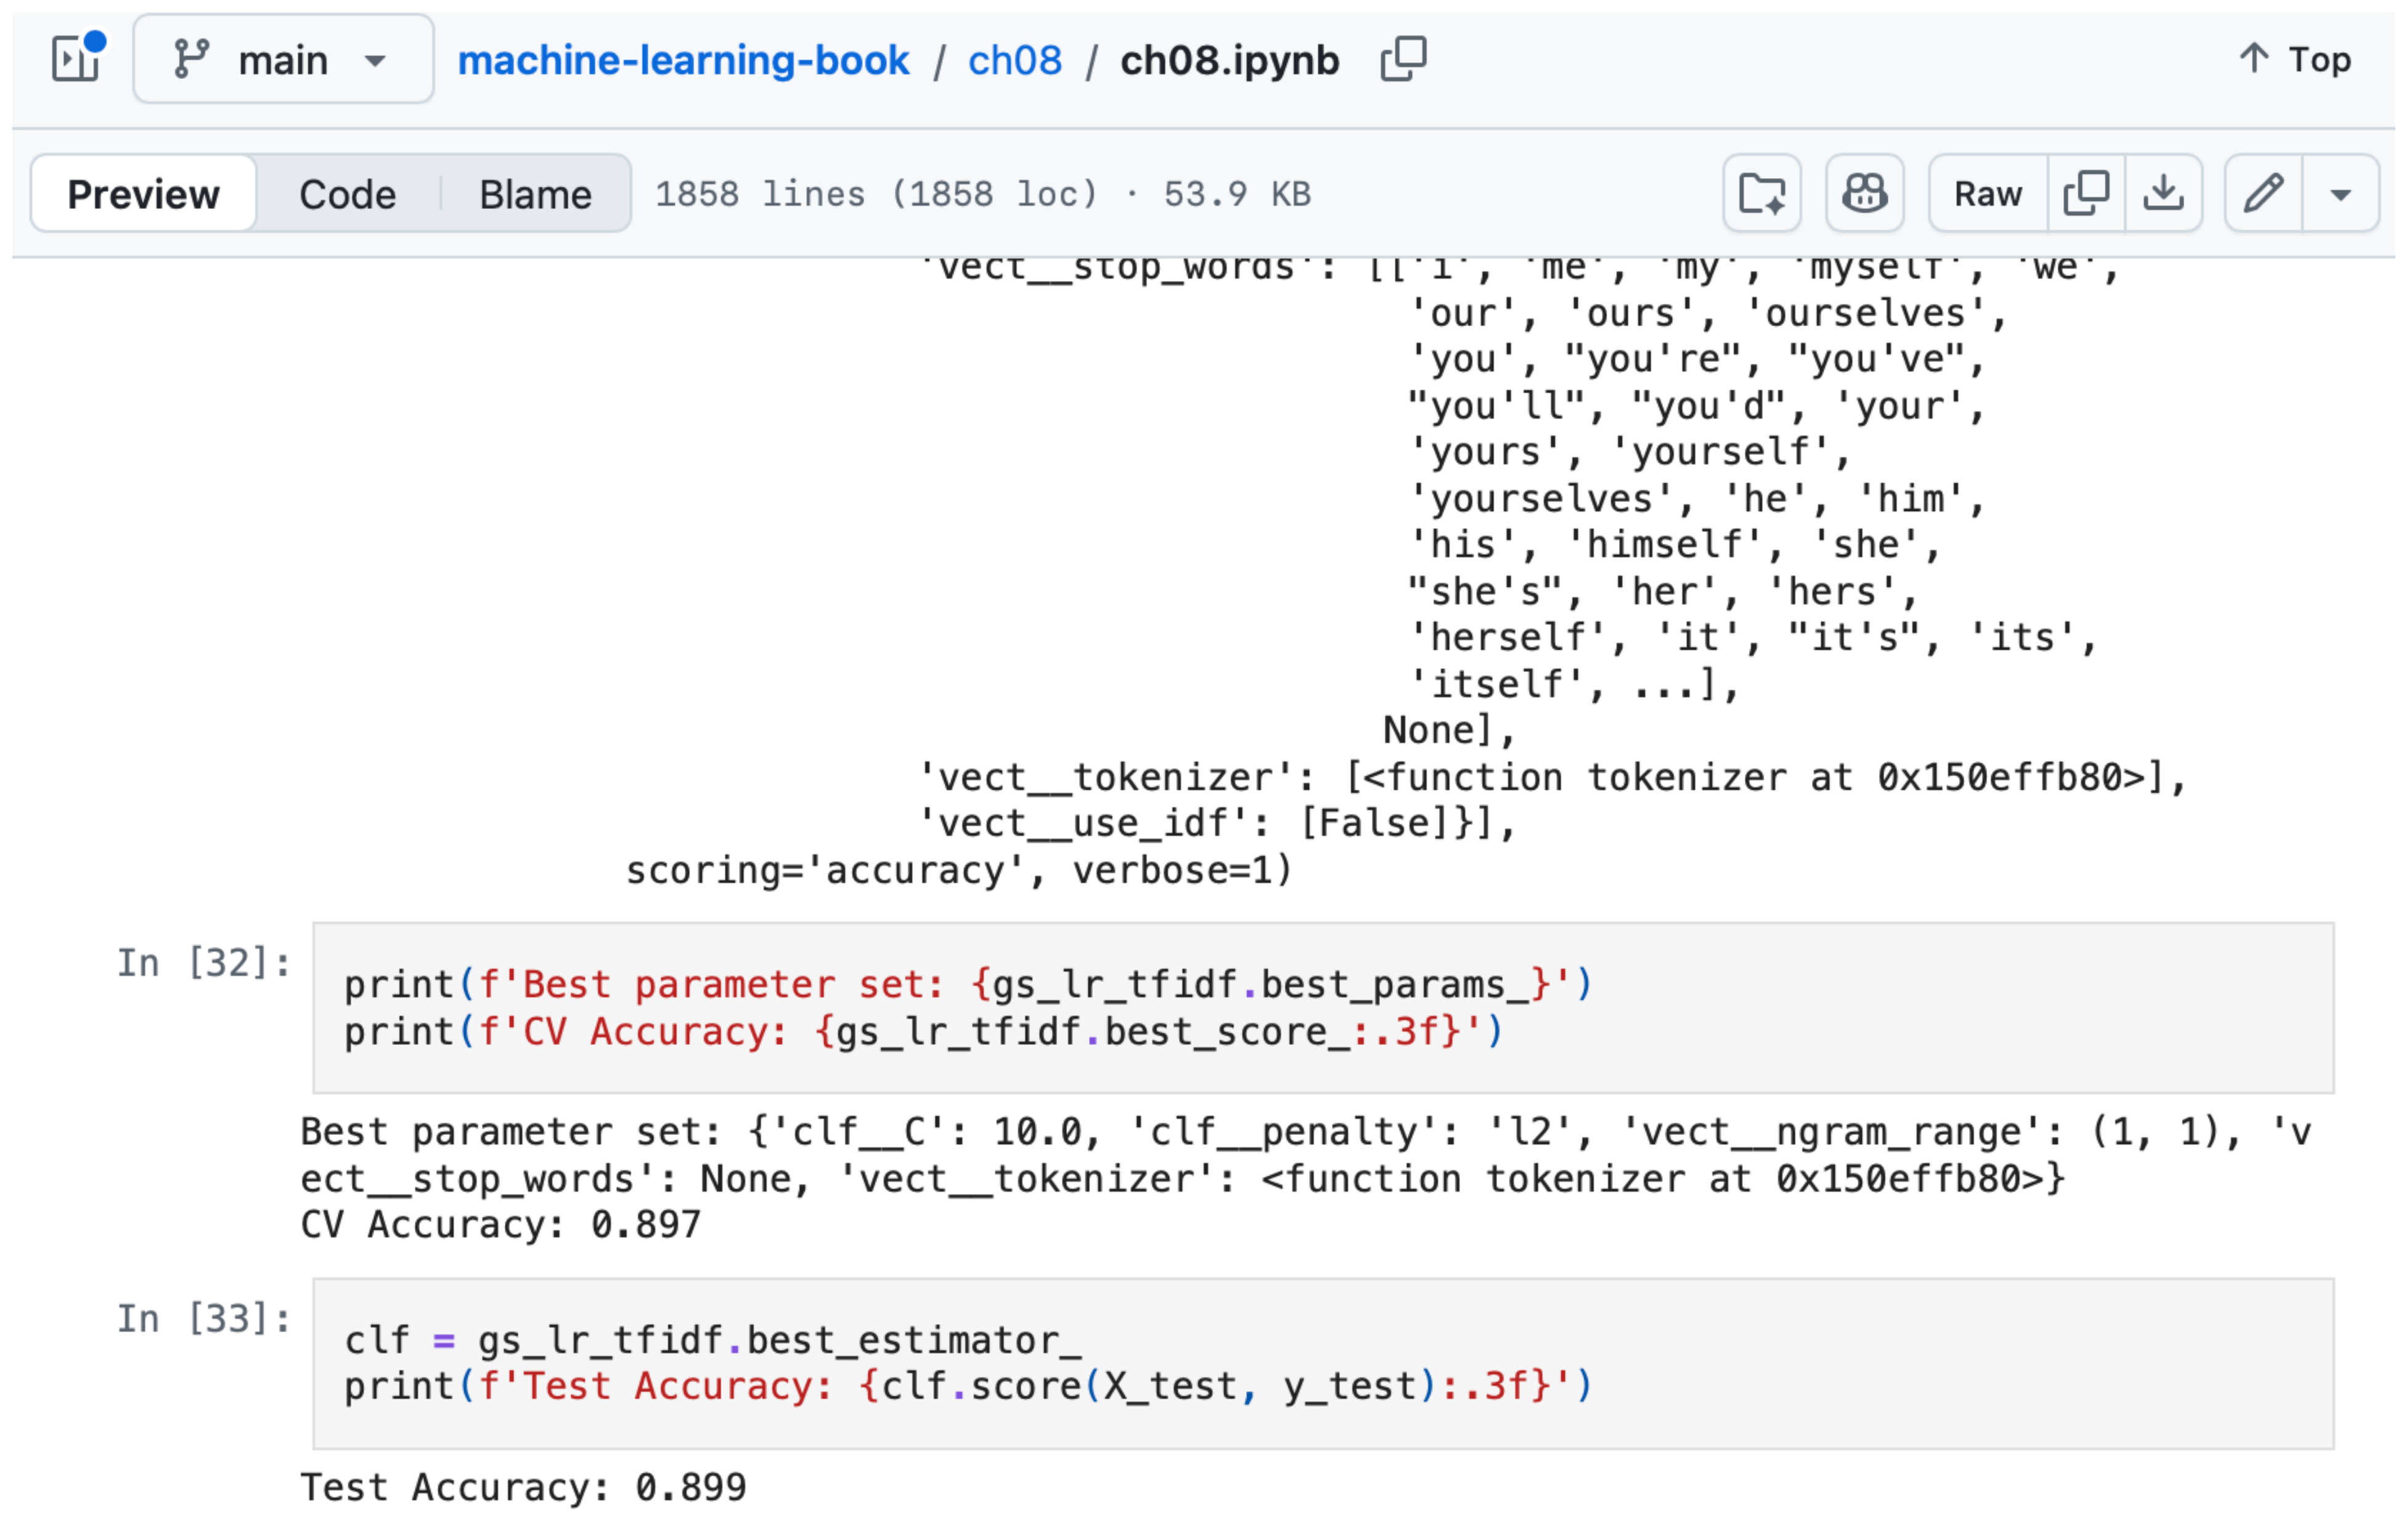
Despite the shortcomings, I still think that a bag-of-words has its place in certain low-stakes applications because it’s so cheap, and a bag-of-words representation + logistic regression remains my go-to baseline for every text classification problem, since it’s so easy to implement.
1.2 Deep neural networks for text classification
The aforementioned bag-of-words model would also work with (simple) deep neural networks, like multilayer perceptrons. But the downside still is that we would lose the sentence structure and word order.
However, more sophisticated neural network architectures avoid the bag-of-words workaround: convolutional neural networks (CNNs) and recurrent neural networks (RNNs), which can take word embeddings as input.
1.2.1 Word embeddings
First, before feeding the input texts into a model, we have to convert them into a suitable representation. One such representation is bag-of-words. Another is word embedding vectors. The difference is that a bag-of-words vector represents the entire text by counting how often each vocabulary word occurs, while a word embedding represents an individual word as a dense vector of learned numbers.
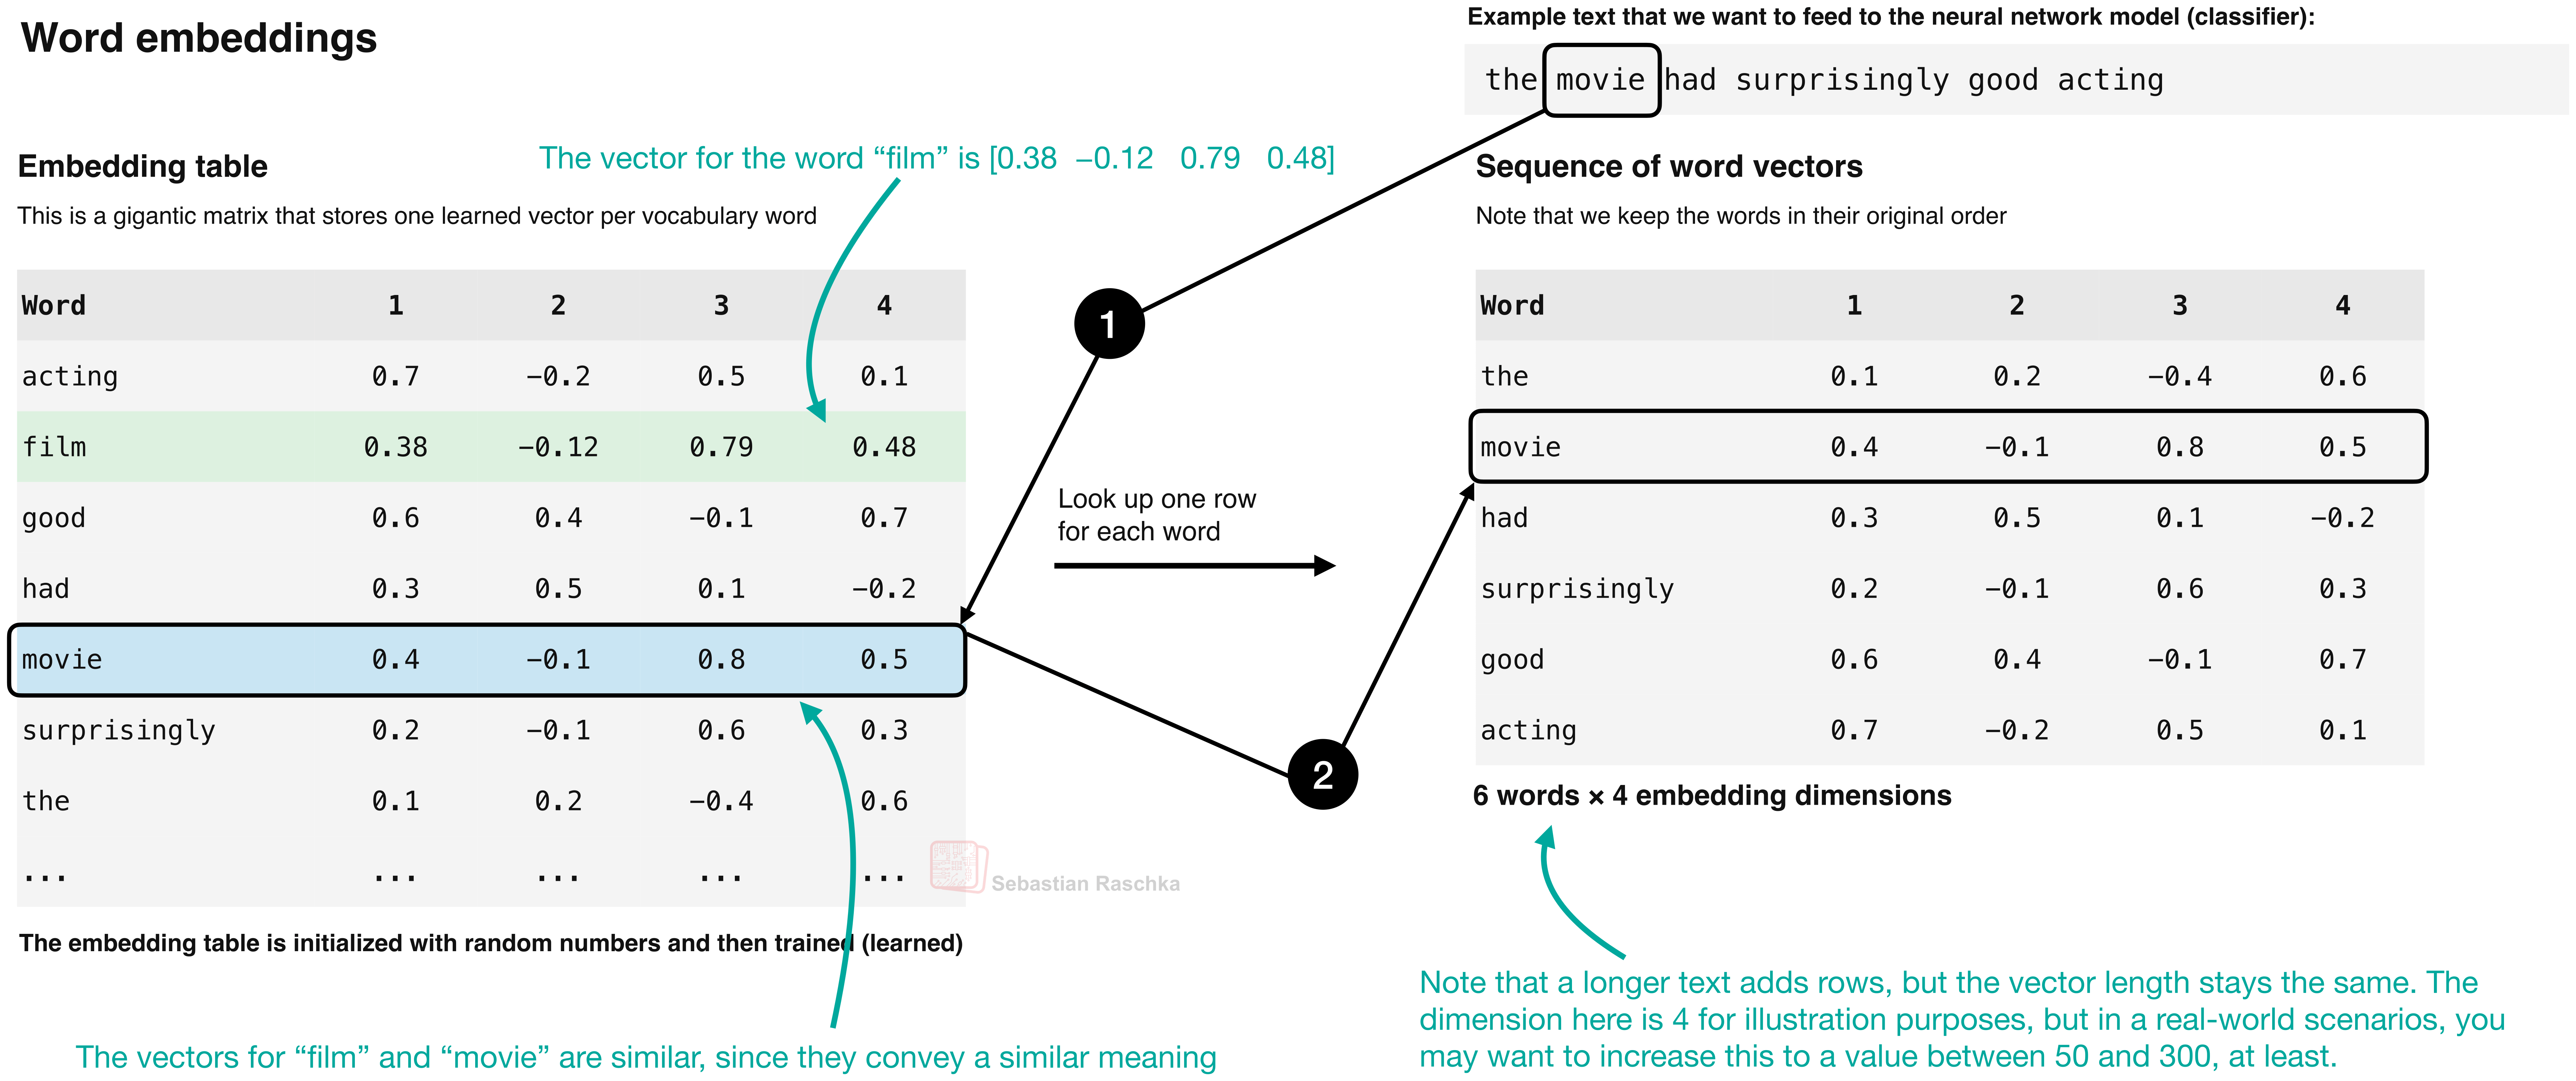
Word embeddings work similarly to embedding layers in LLMs, i.e., they convert input tokens into dense vectors. Embeddings can happen outside the model (e.g., two classic, popular methods for learning them are Word2Vec and GloVe), or the embedding layer can be part of the neural network architecture itself and be learned and tuned during model training.
These classic embeddings are context-independent at lookup time. The word “bank”, for example, gets the same vector in “river bank” and “bank account” (as you may know, context can be handled via concepts like attention).
For additional resources on embeddings, you may find the following ones helpful:
Chapter 2: Working with Text Data (this is an LLM chapter but should give you the gist of embedding words or tokens; in LLM tokenizers, we split words into subword tokens; in Word2Vec, 1 word is usually 1 token.)
Understanding the Difference Between Embedding Layers and Linear Layers (this is an illustration that shows when embedding vectors are mathematically equivalent to Linear layers and matrix multiplications.)
1.2.2 Recurrent neural networks (RNNs)
Since many of you are probably familiar with recurrent neural networks (RNNs), I will keep this section short. RNNs are a classic go-to neural network architecture for natural language processing, and popular variants go back to the 1980s and early 1990s. Transformers, which were introduced in 2017 (and using the attention mechanisms that were first introduced in RNNs; see my Understanding Large Language Models for a brief timeline), then gradually replaced them in many NLP applications.
RNNs read a sequence (like text) one word at a time. At each step, they combine the current word embedding (discussed in the previous section) with a hidden state from the previous step. We can think of the hidden state as a fixed-size vector that summarizes the text processed so far, so this makes word order matter, because rearranging the words changes the sequence of state updates.
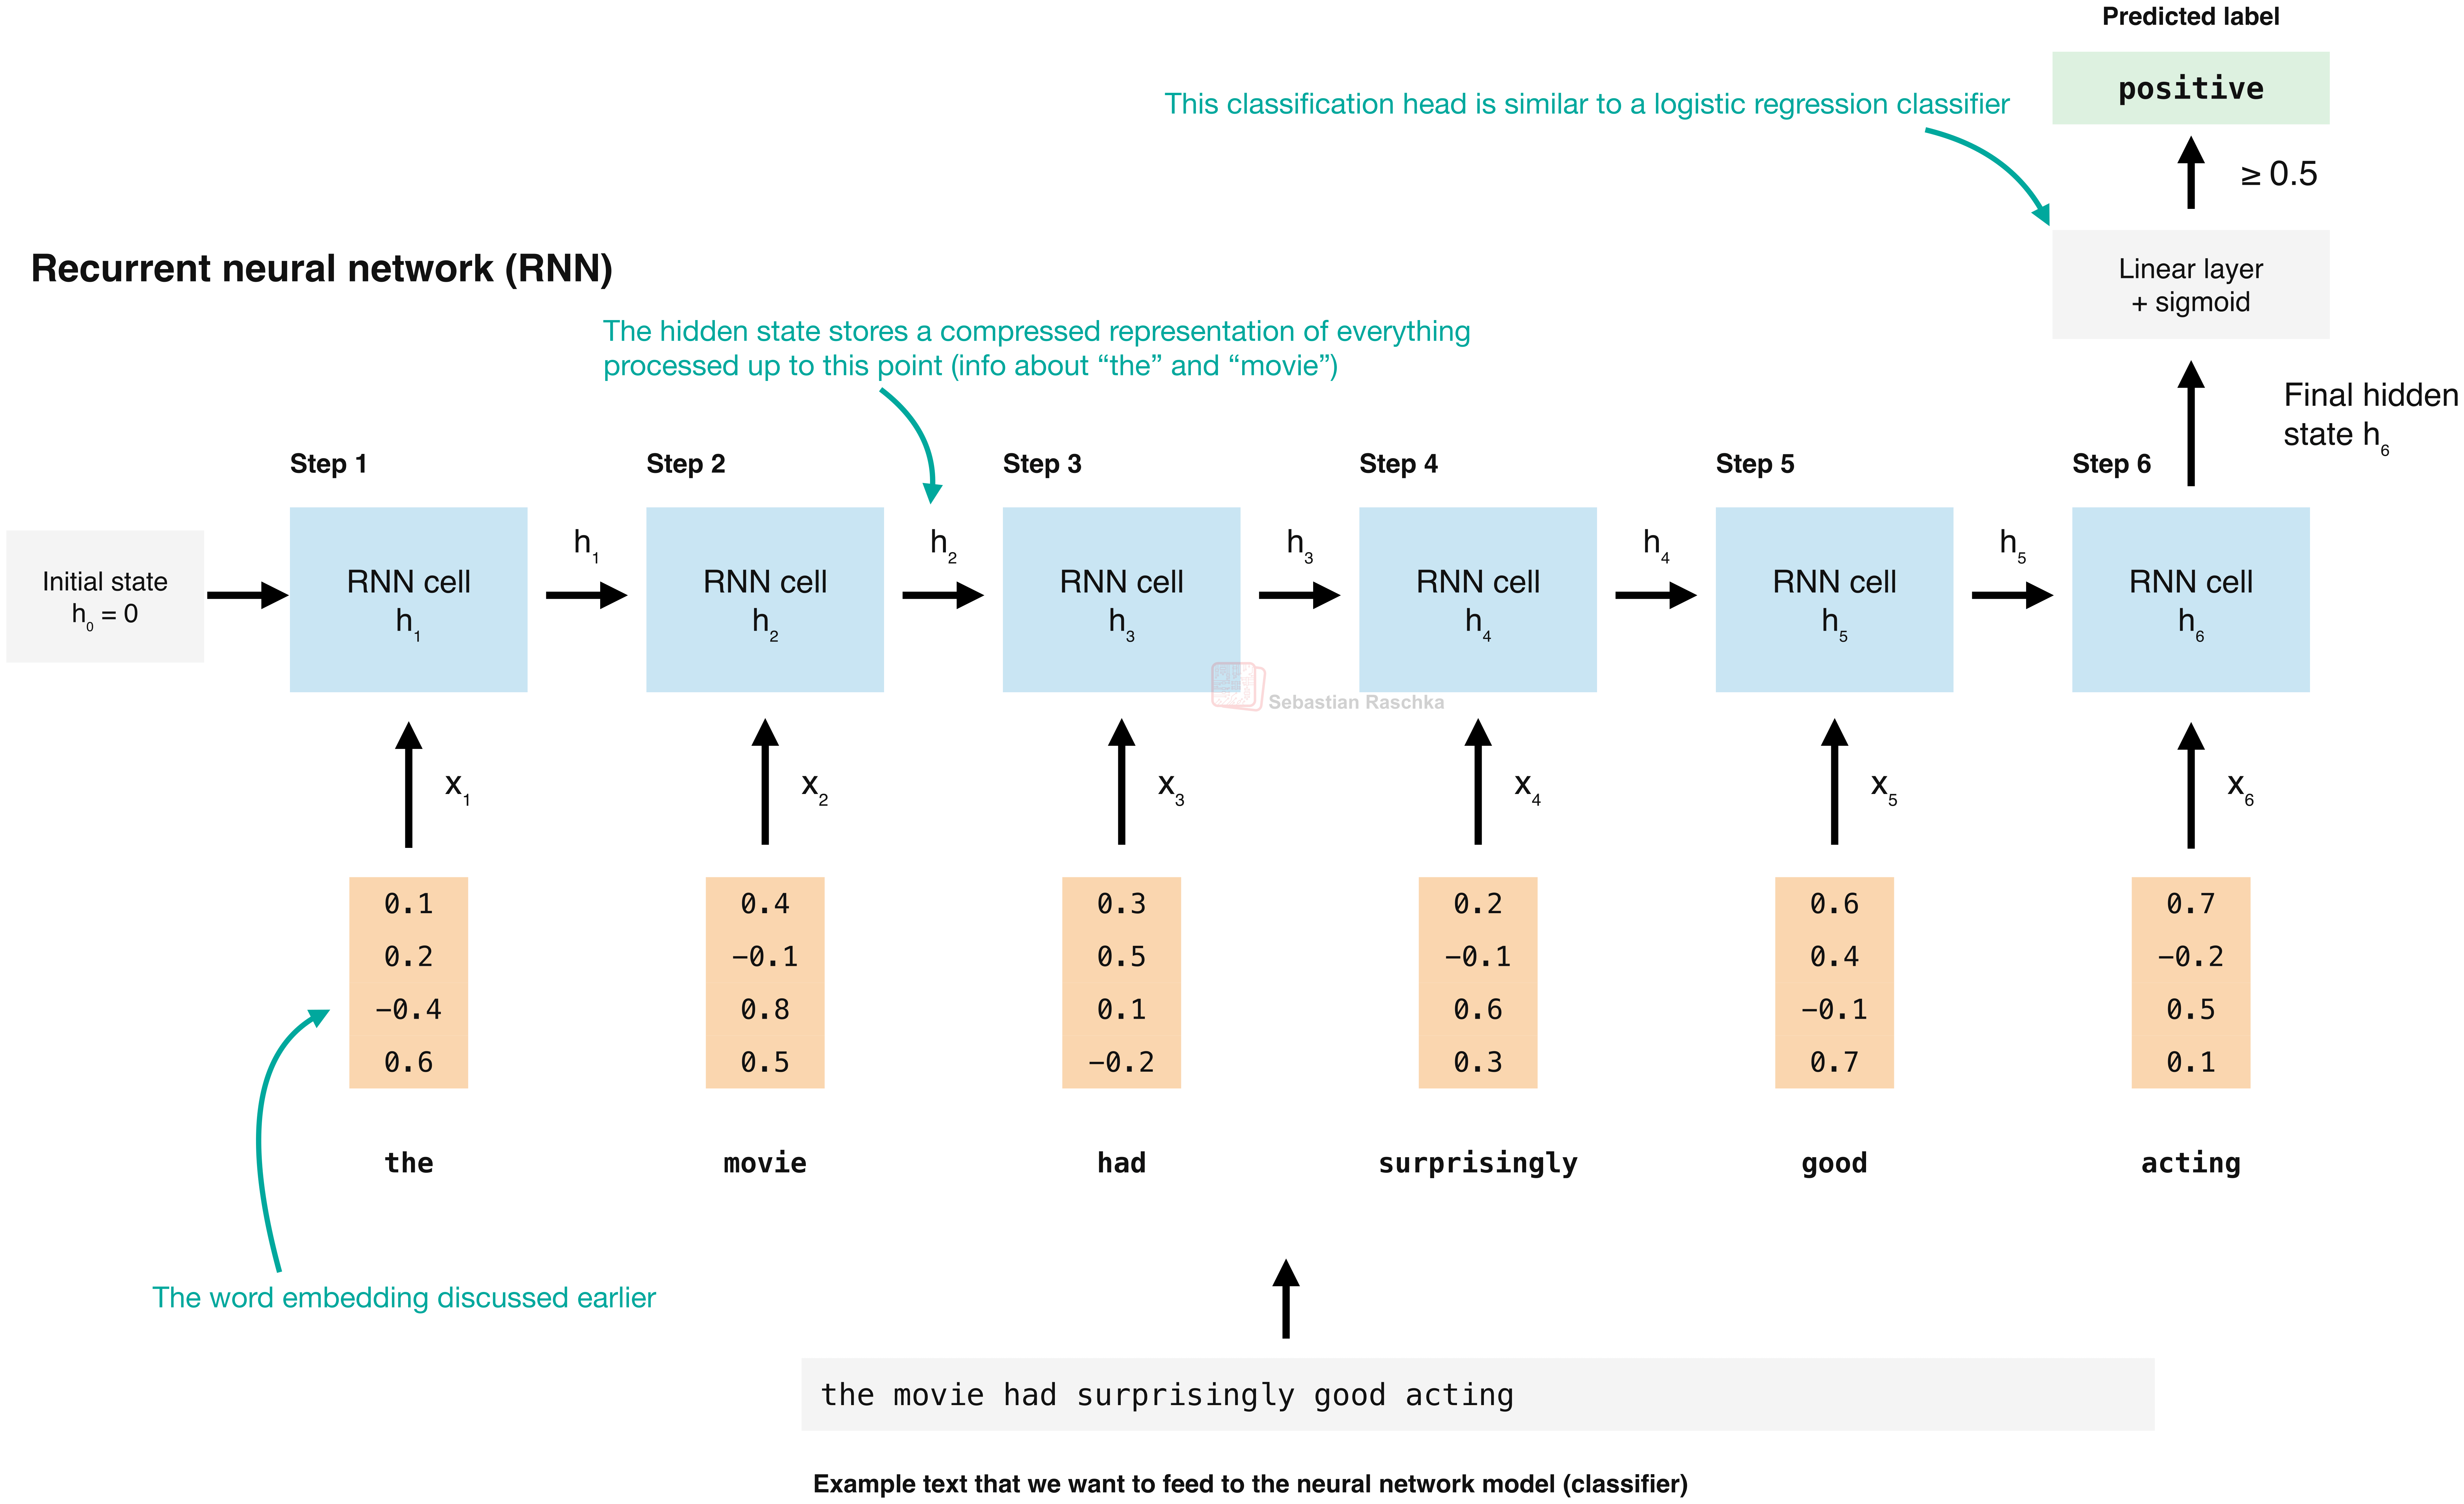
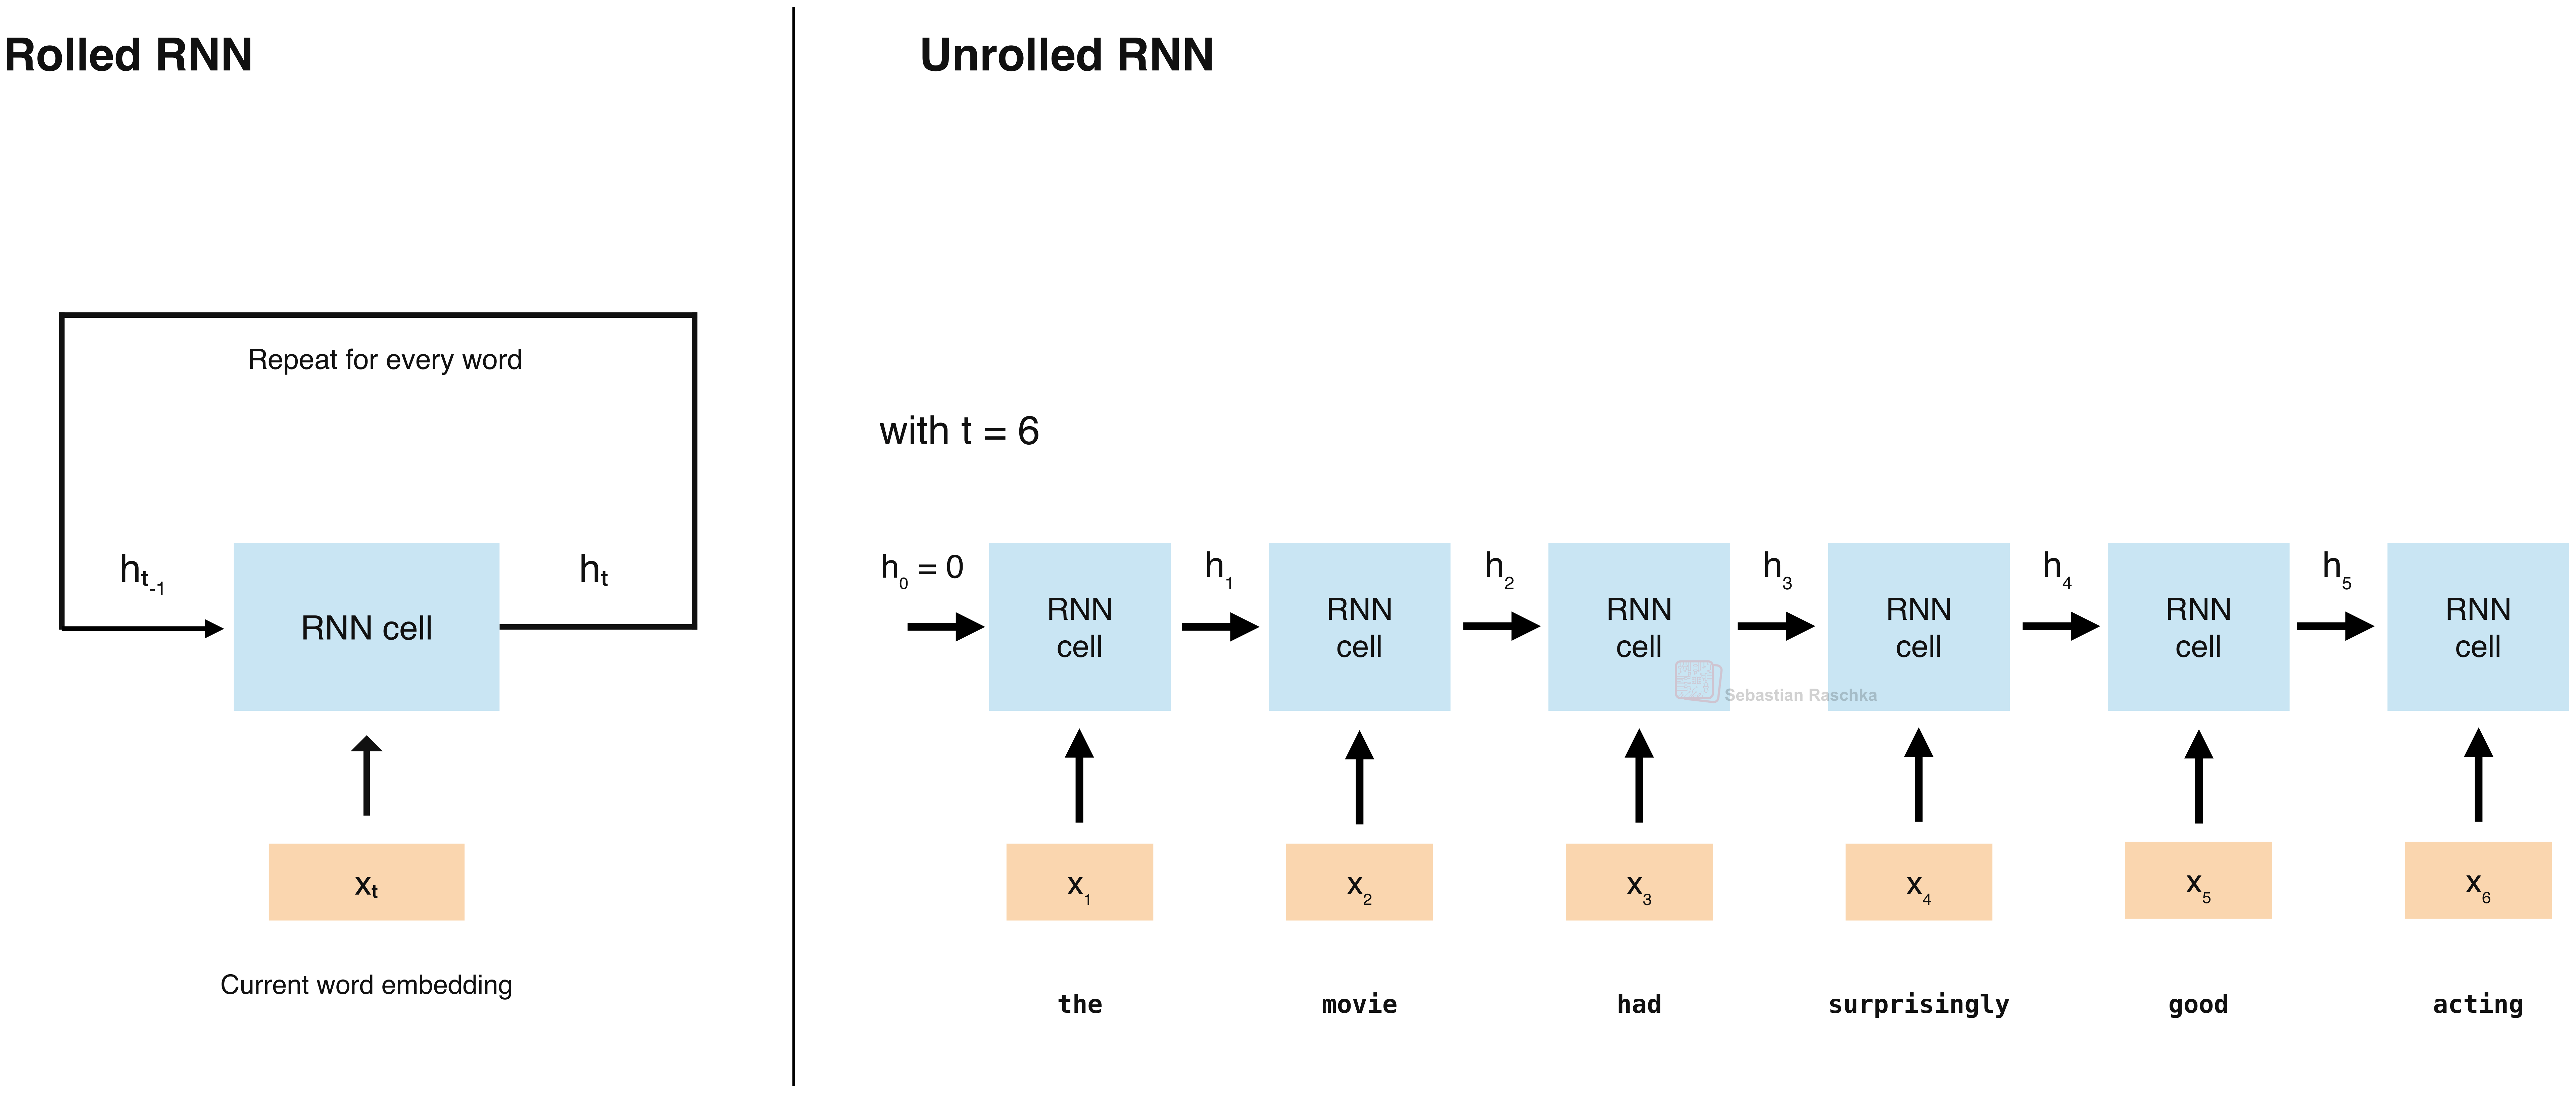
Note that the figure above shows the RNN in the unrolled representation. I.e., the RNN reuses the same layer stack for each input, hence the term “recurrent”. And since it’s “recurrent”, the input text can have an arbitrary length. The figure below illustrates the “recurrence” with the unrolled representation side by side. Note that both show the identical architecture, it’s just a different visualization.
RNNs were notoriously hard to train, and there are important improvements to RNNs, like Long short-term memory (LSTM) networks, introduced in 1997, and gated recurrent units (GRUs), introduced in 2014, which use learned gates to control how information is retained and updated. (There is also the more recent xLSTM: Extended long short-term memory, introduced in 2024).
Also, state-space models are inspired by this idea of a fixed-size hidden state updated sequentially, which is cheaper than transformer attention. However, the bottleneck is still how much information the hidden state can retain, and it still has to be processed sequentially. (Fun fact: attention was first developed for RNNs before the transformer architecture came along, but it’s a story for another time; I’ve written about it in my Understanding Large Language Models article.)
The bottom line is that RNNs can be used to train text classifiers. Coming back to the IMDb movie review dataset, the bag-of-words classifier with logistic regression achieved about 89.9% accuracy (on a balanced dataset), while an LSTM RNN achieved only 85.66% accuracy. Yes, RNNs can be harder to train (stay tuned for the ULMFiT method below, which trains an RNN with much higher accuracy).
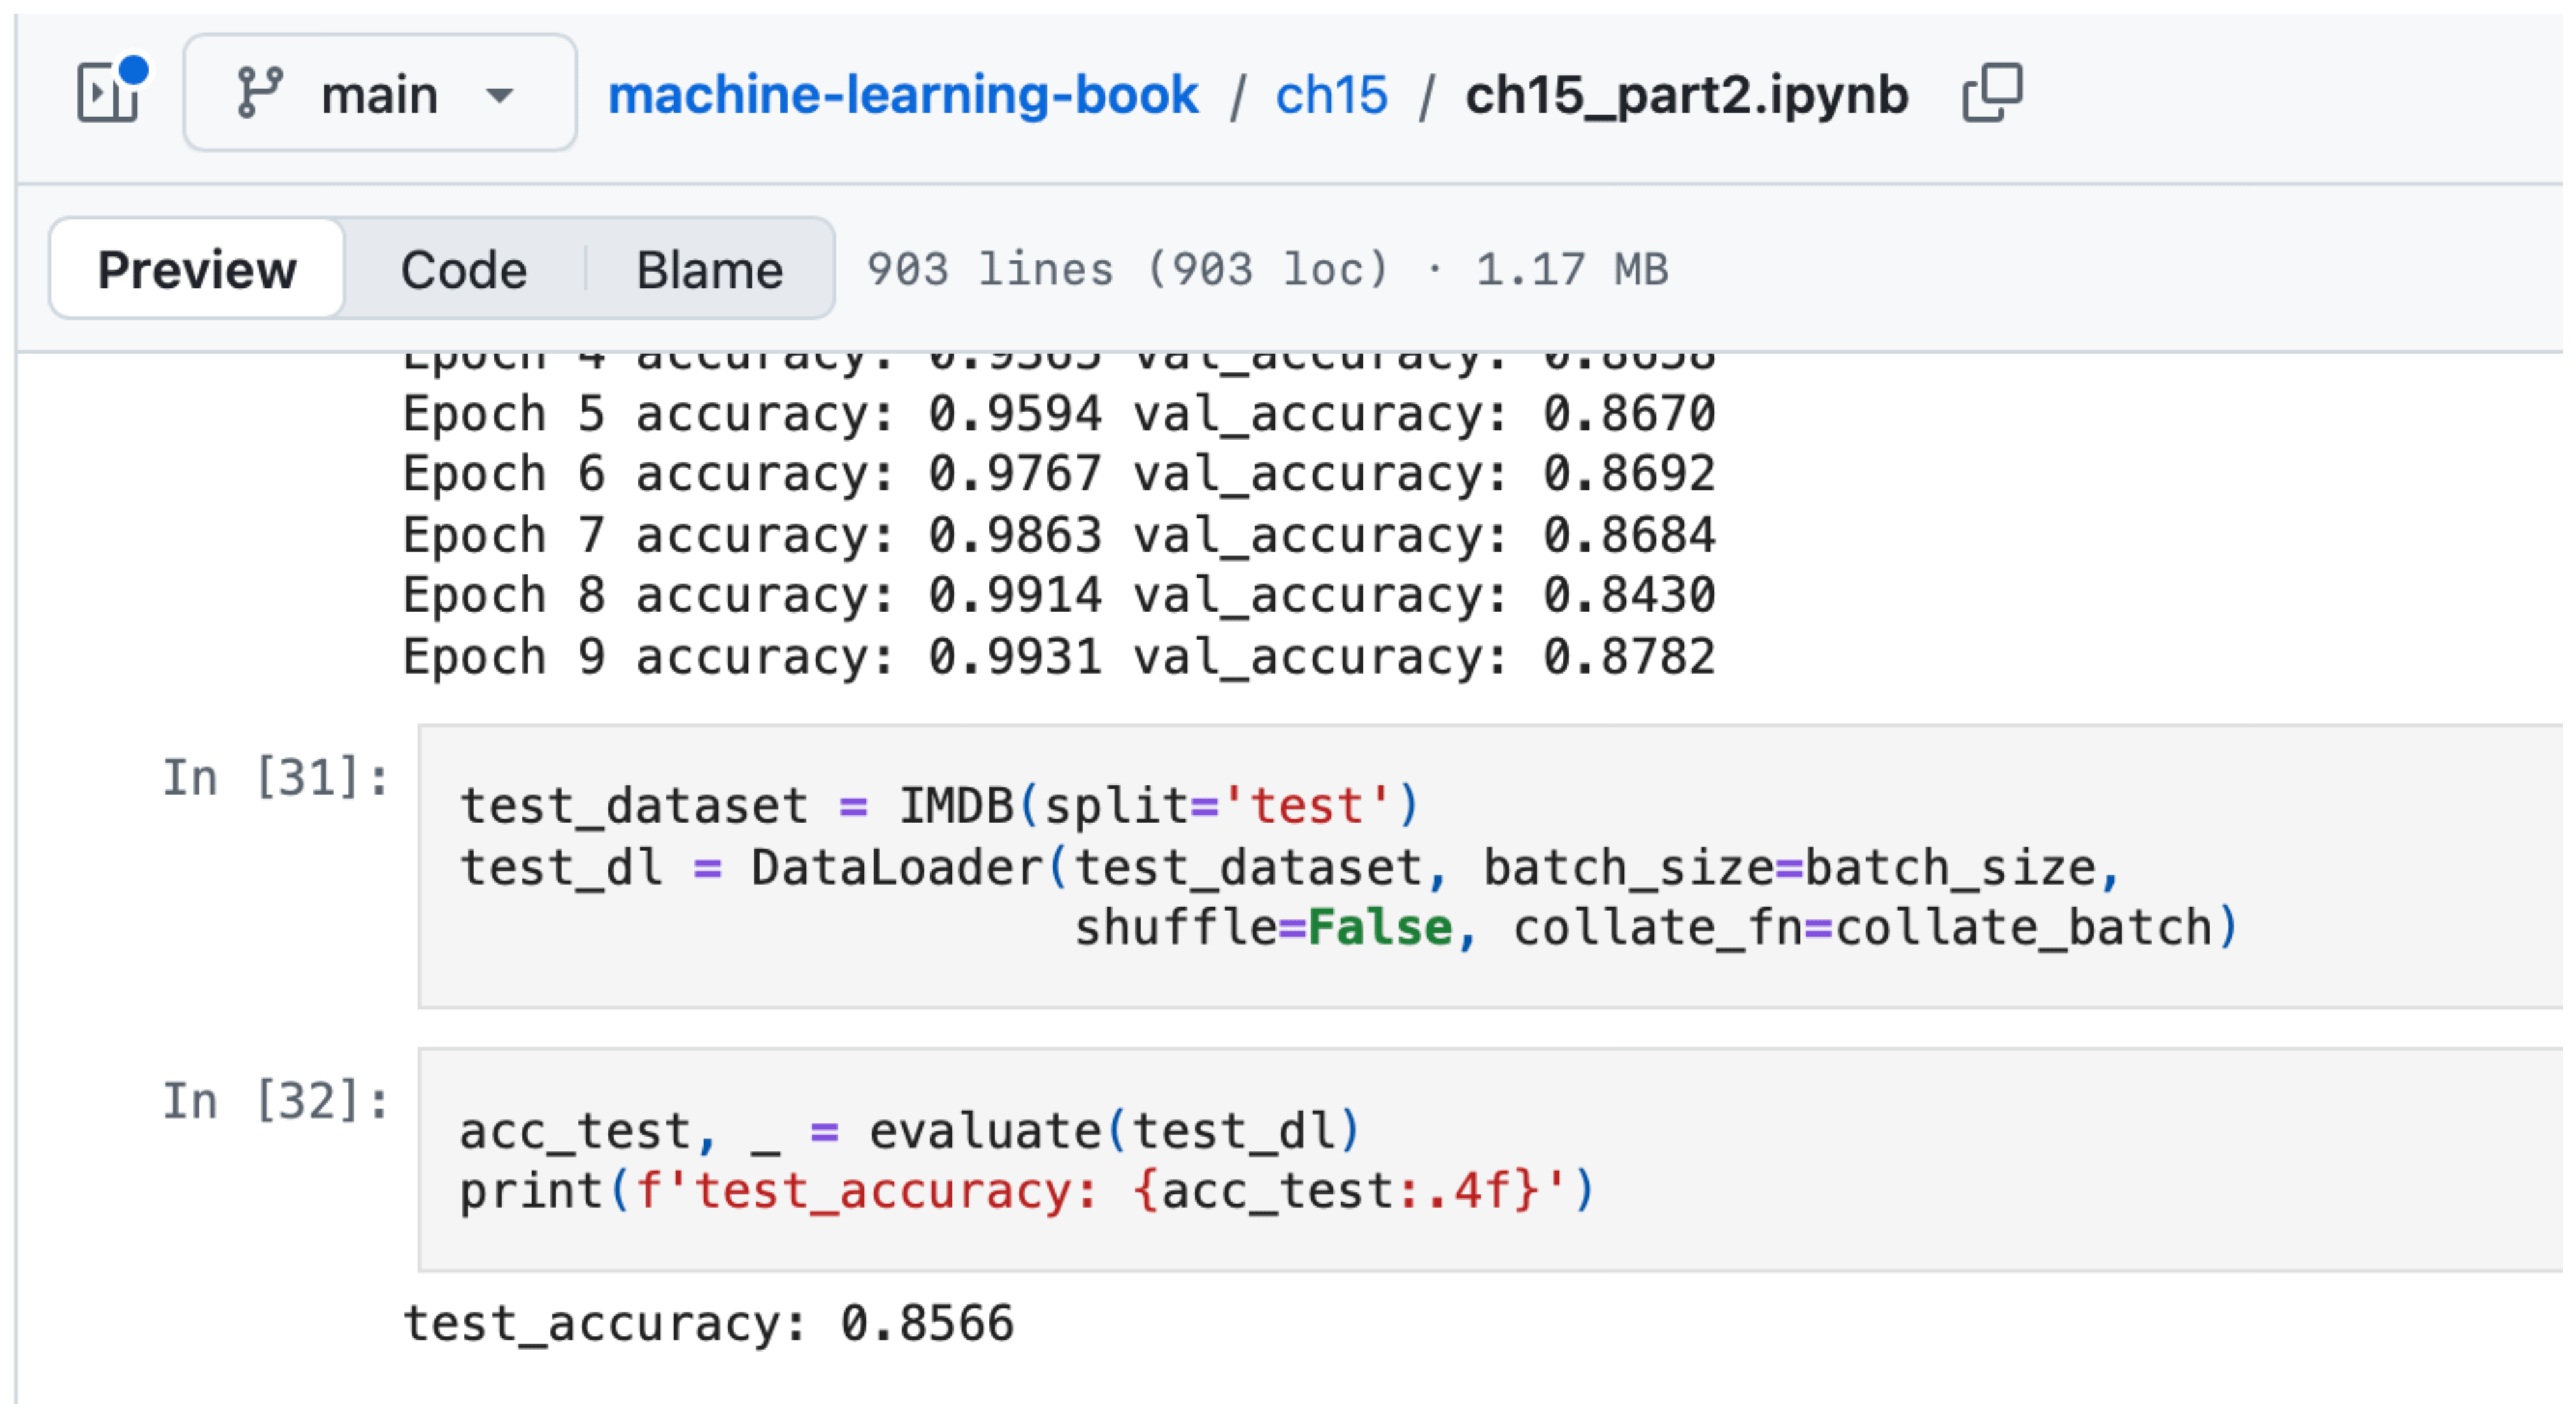
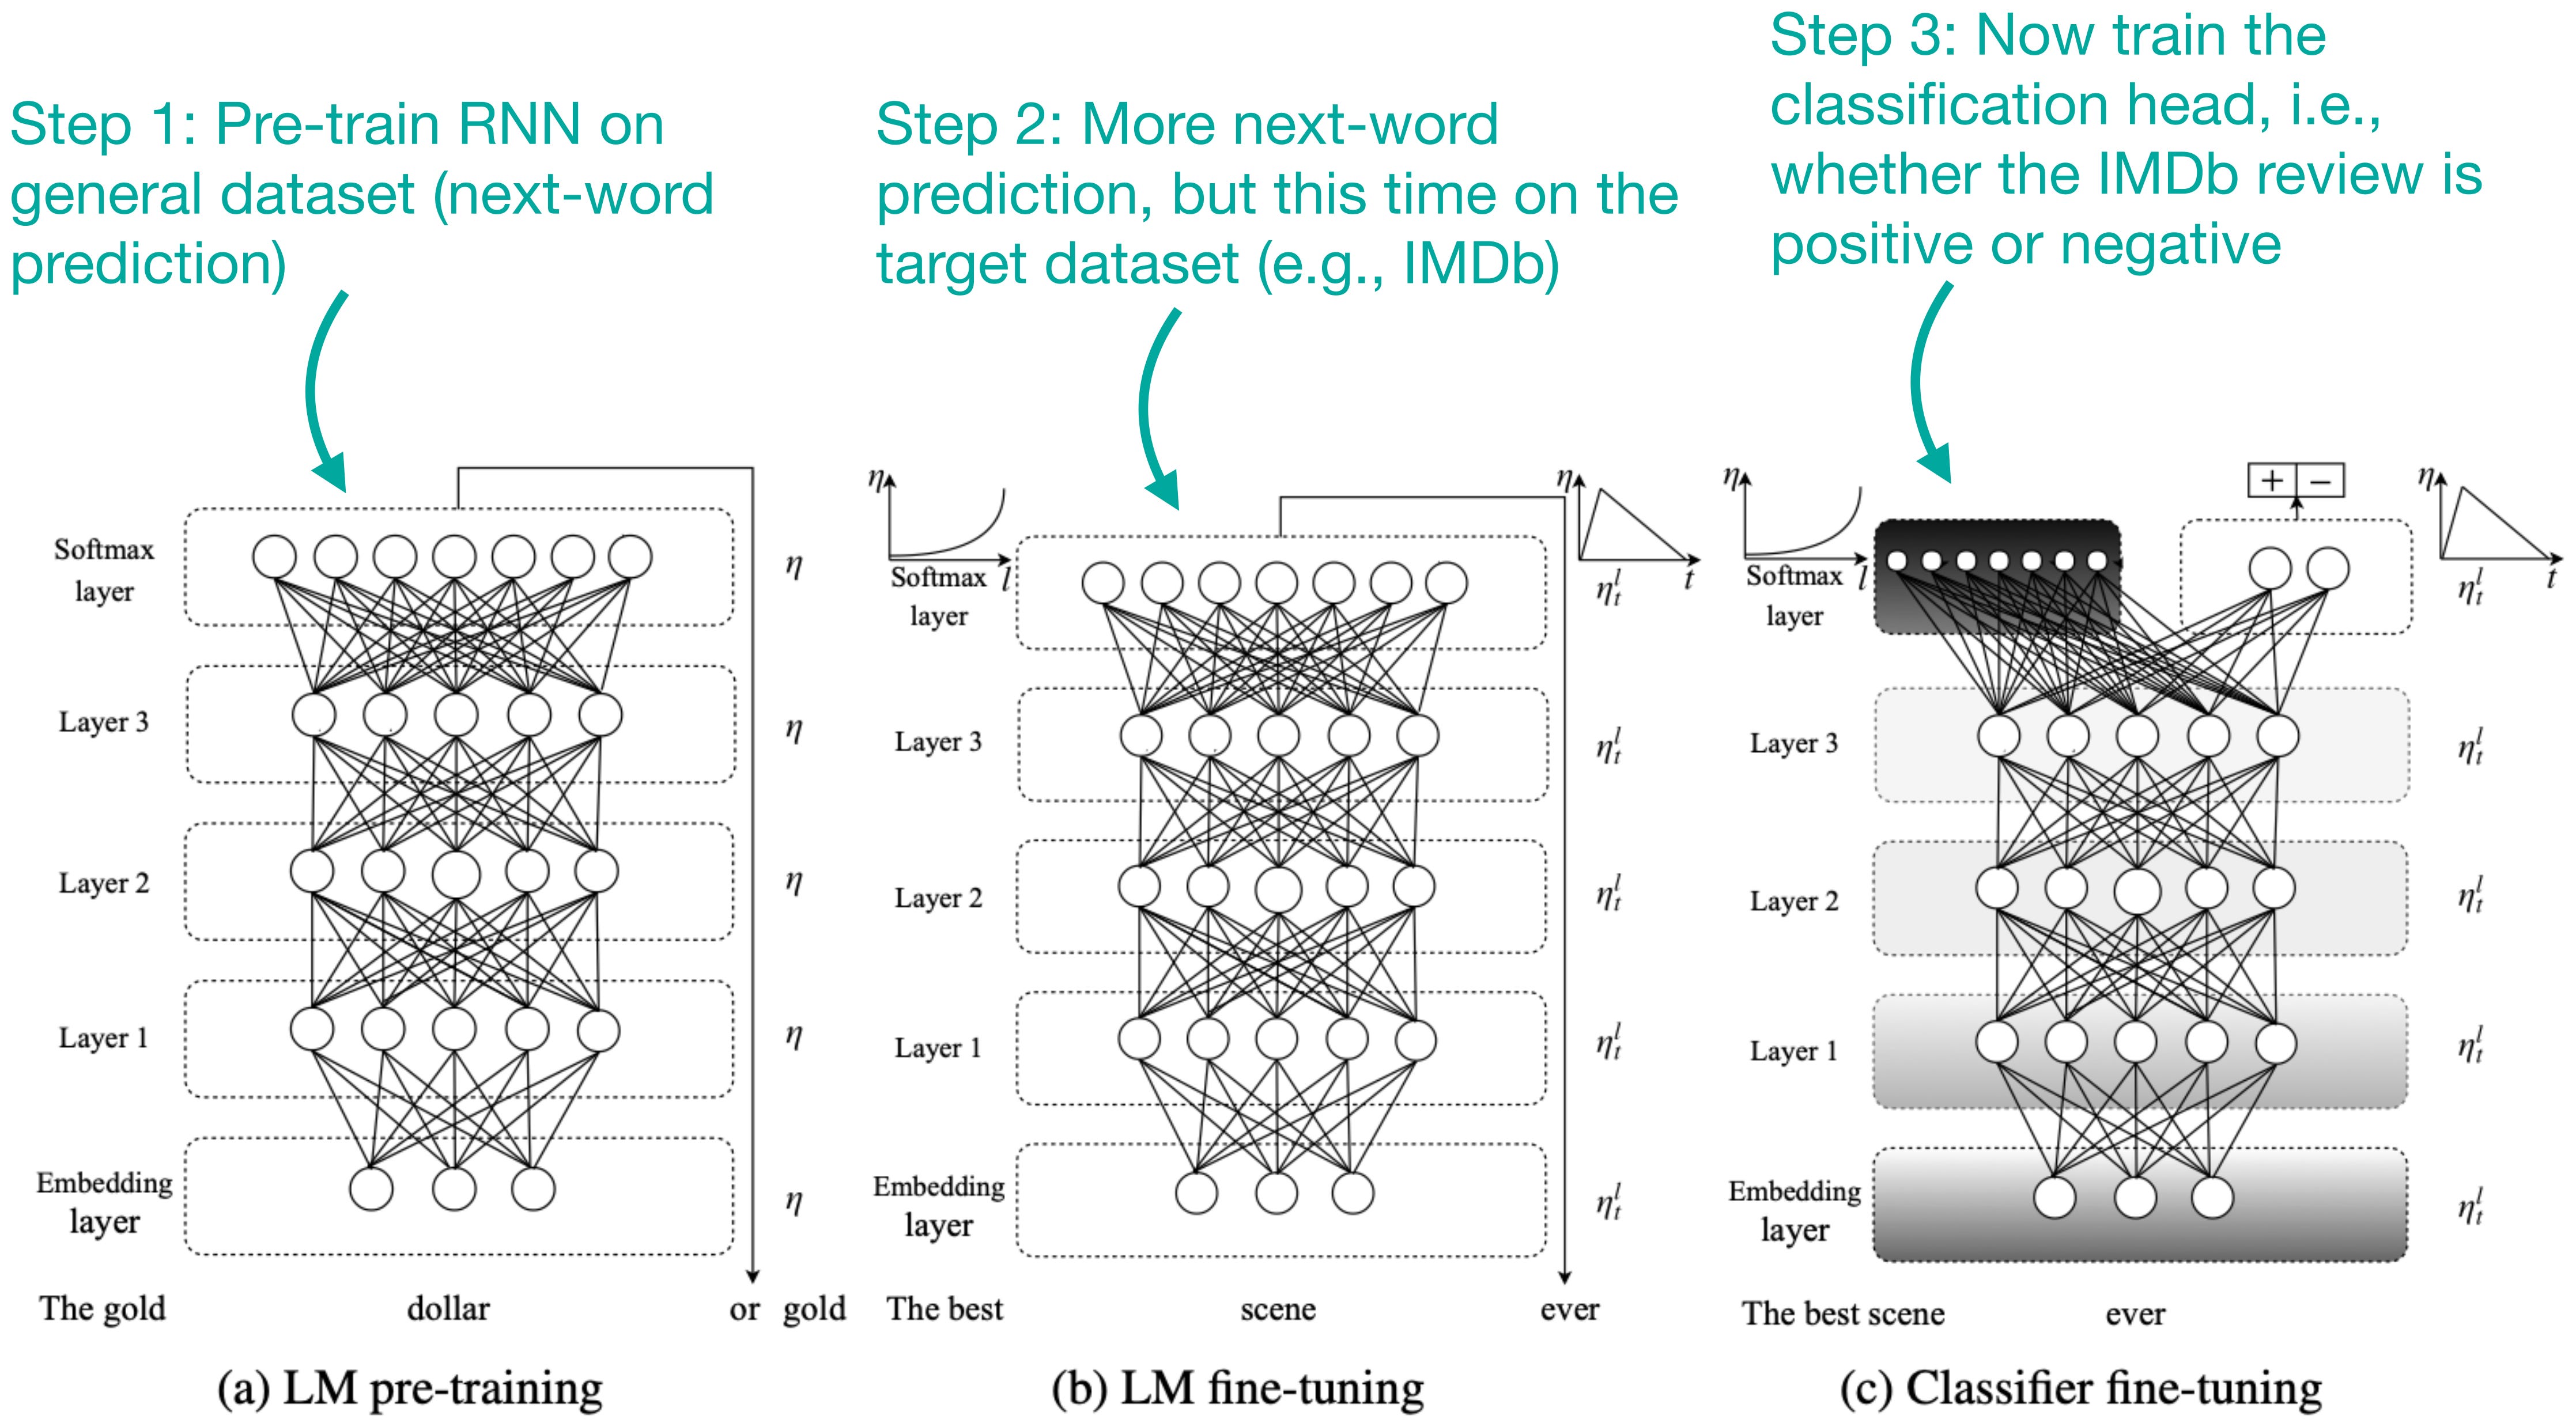
Note that this RNN was trained from scratch. A better approach is to pre-train the model on a larger dataset first, then fine-tune it on this target dataset (classically, we call this approach “transfer learning”).
In the natural language processing domain, one of the most influential papers proposing this approach is ULMFiT (2018), which achieved an impressive 95.4% test accuracy on IMDb.
1.2.3 Convolutional neural networks (CNNs)
You probably know convolutional neural networks (CNNs) from their use in computer vision. However, it is also possible, although historically less common, to use them for text.
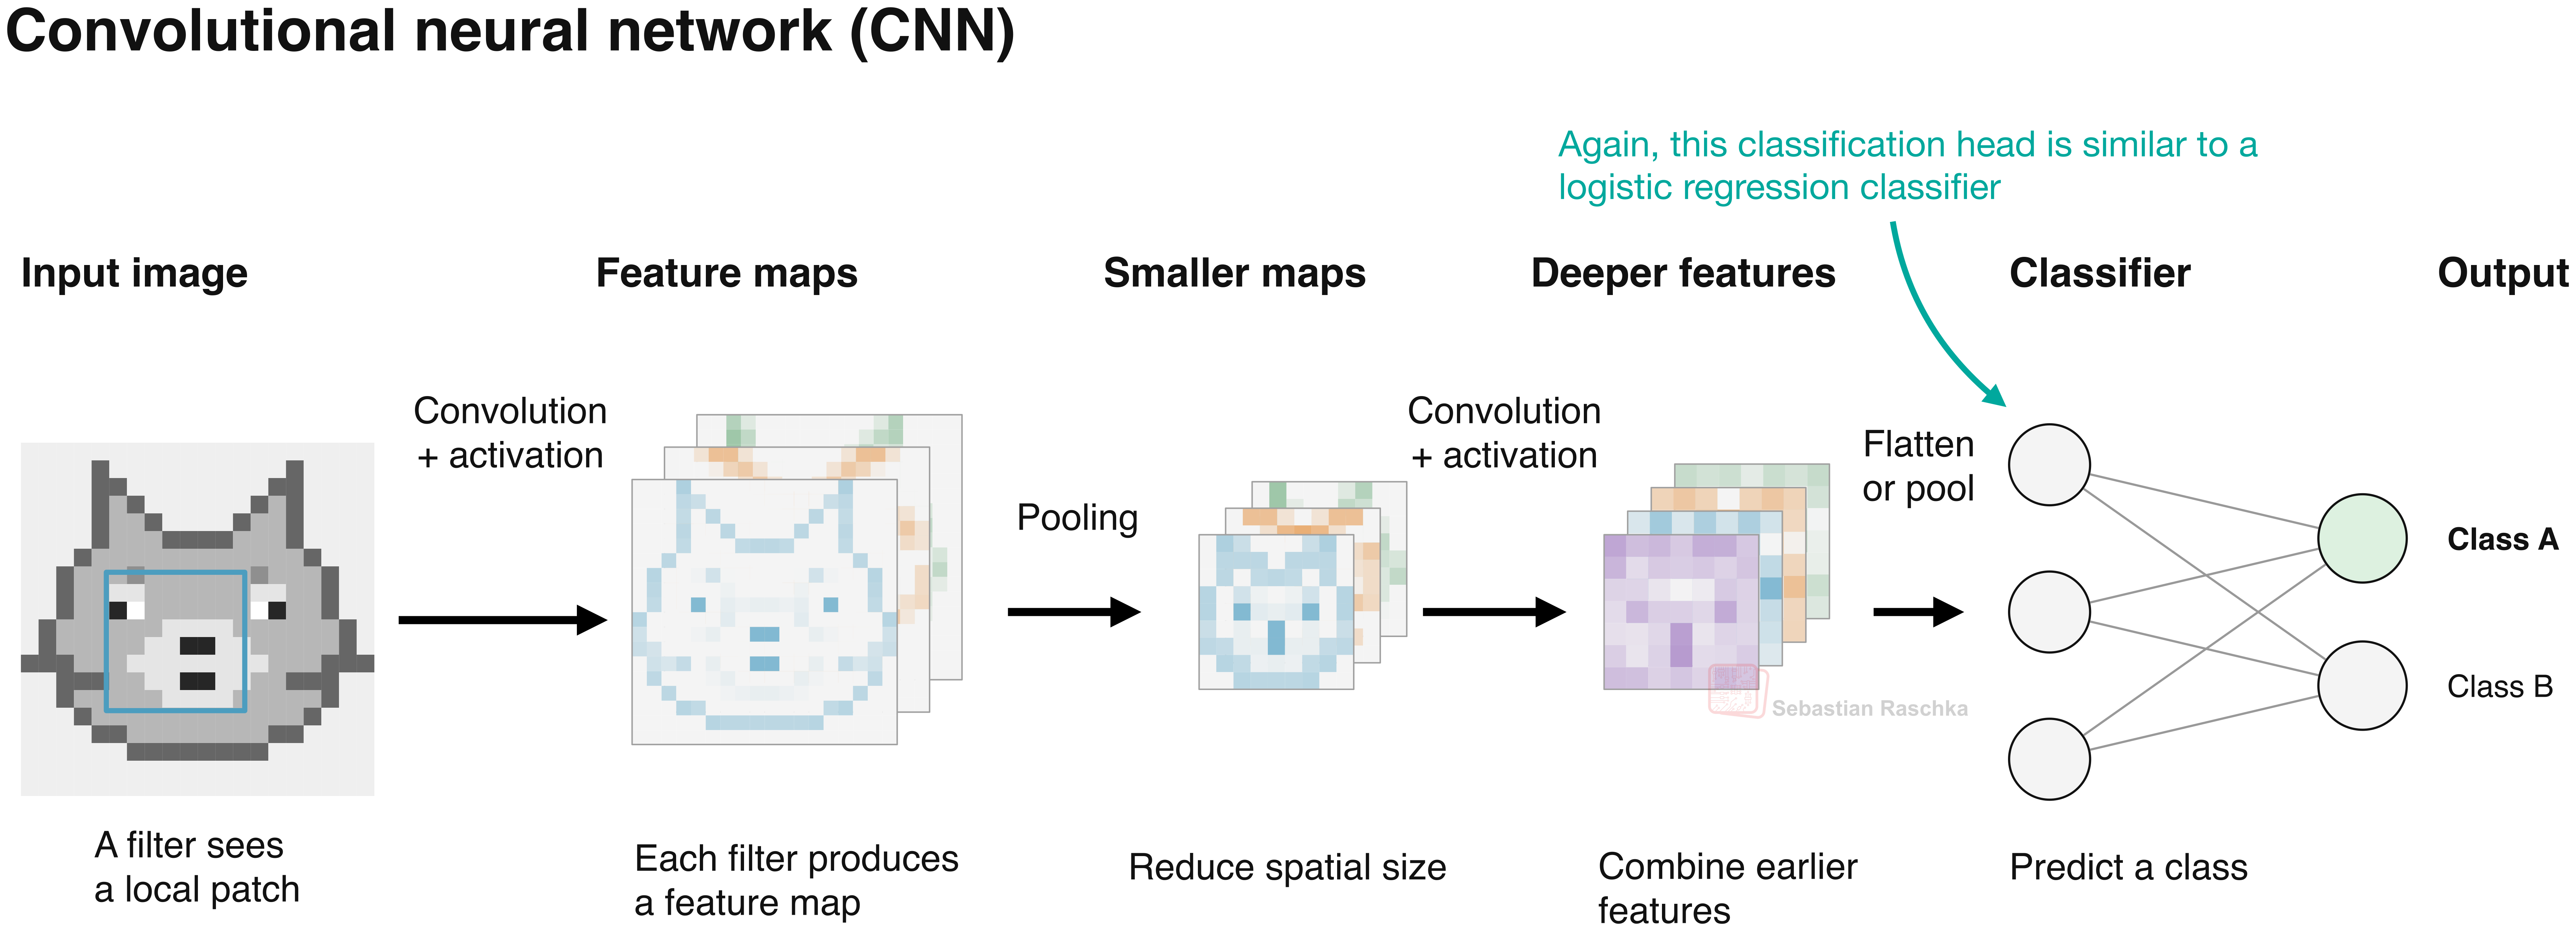
As shown in the image classification example in the figure above, CNNs apply learned filters to image patches (windows). Similarly, in the natural language domain, we can apply learned filters to windows of adjacent word embeddings.
As illustrated in the figure above, a convolutional filter with a window size of three uses the same weights for each adjacent group of three words. Then, as it slides over the inputs, it moves the filter one word at a time across “the movie had surprisingly good acting”. So, this gives four windows (ignoring padding for simplicity):
1: “the movie had”
2: “movie had surprisingly”
3: “had surprisingly good”
4: “surprisingly good acting”
So, in the last layer, before the classification head, we can either flatten or global max pool the results before connecting it to the classification head. While flattening preserves all information, it would produce differently sized vectors depending on the text input length. (E.g., if “the movie had surprisingly good acting” were longer, we would have longer feature maps.) So, to make it input-length agnostic, global max-pooling would be a better option here.
In short, we can visualize the text CNN as shown below.
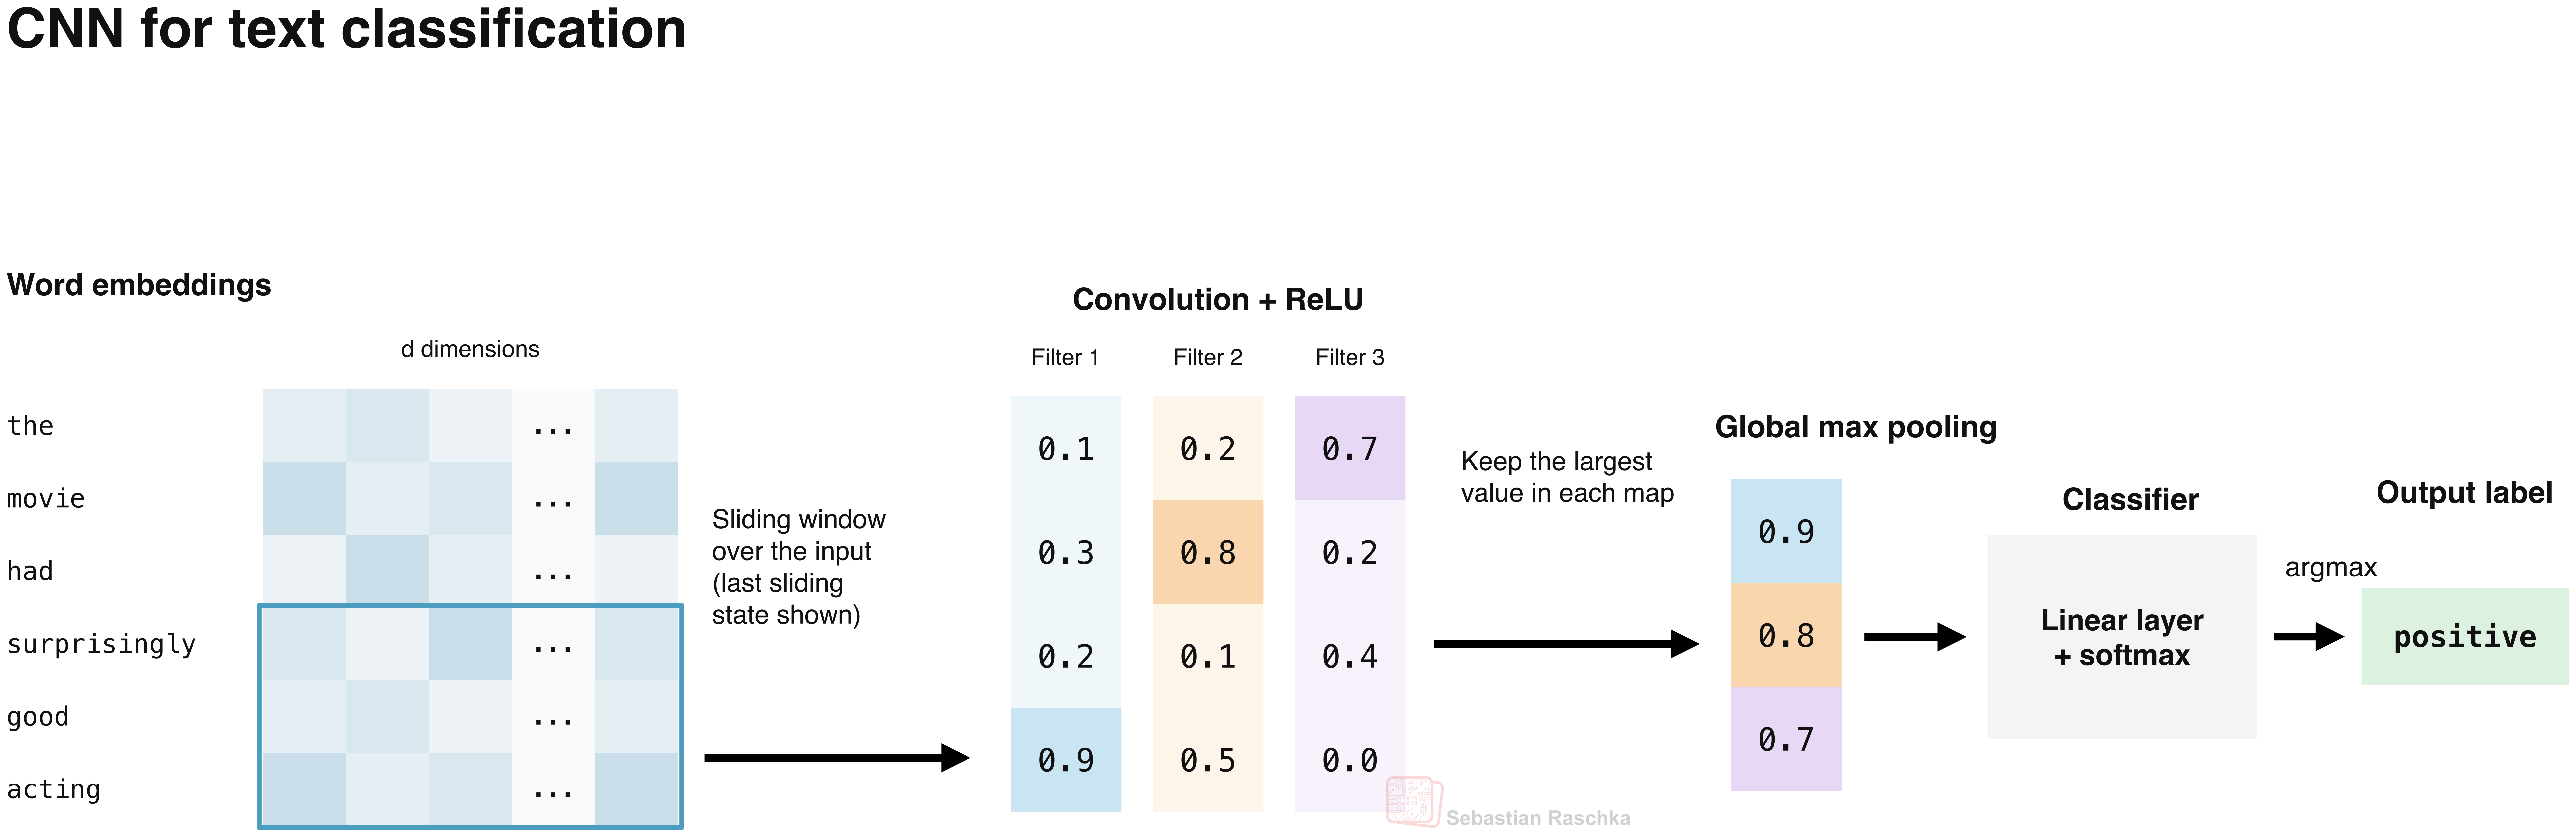
Also, what’s nice is that the filter computations across positions can run in parallel, which avoids the step-by-step dependency of an RNN.
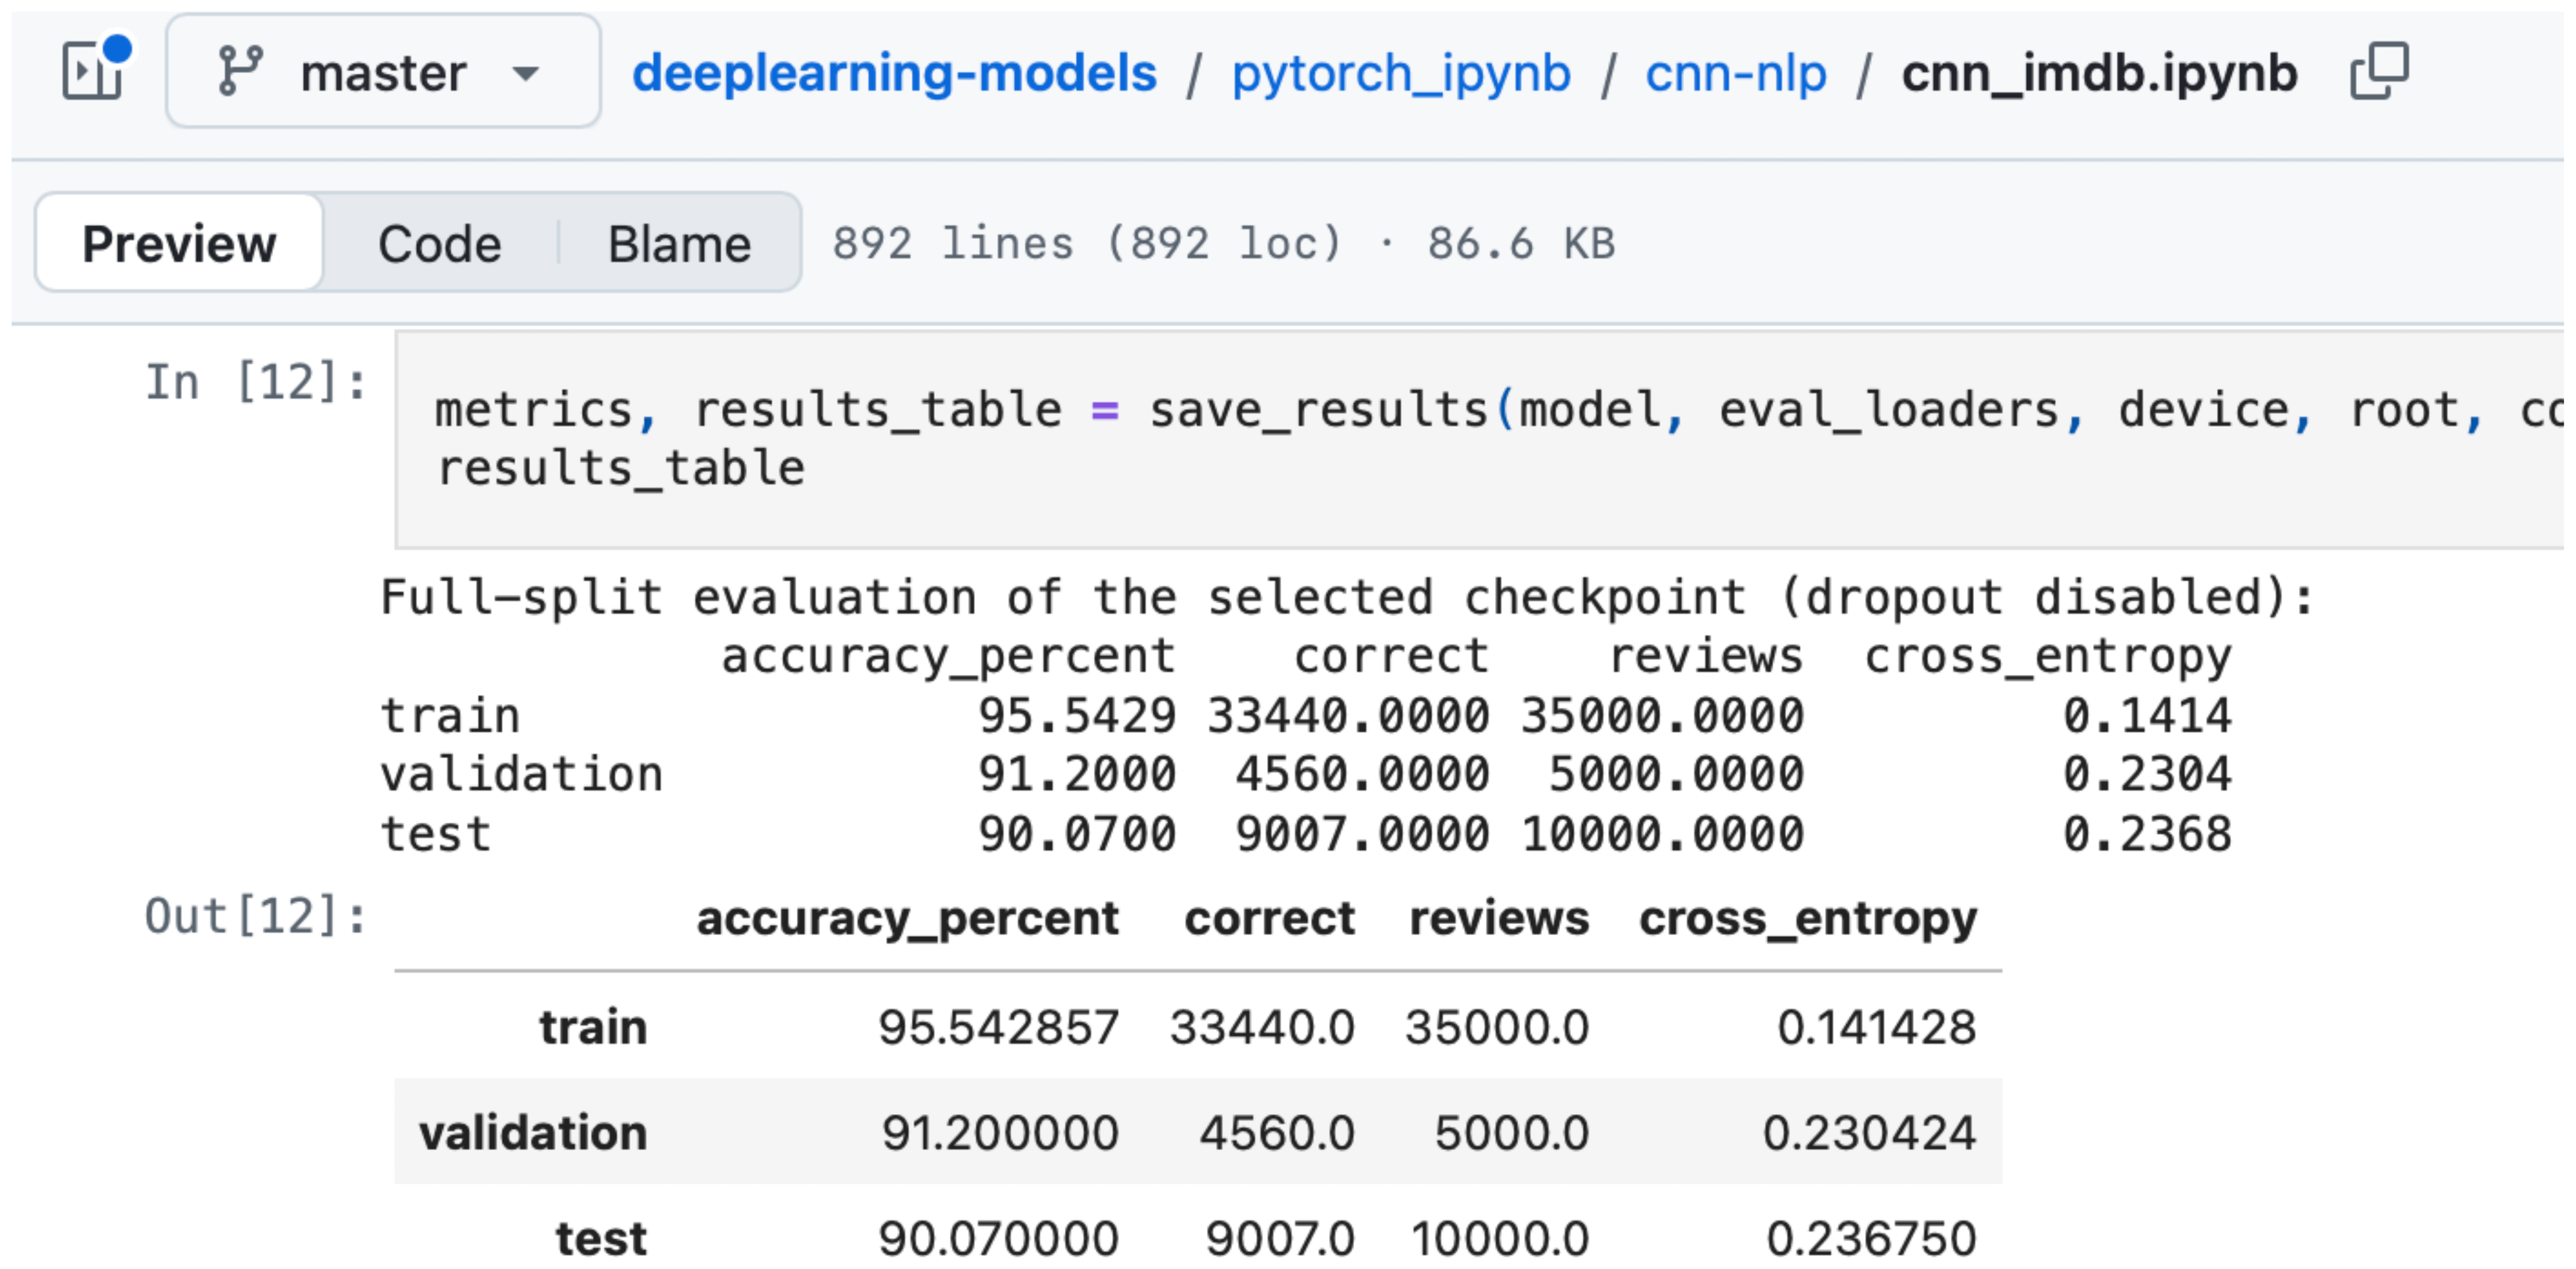
For a quick comparison, on the aforementioned IMDb dataset, my experiments show that such a CNN gets about 90.07% accuracy (but note that this is highly architecture-dependent; for example, you may know from computer vision contexts that accuracies can vary widely). (E.g., the good old AlexNet had a ~62.5% top-1 accuracy on ImageNet, and a ConvNeXt V2-H gets 88.9%.)
2. Transformers
In 2017, the original transformer architecture was introduced in the Attention Is All You Need paper. Since this topic has been covered so extensively (by me and others), I will focus on the classification-relevant aspects. But for those interested in the attention mechanism and other architecture details, please see my related articles:
The key point is that the original transformer architecture was an encoder-decoder setup used for language translation, but it can be easily adapted for text classification tasks, as I’ll illustrate in the following sections.
2.1 Encoder-style language models
I remember all too well the first years after the original transformer architecture release. They were pretty much defined by the rivalry between two different approaches:
Encoder-style models like BERT, primarily developed by Google;
Decoder-style models like GPT, primarily developed by OpenAI.
Encoder-style models were natural text classifiers, whereas GPT models could do zero- and few-shot classification as an emergent property, but their strength was more in generative tasks.
But let’s start with encoder-style models and how to fine-tune and use them to classify text.
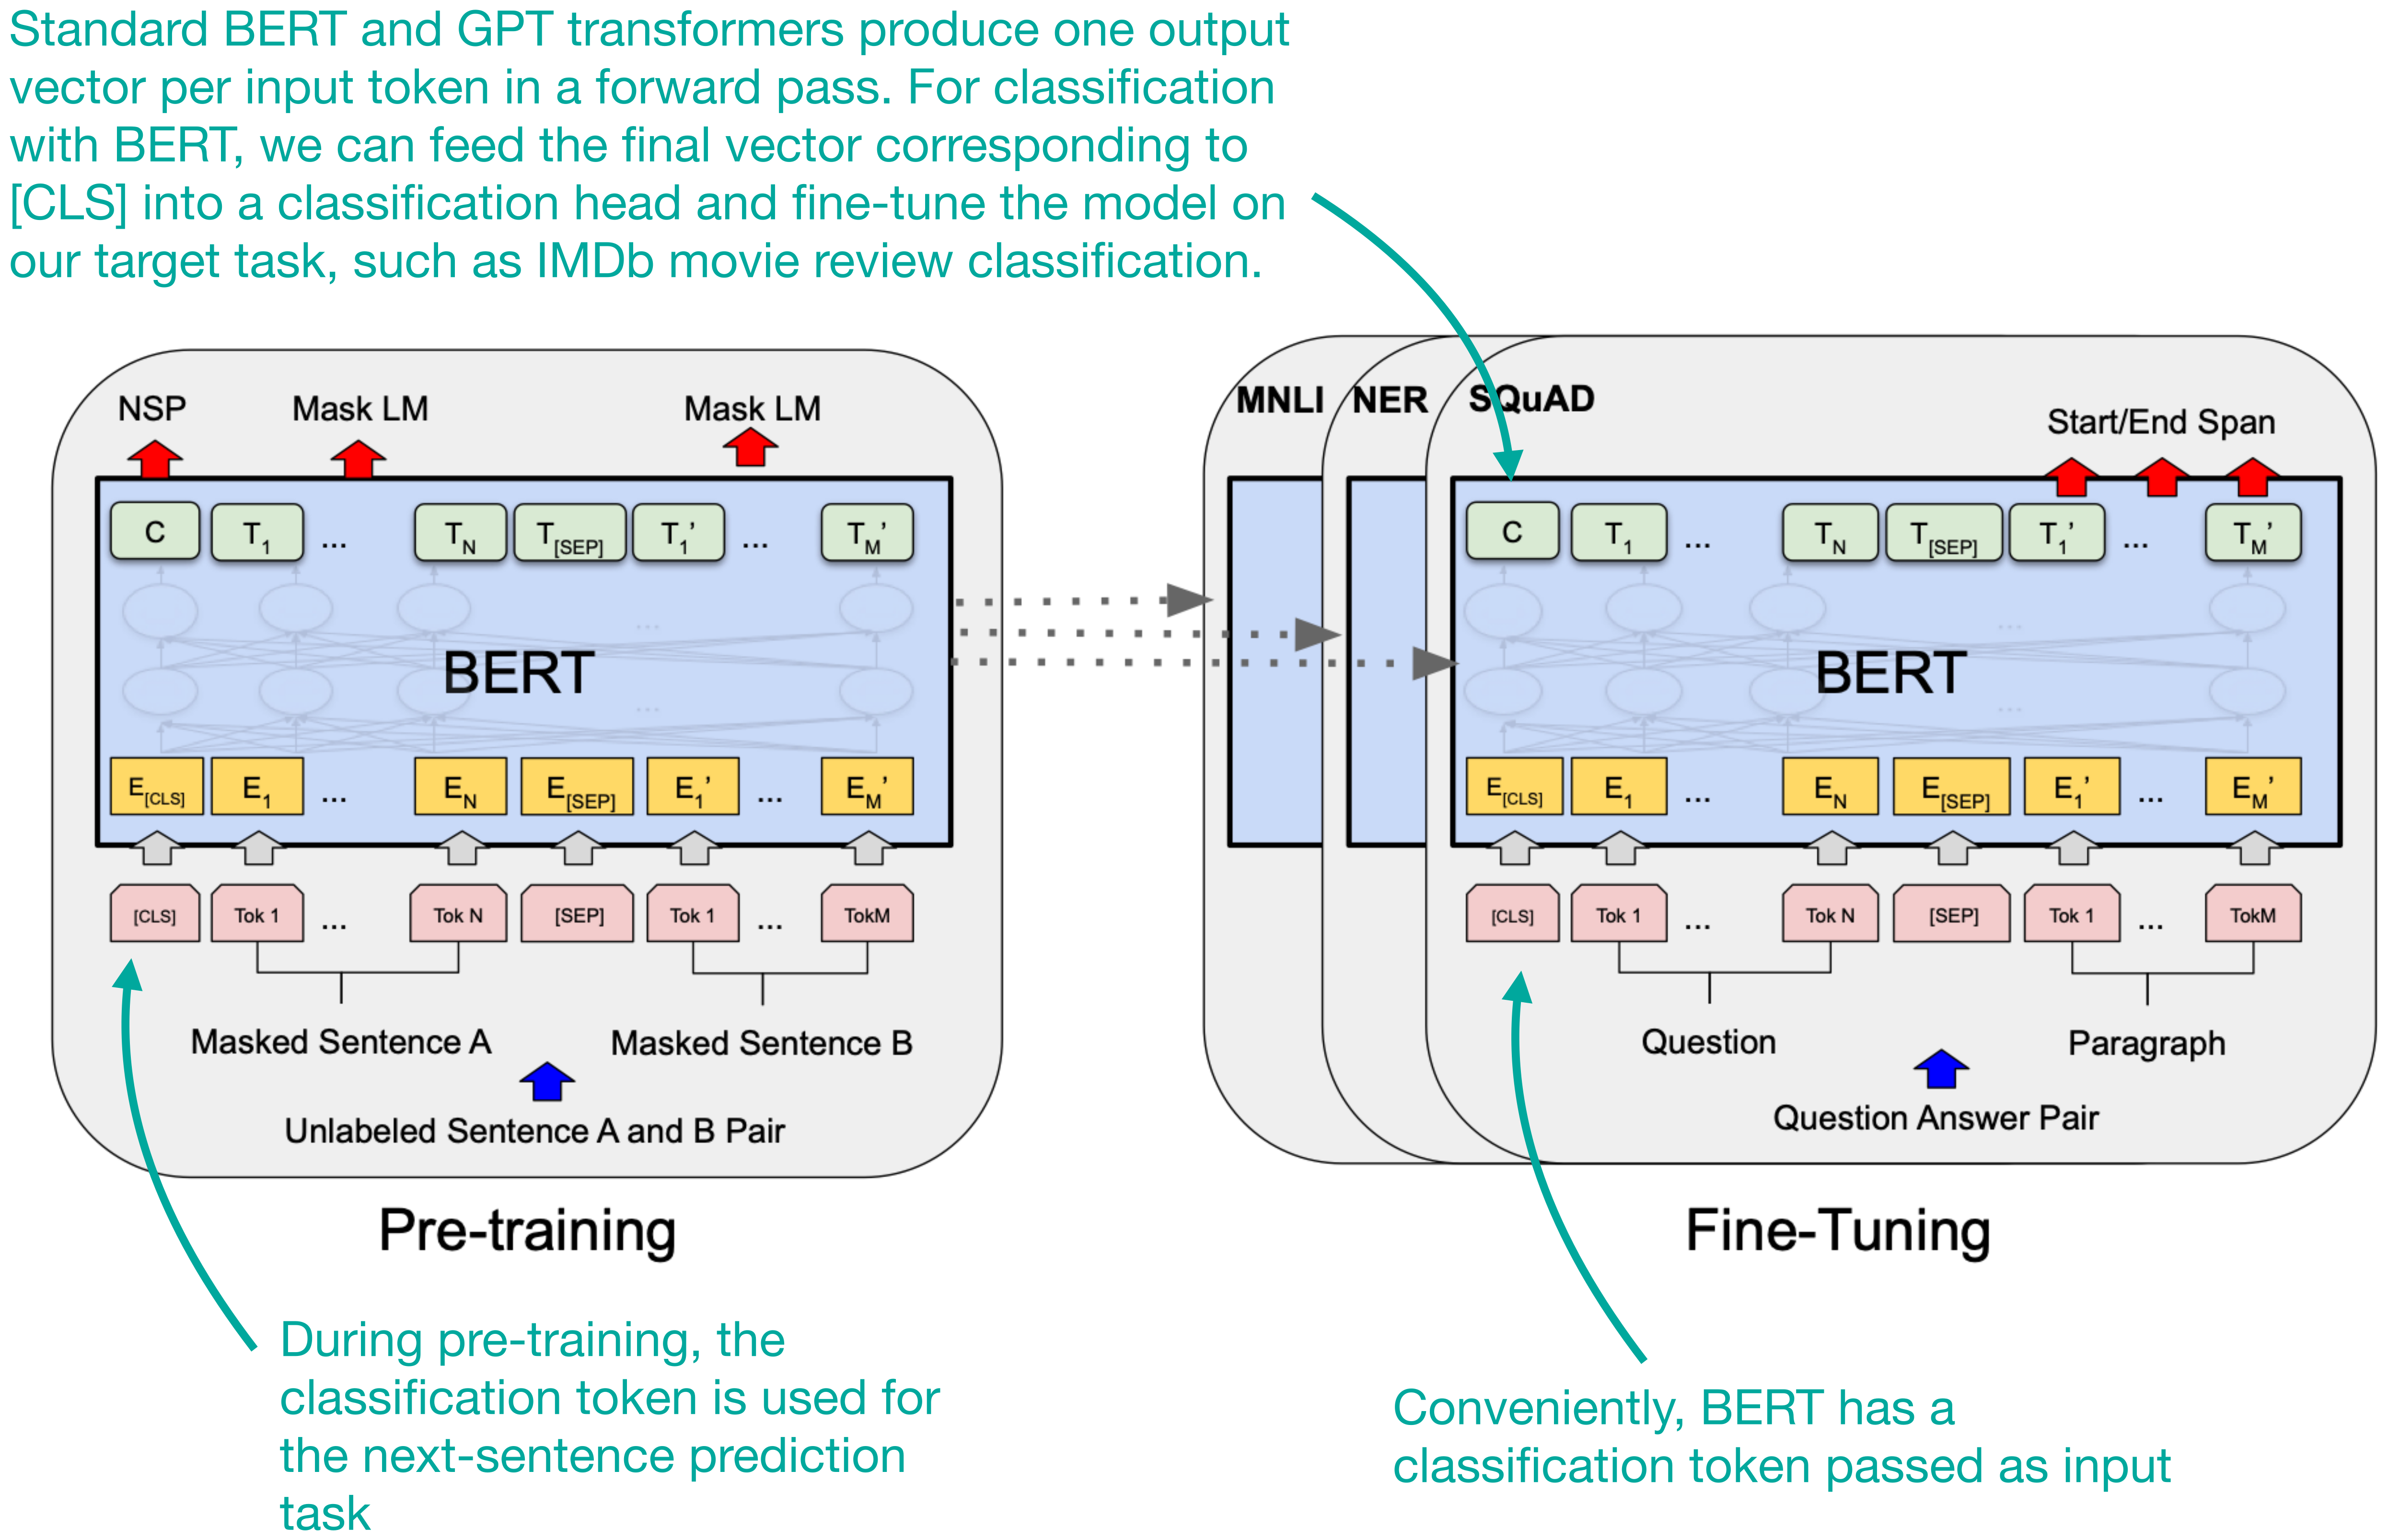
One universal aspect of using transformers, whether encoder- or decoder-style, is that we work with models pre-trained on large text corpora, and, in addition to using them as zero- or few-shot classifiers, we can fine-tune them on the target dataset (similar to ULMFiT, as mentioned in the RNN section earlier).
As shown in the figure excerpt from the BERT paper (2018) below, BERT-/encoder-style models have a classification token at the first position that we can conveniently fine-tune for this.
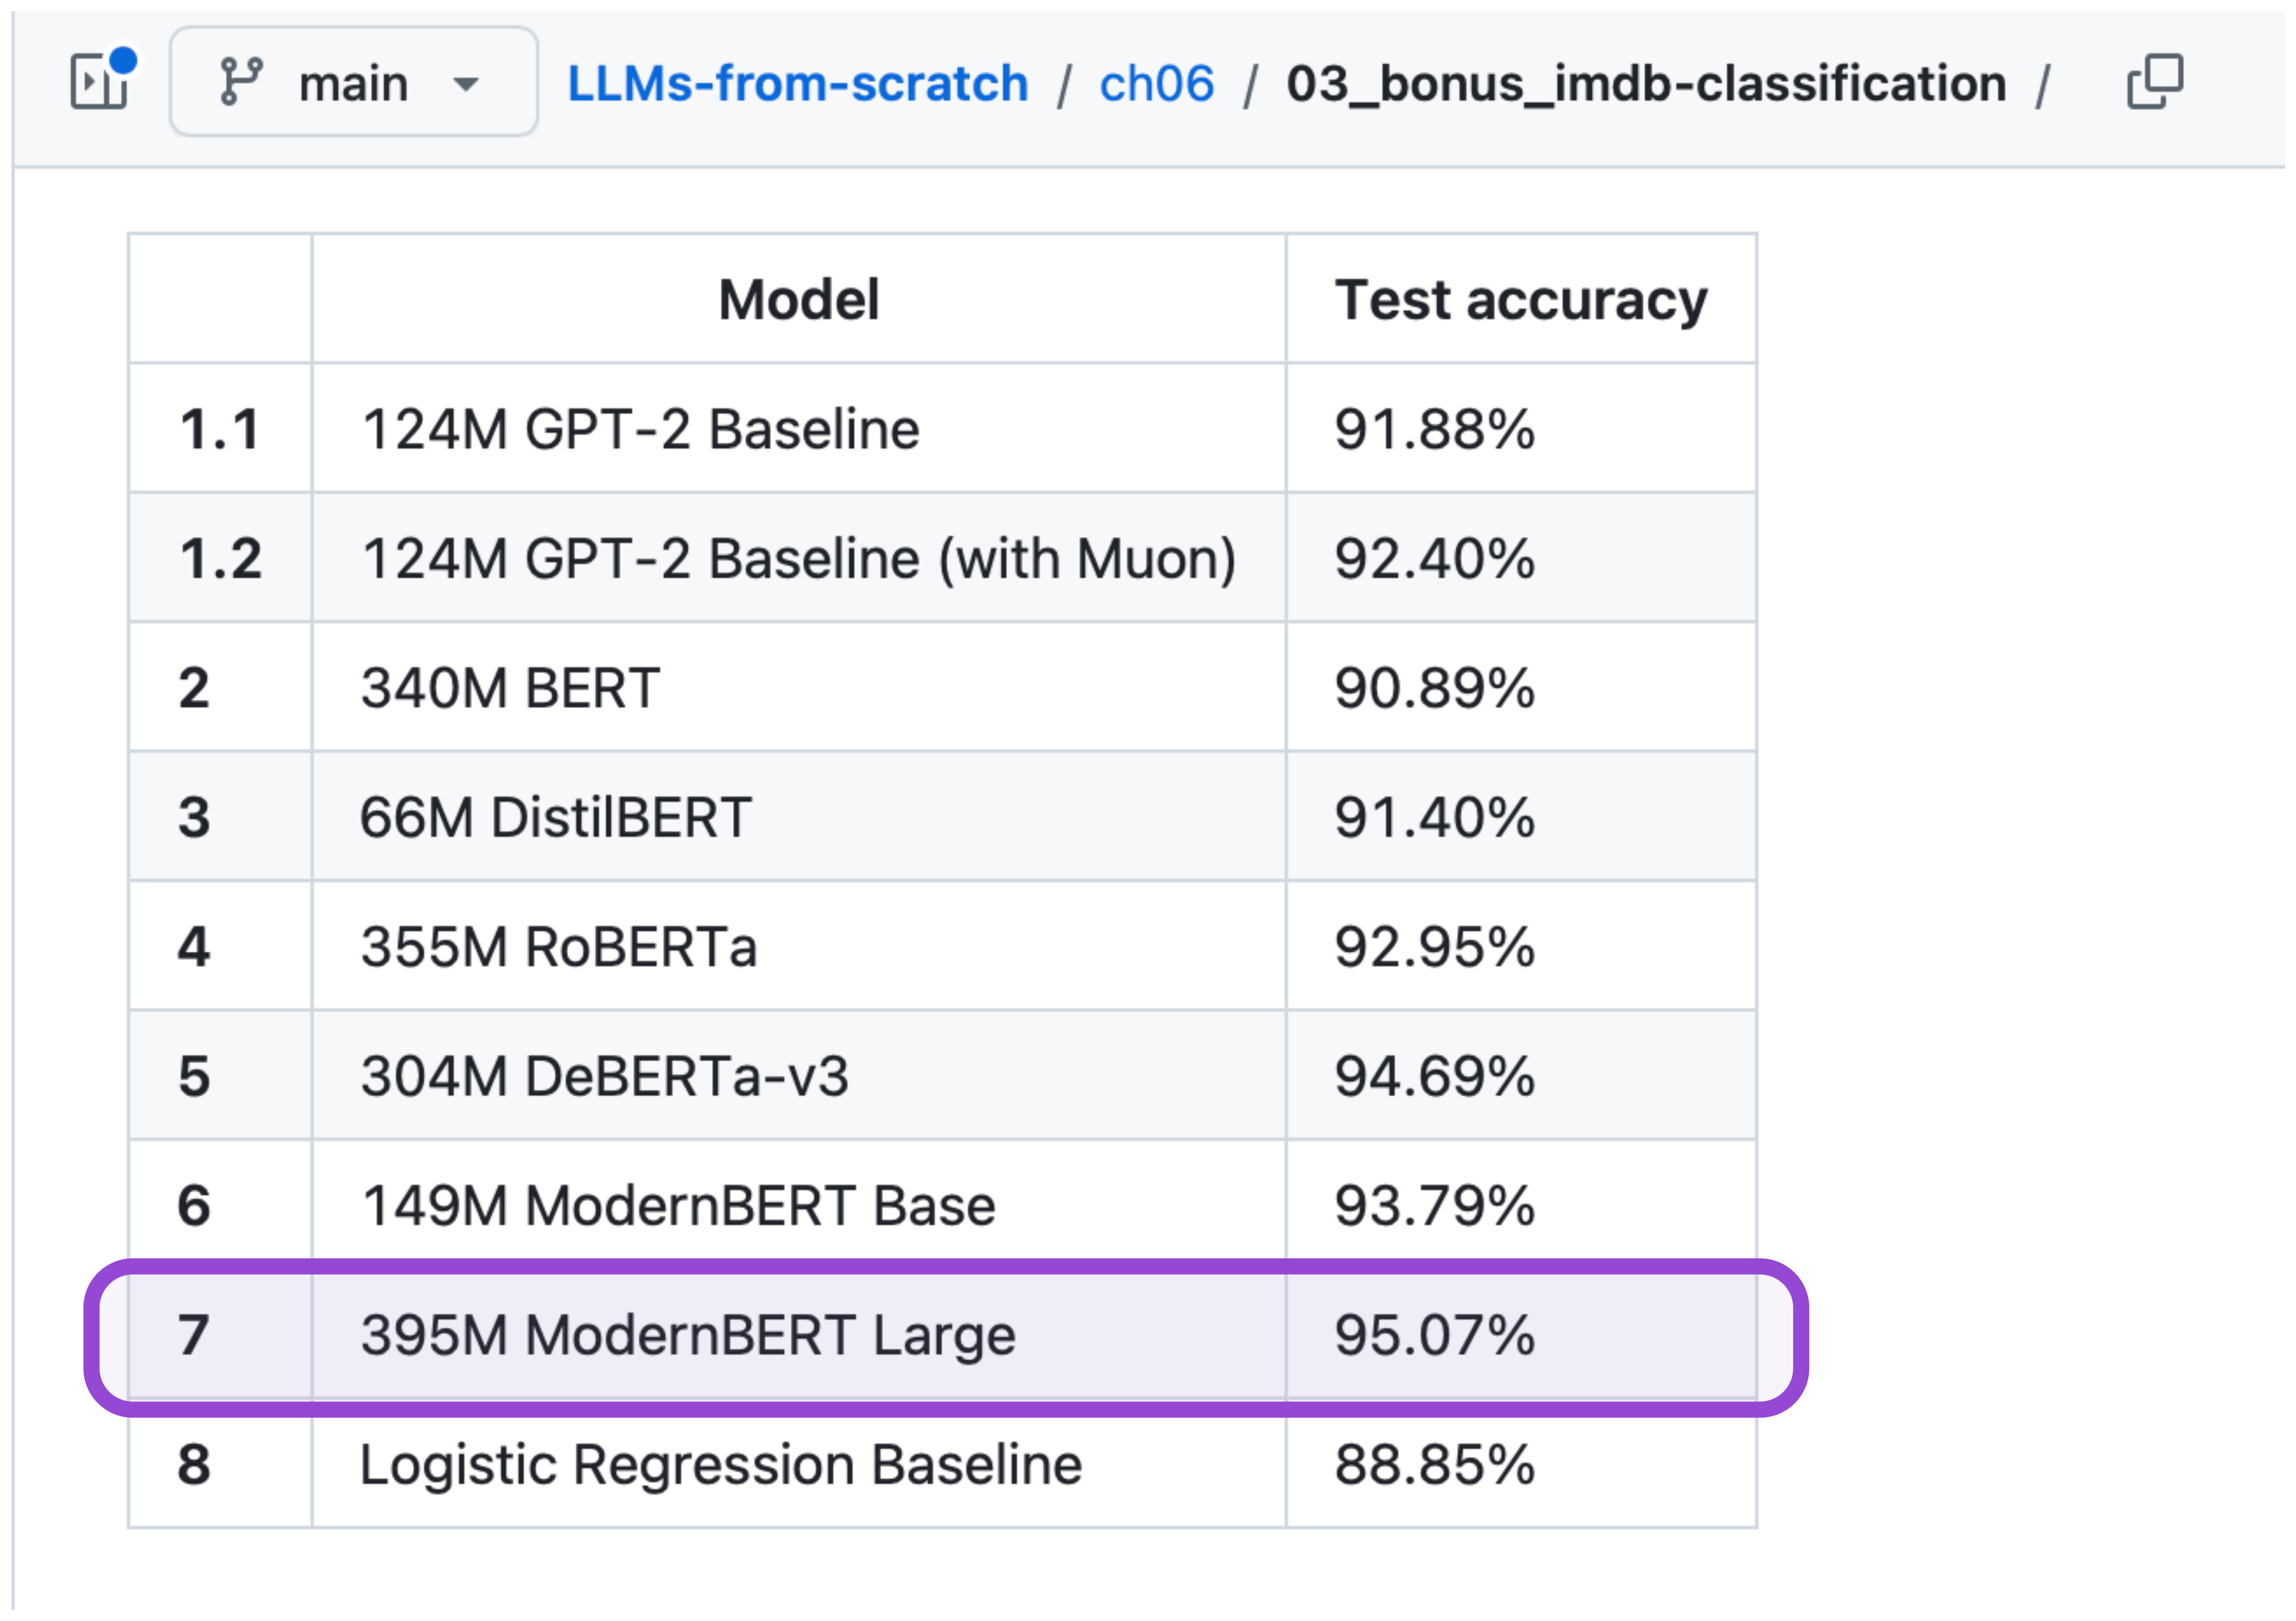
While BERT models are not nearly as popular as autoregressive GPT-style transformers, thankfully some people still update and modernize them occasionally. One recent example that is often my go-to for classification tasks is the 2024 ModernBERT model.
As shown below, on the IMDb movie reviews, ModernBERT gets approximately 95% accuracy with very little fine-tuning effort.
2.2 Decoder-style LLMs
LLMs like GPT are decoder-style, autoregressive transformers that are the center of all attention (no pun intended) for generating text and code.
However, as I explained in chapter 6 of my Build A Large Language Model (From Scratch) book, as a gentle introduction to fine-tuning (before covering instruction fine-tuning), we can also repurpose these for text classification.
Sure, we can also prompt an LLM directly, as shown in the screenshot below.
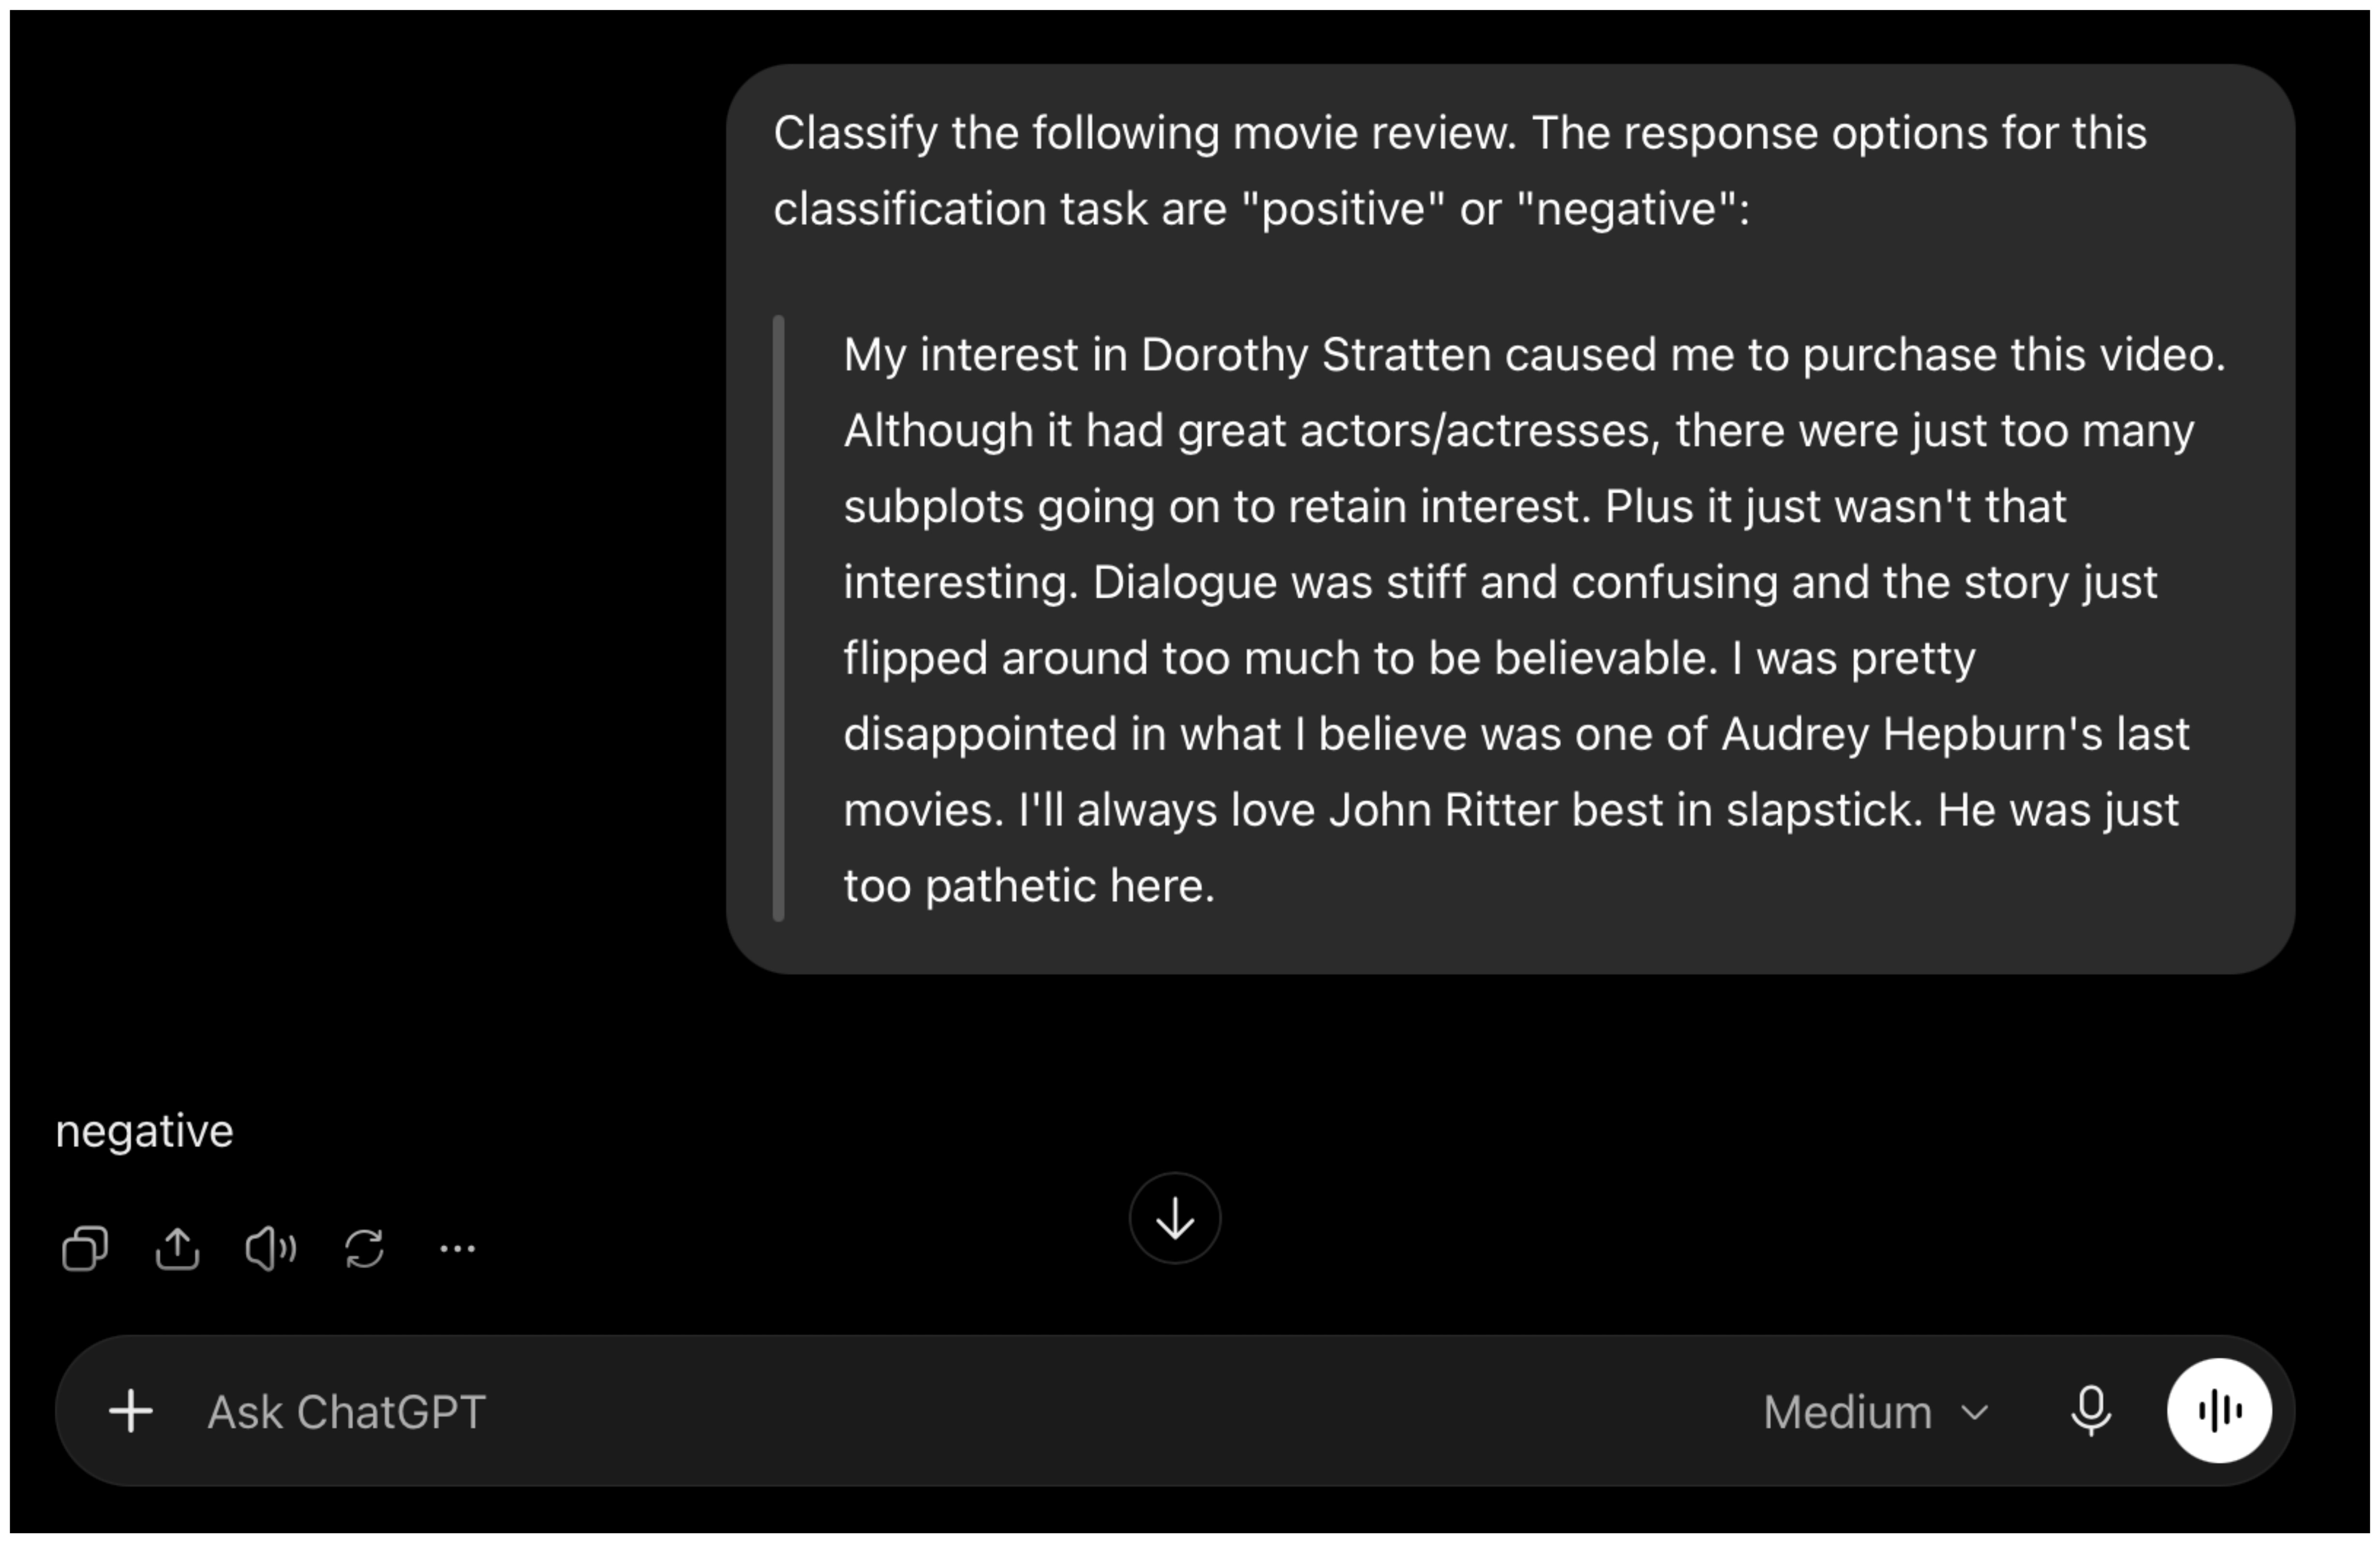
However, if we want structured outputs and we have a specific target domain in mind, this is unnecessarily brittle and inefficient.
Instead, we can replace the output layer with a leaner classification head, as illustrated below:
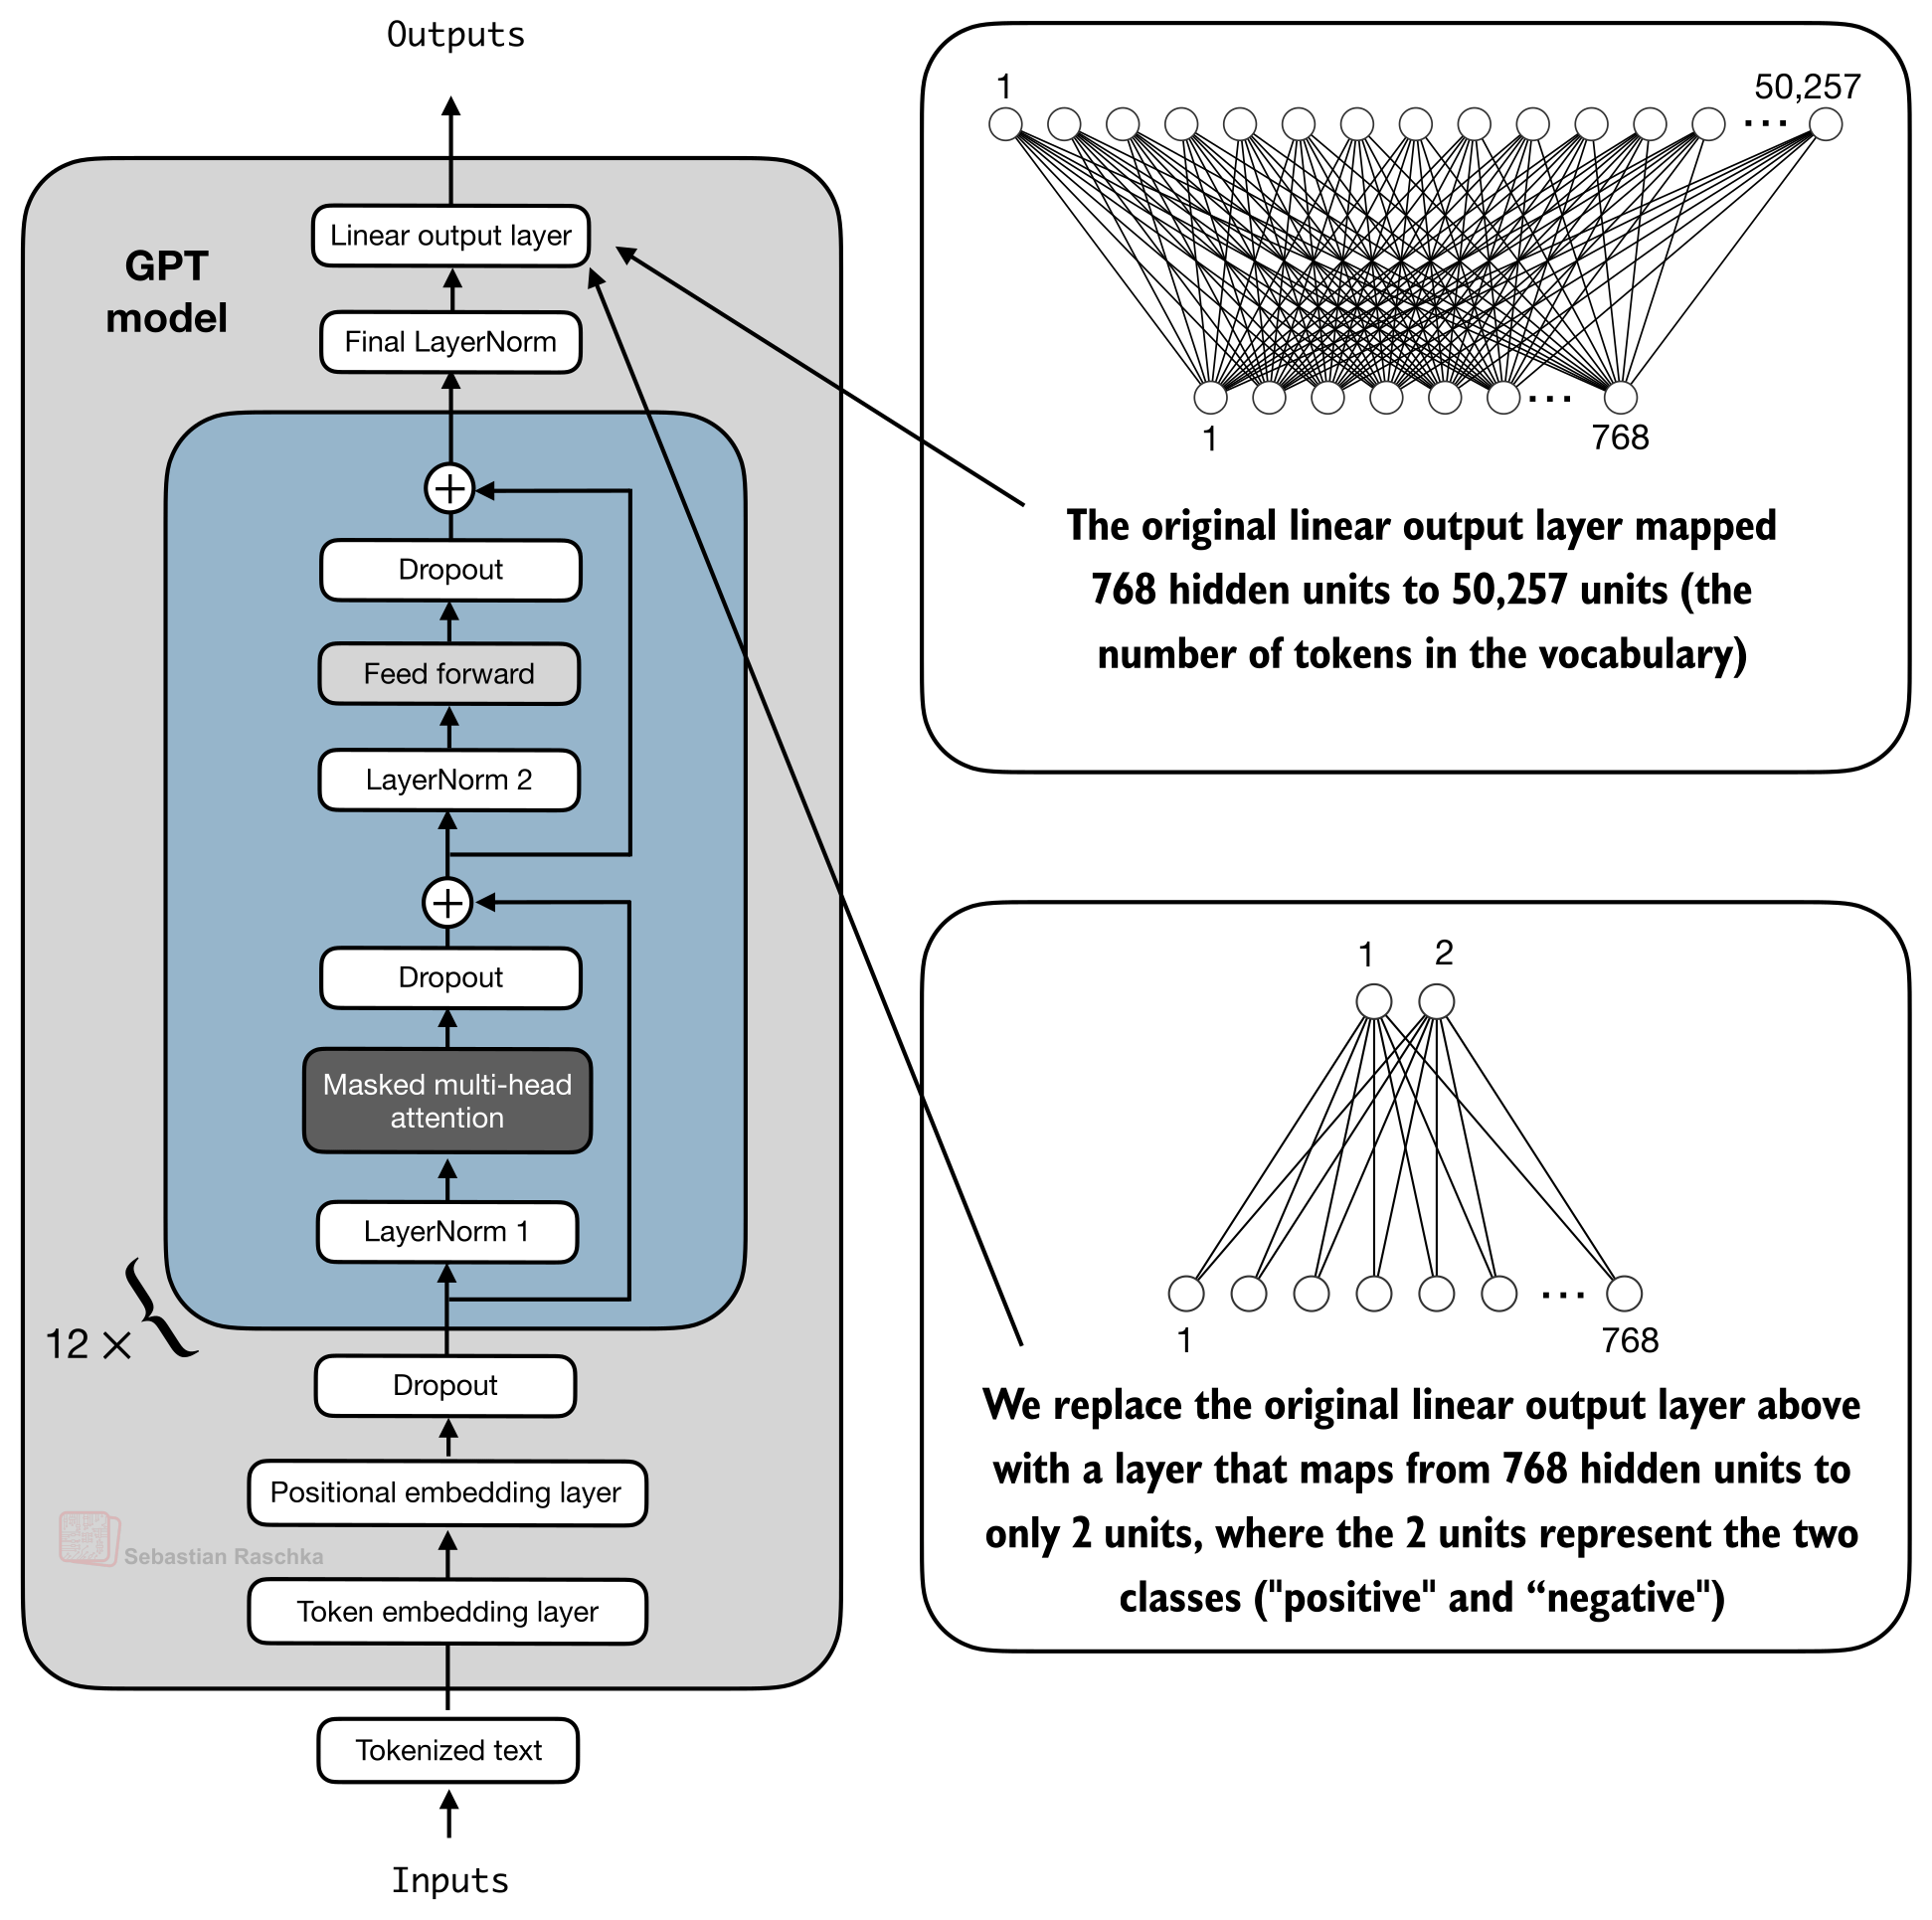
Now, fine-tuning has a few caveats. For instance, because of the autoregressive attention mask, we have to be careful about how we design fine-tuning so that the classification token has information about all other tokens in the sequence.
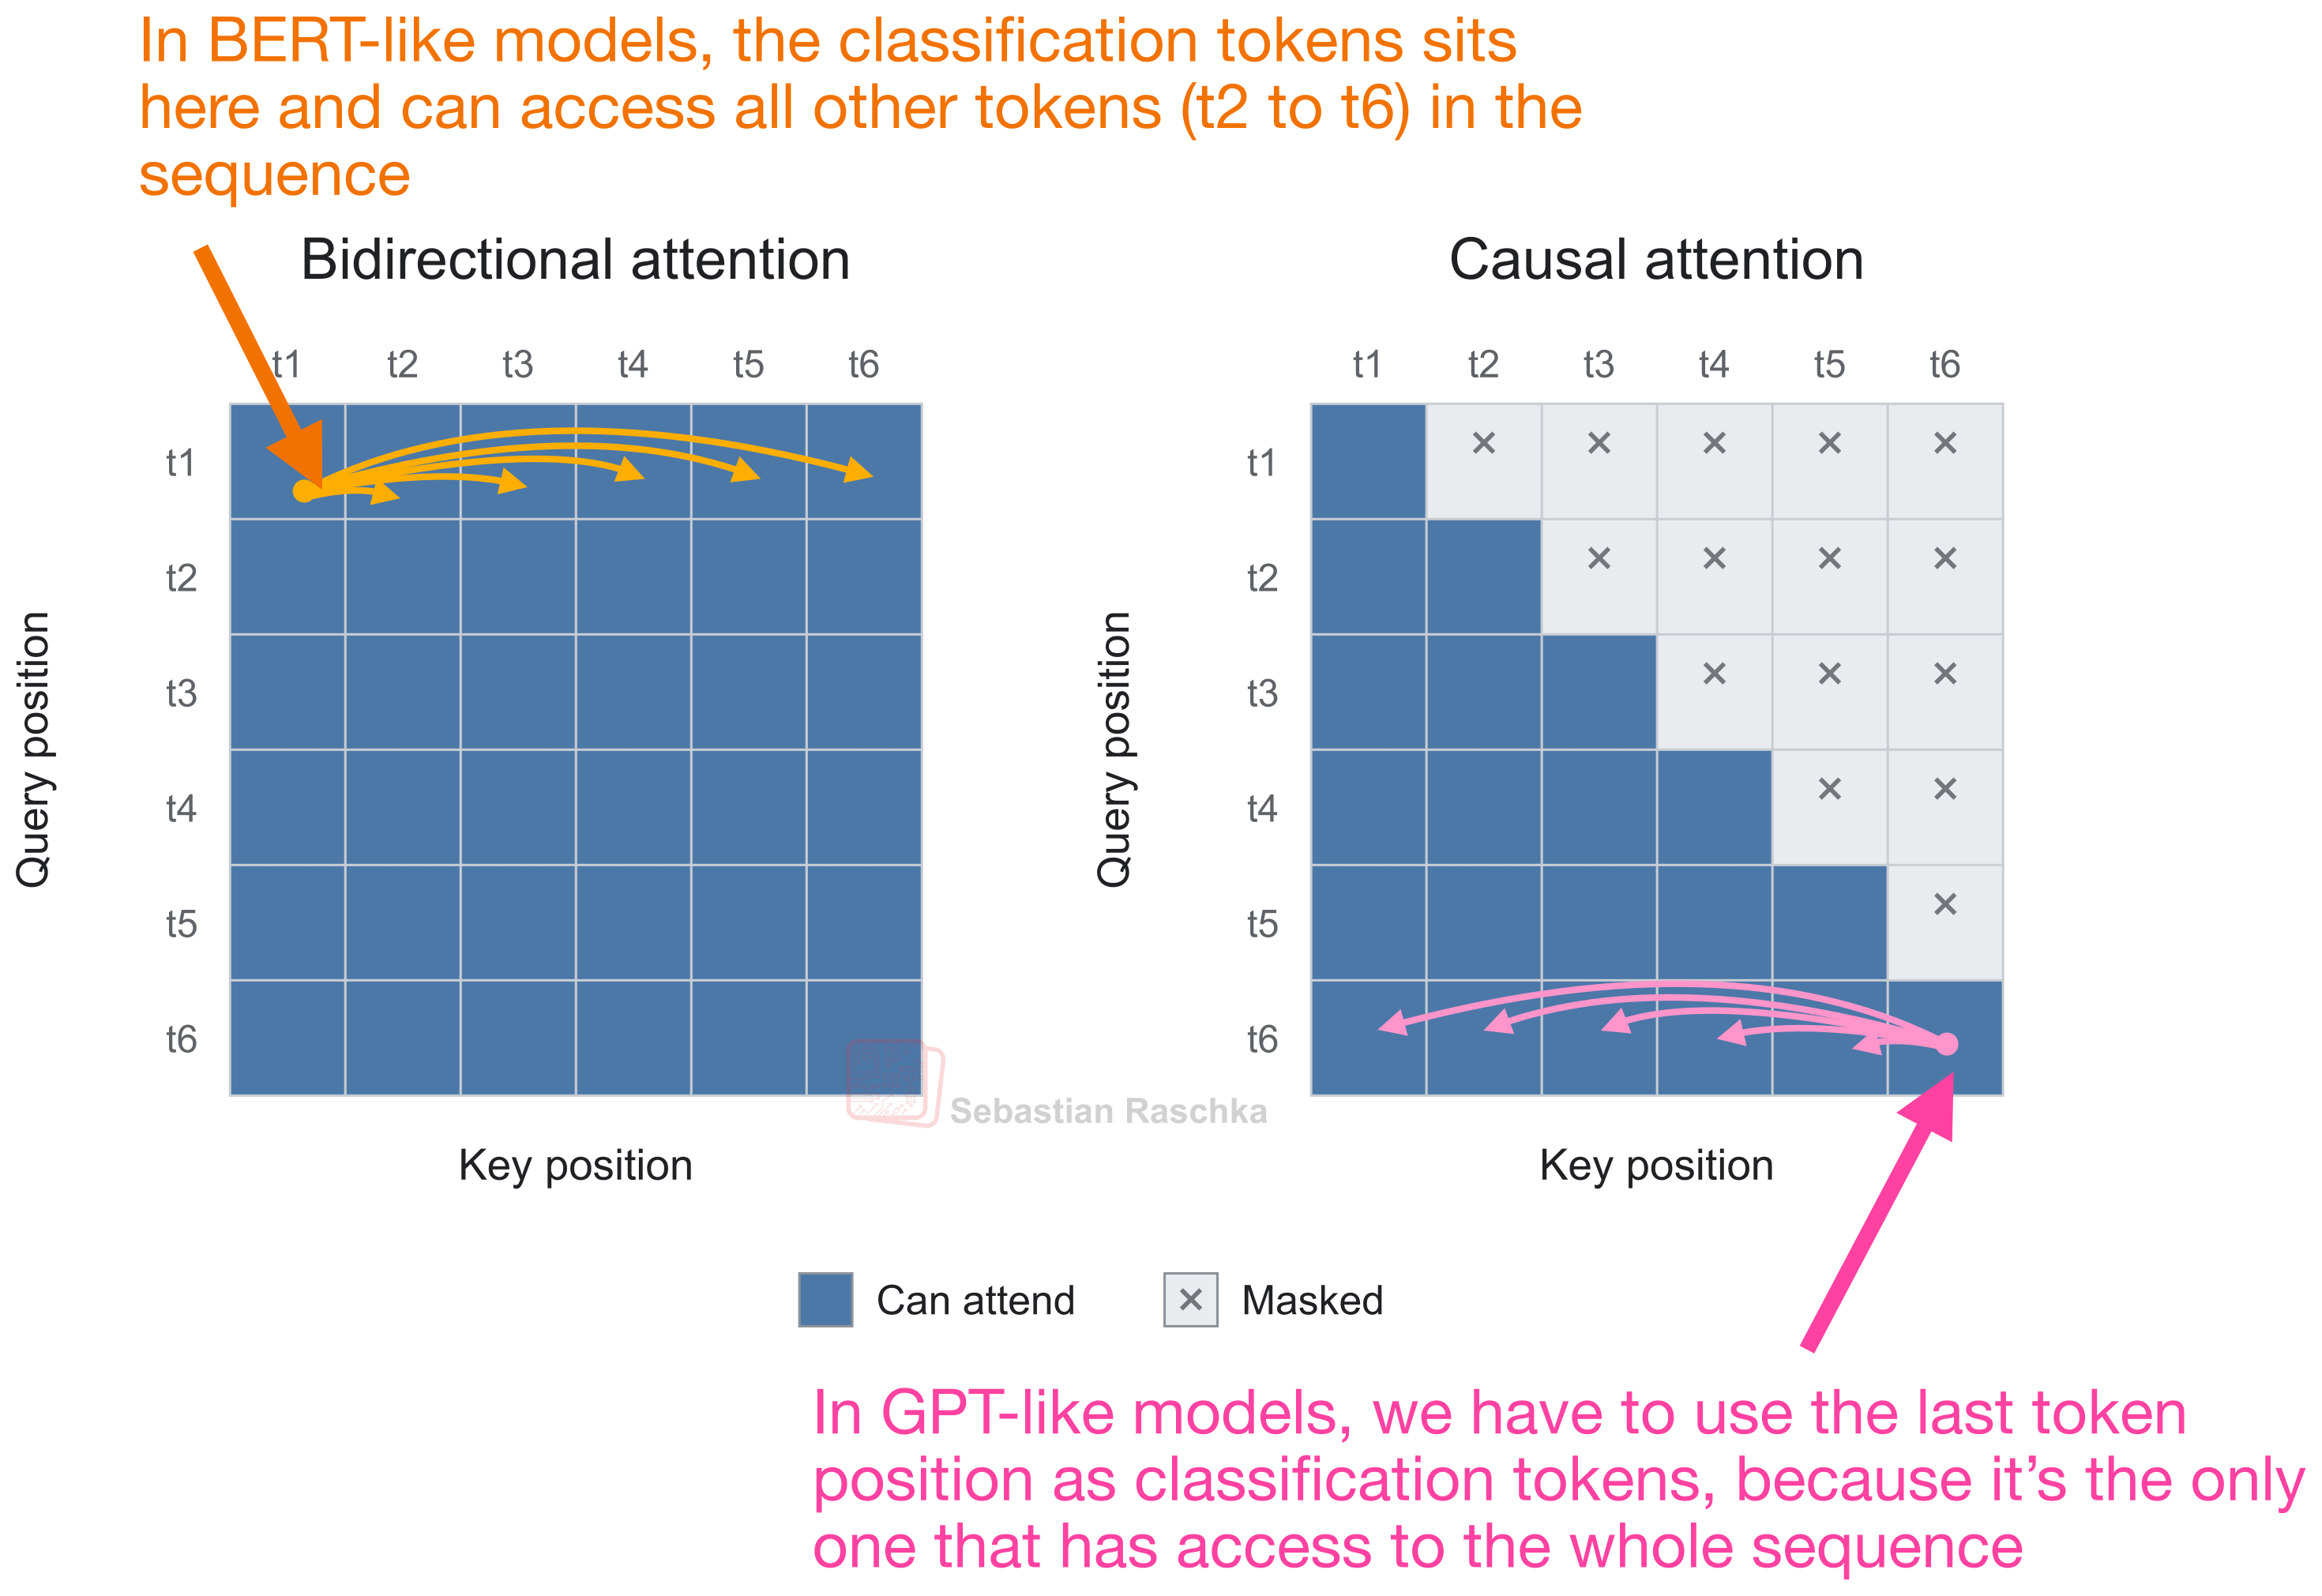
If you are interested in further technical details, please see my recent end-to-end Building an AI Text Detector From Scratch article:
Building an AI Text Detector From Scratch

Substack recently launched its AI detector feature in the UI, which is super interesting.
Overall, though, the advantage of using GPT-style LLMs over e.g., BERT variants is that there are so many modern open-weight architectures out there to adopt. Anything between the small Qwen 3 0.6B models to the latest Kimi, GLM, or DeepSeek models. (Of course, using such >1B parameter models for classification could be a bit overkill from an efficiency perspective, but hey, it’s possible.)
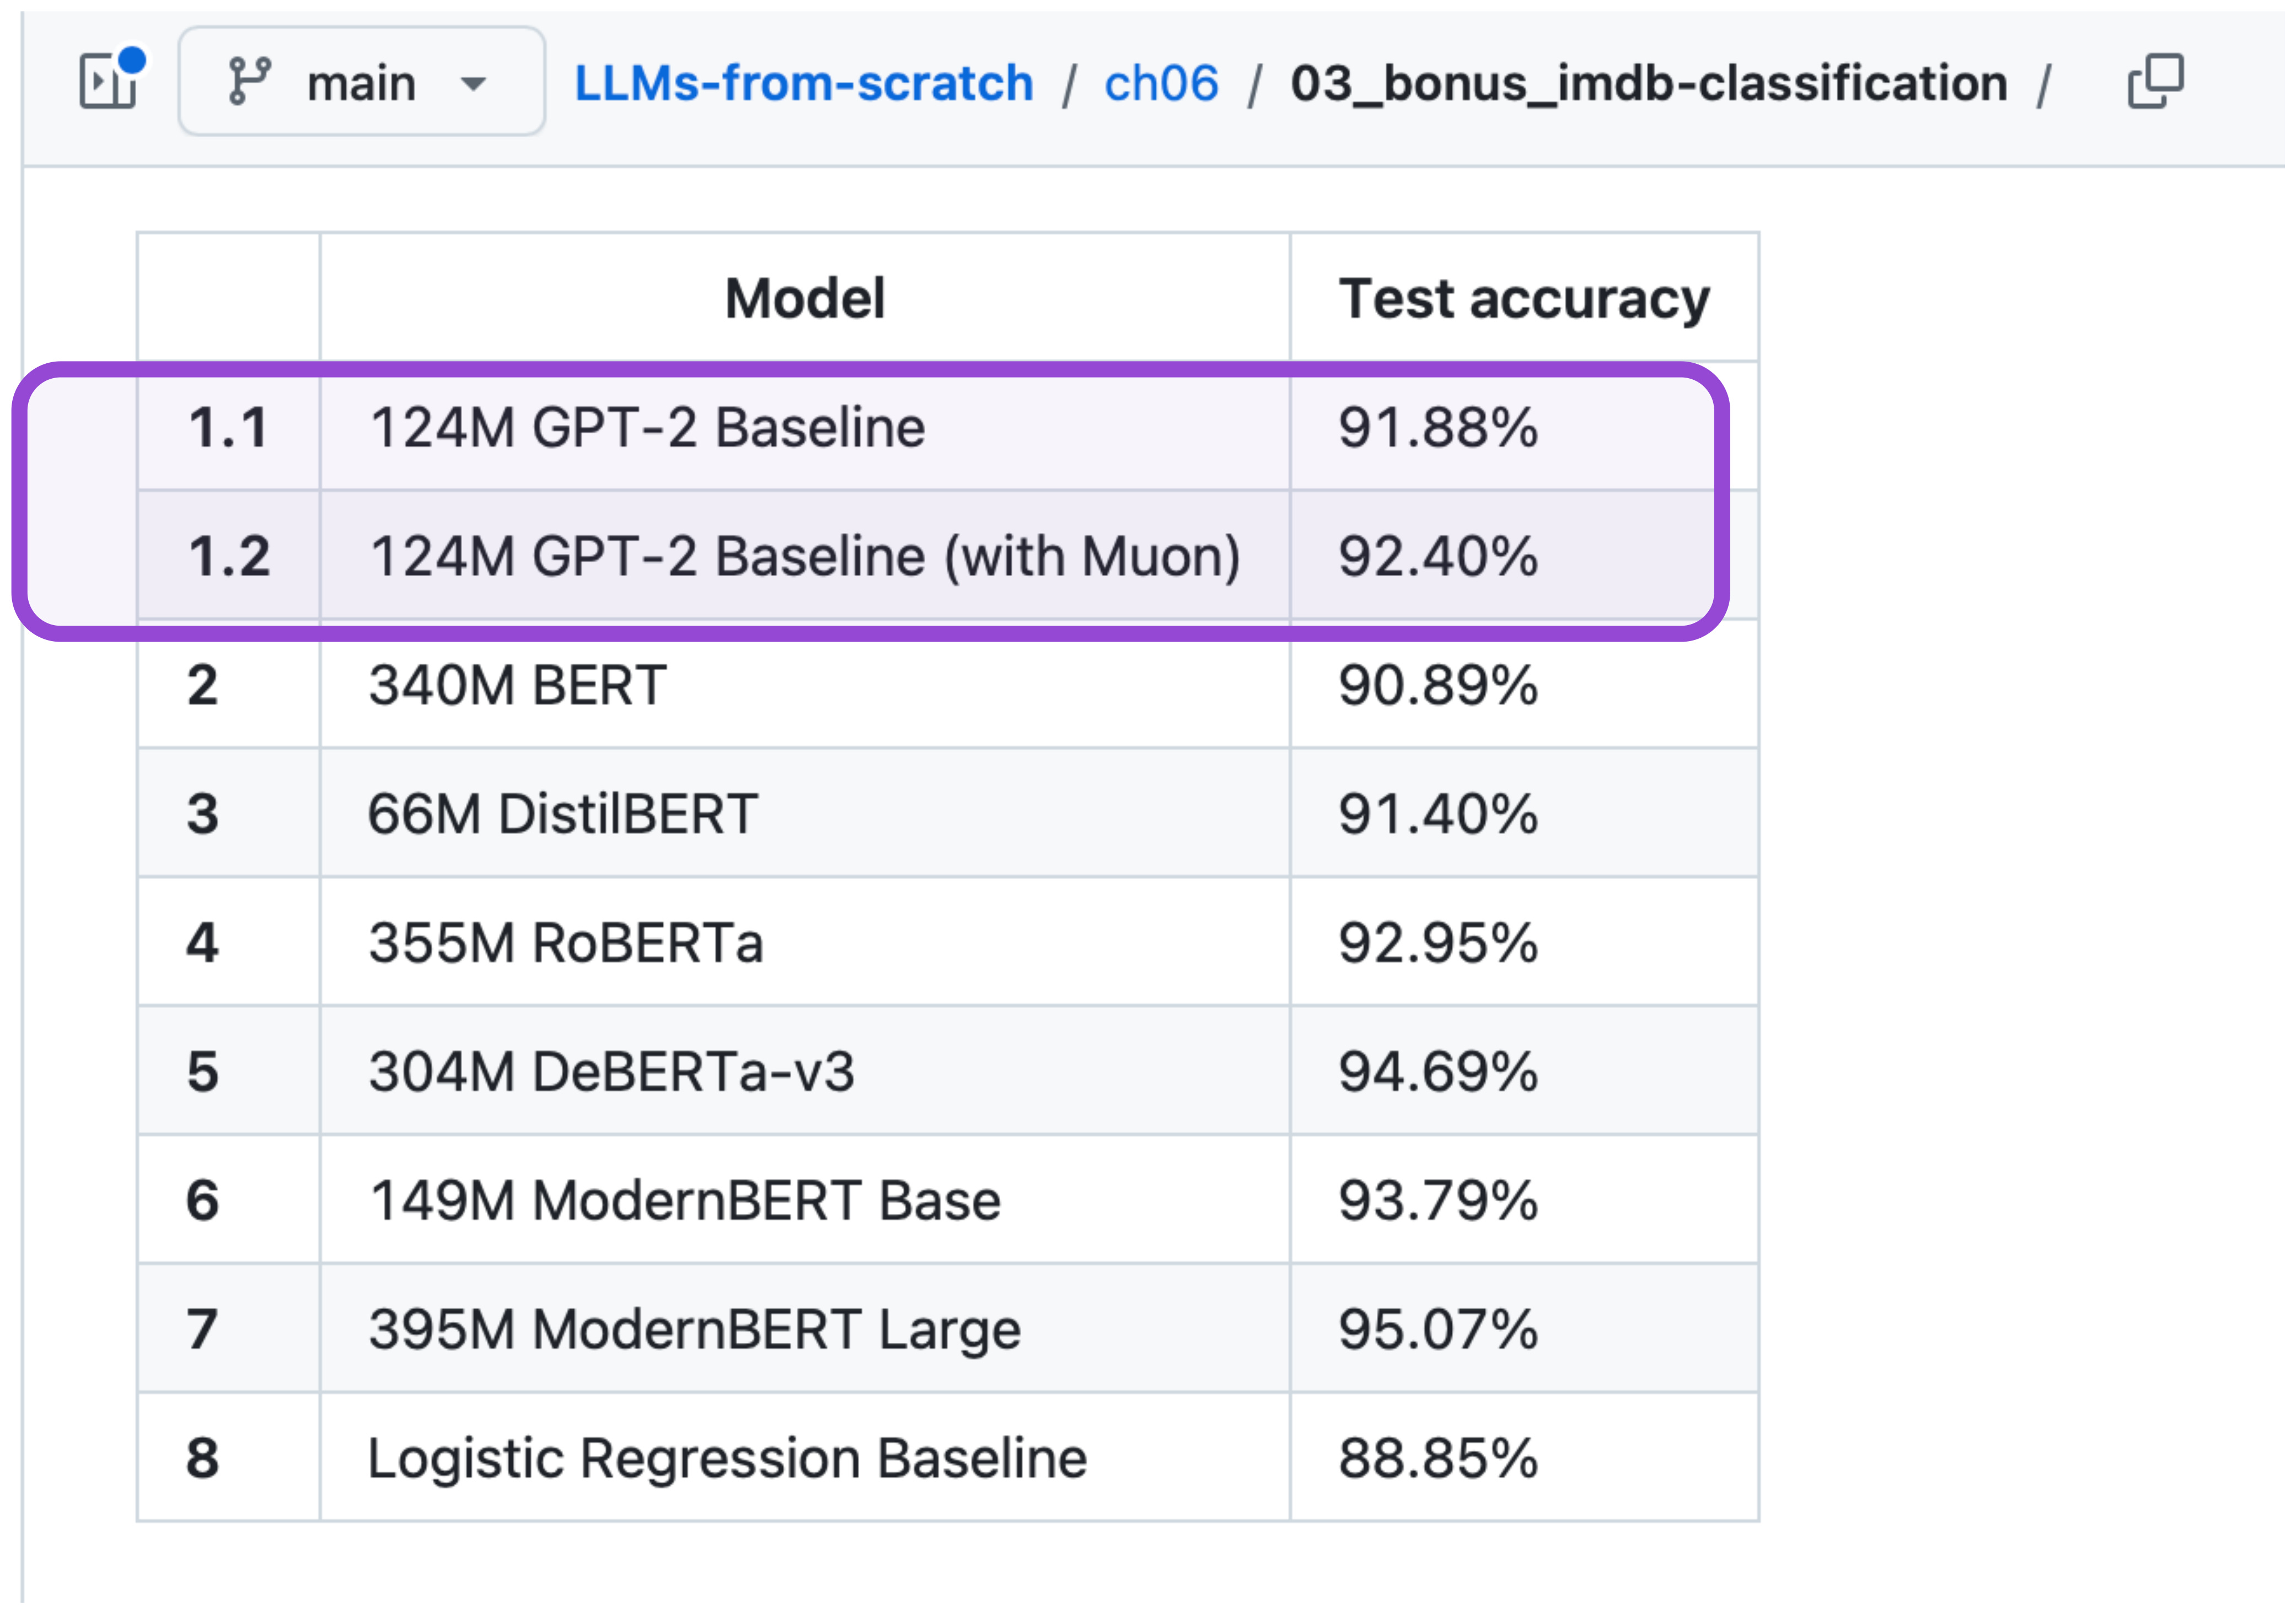
Figure 20: On the aforementioned IMDb movie review dataset, a relatively small GPT-2 124M model gets approximately 92% accuracy; a larger and newer LLM (like a recent Qwen3 variant) would likely perform better.
2.3 Encoder-decoder style architectures
While the original transformer architecture (an encoder-decoder) was split into two paradigms, encoder-style models like BERT and decoder-style LLMs like GPT, there were also efforts to use encoder-decoder-style variants, with the most recent variant (somewhat unexpectedly) being DeepSeek V4.1 Flash. (However, in this case, it’s a causal encoder not a bidirectional one as in T5.)
Keeping the focus on encoder-decoder architectures for classification, probably the most prominent candidate is Google’s 2019 T5 (Text-to-Text Transfer Transformer).
Architecturally, the differences between T5 and the original transformer include updates to the architecture (as summarized below), as well as changes to training. The original transformer was trained to do language translation (in a supervised fashion); T5 uses pre-training on unlabeled text with span corruption, where the encoder receives text with missing spans and the decoder generates those missing spans.
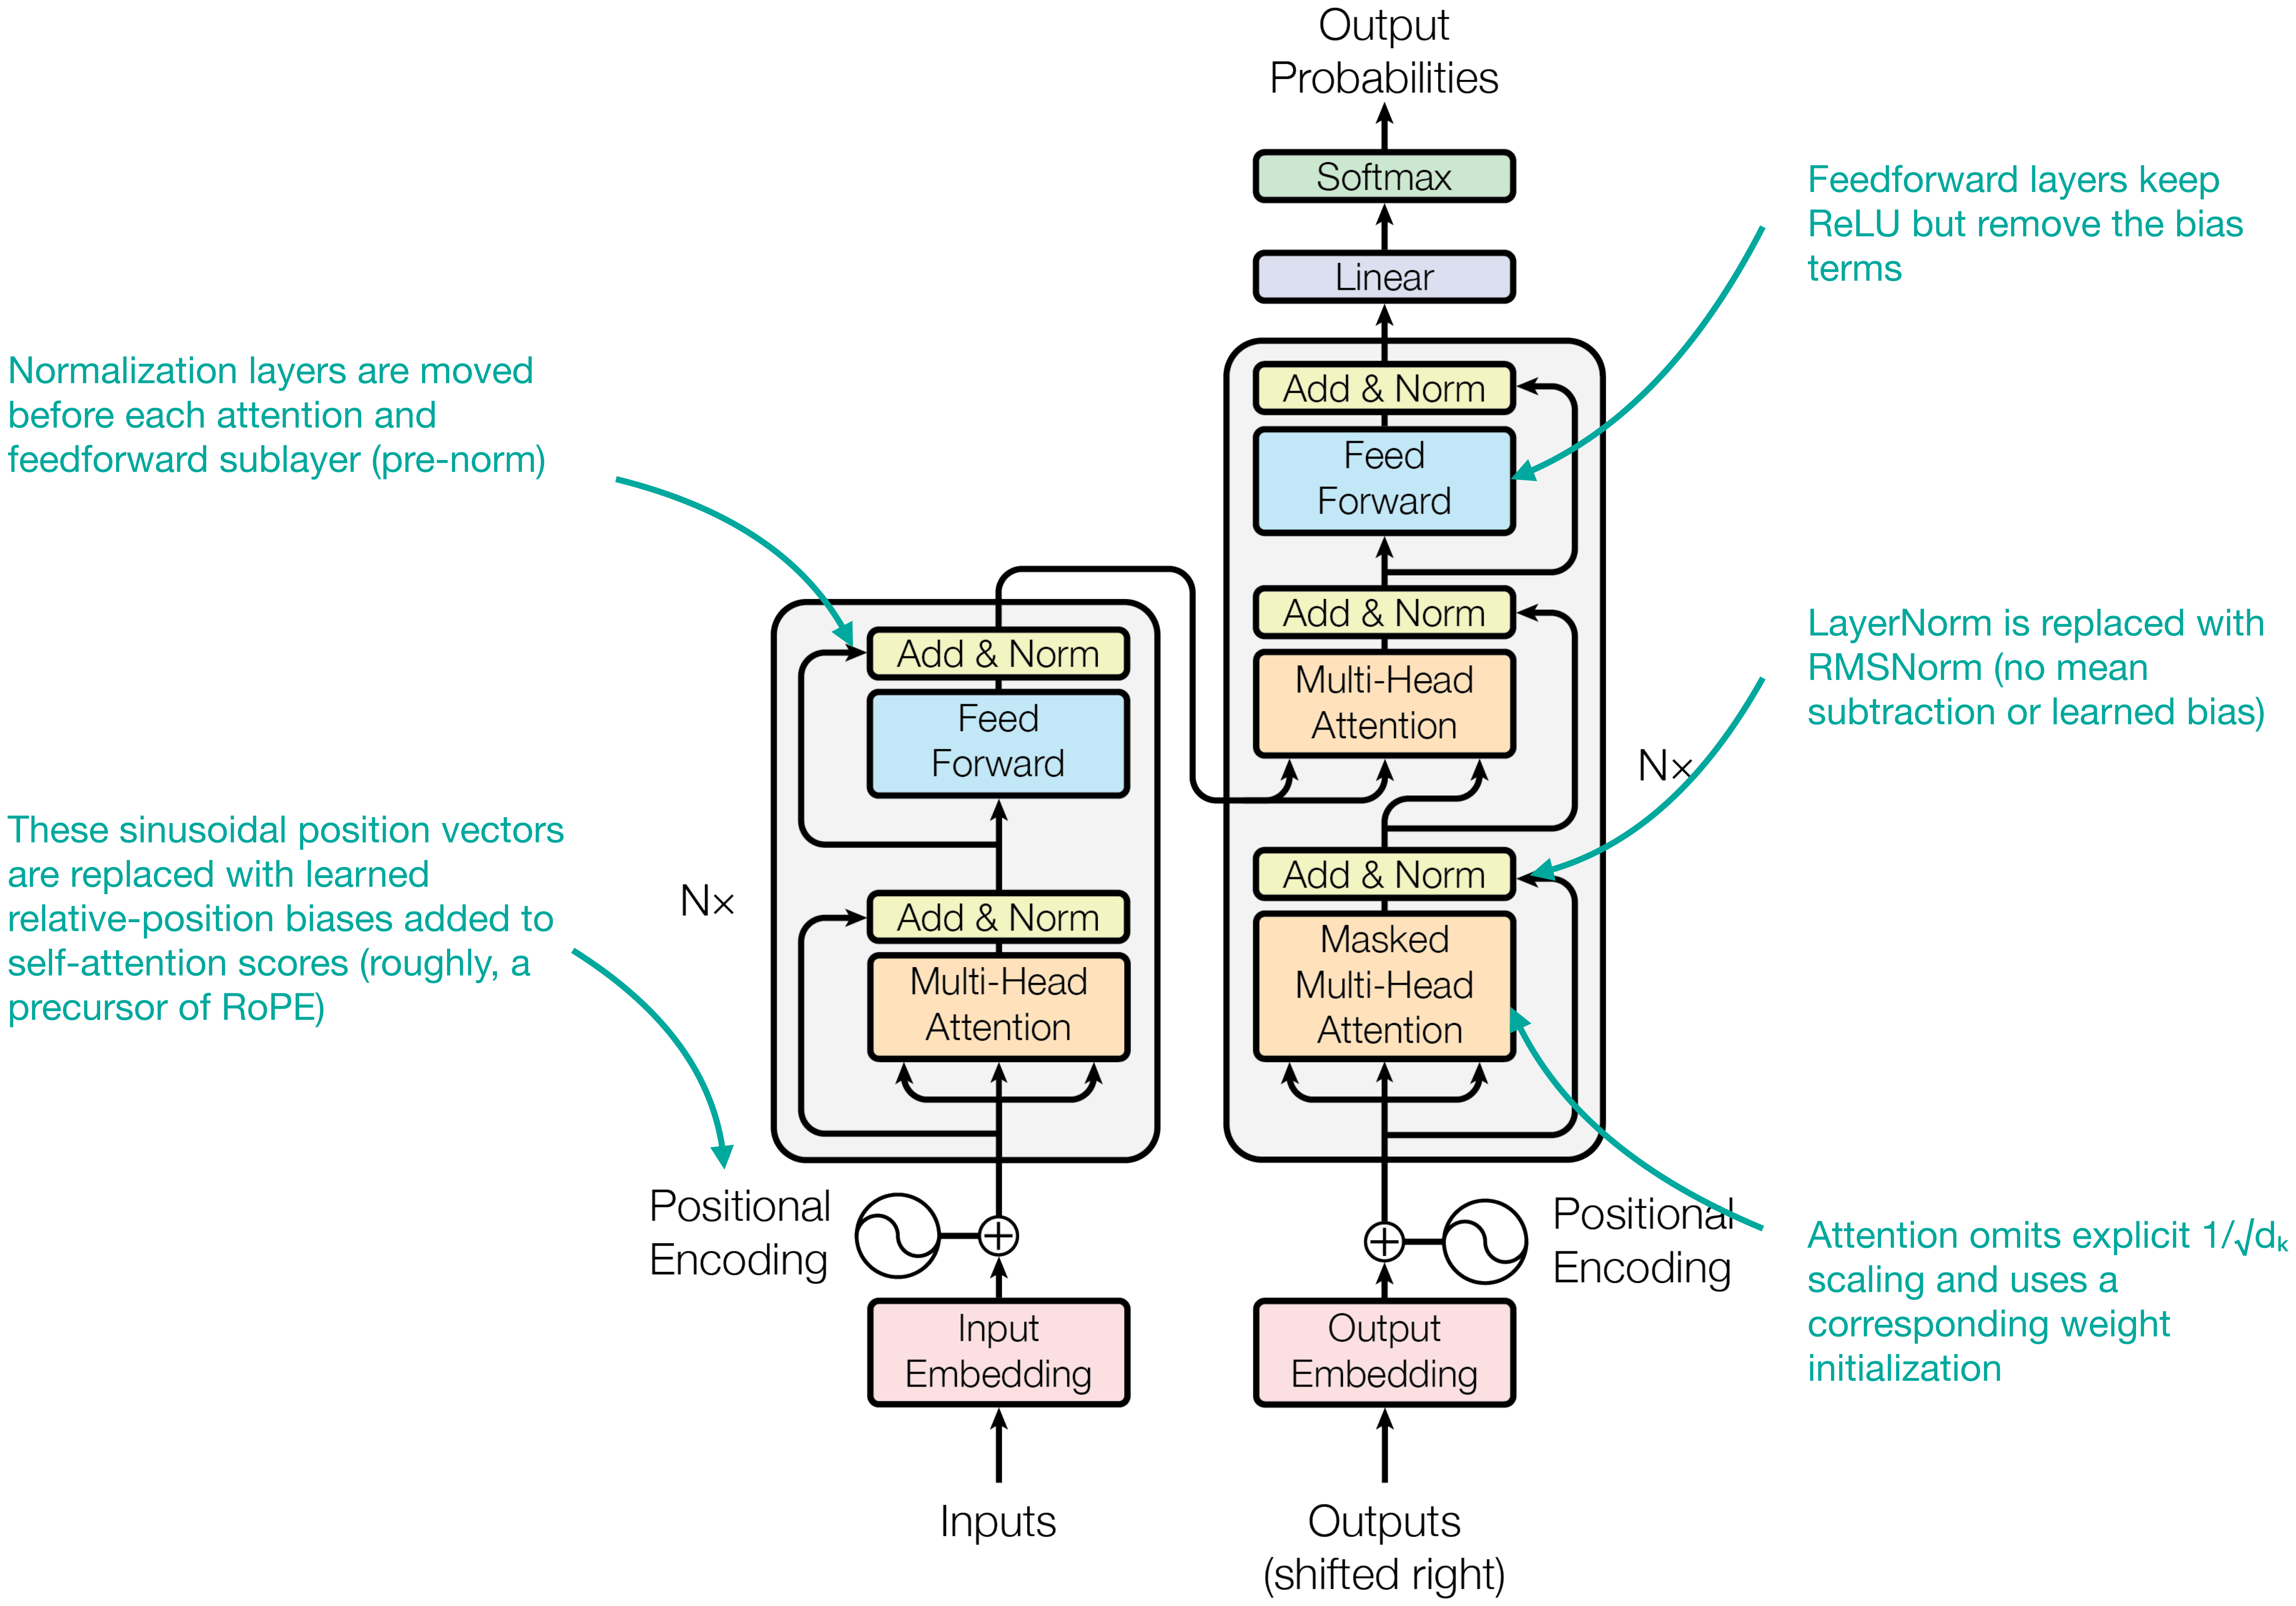
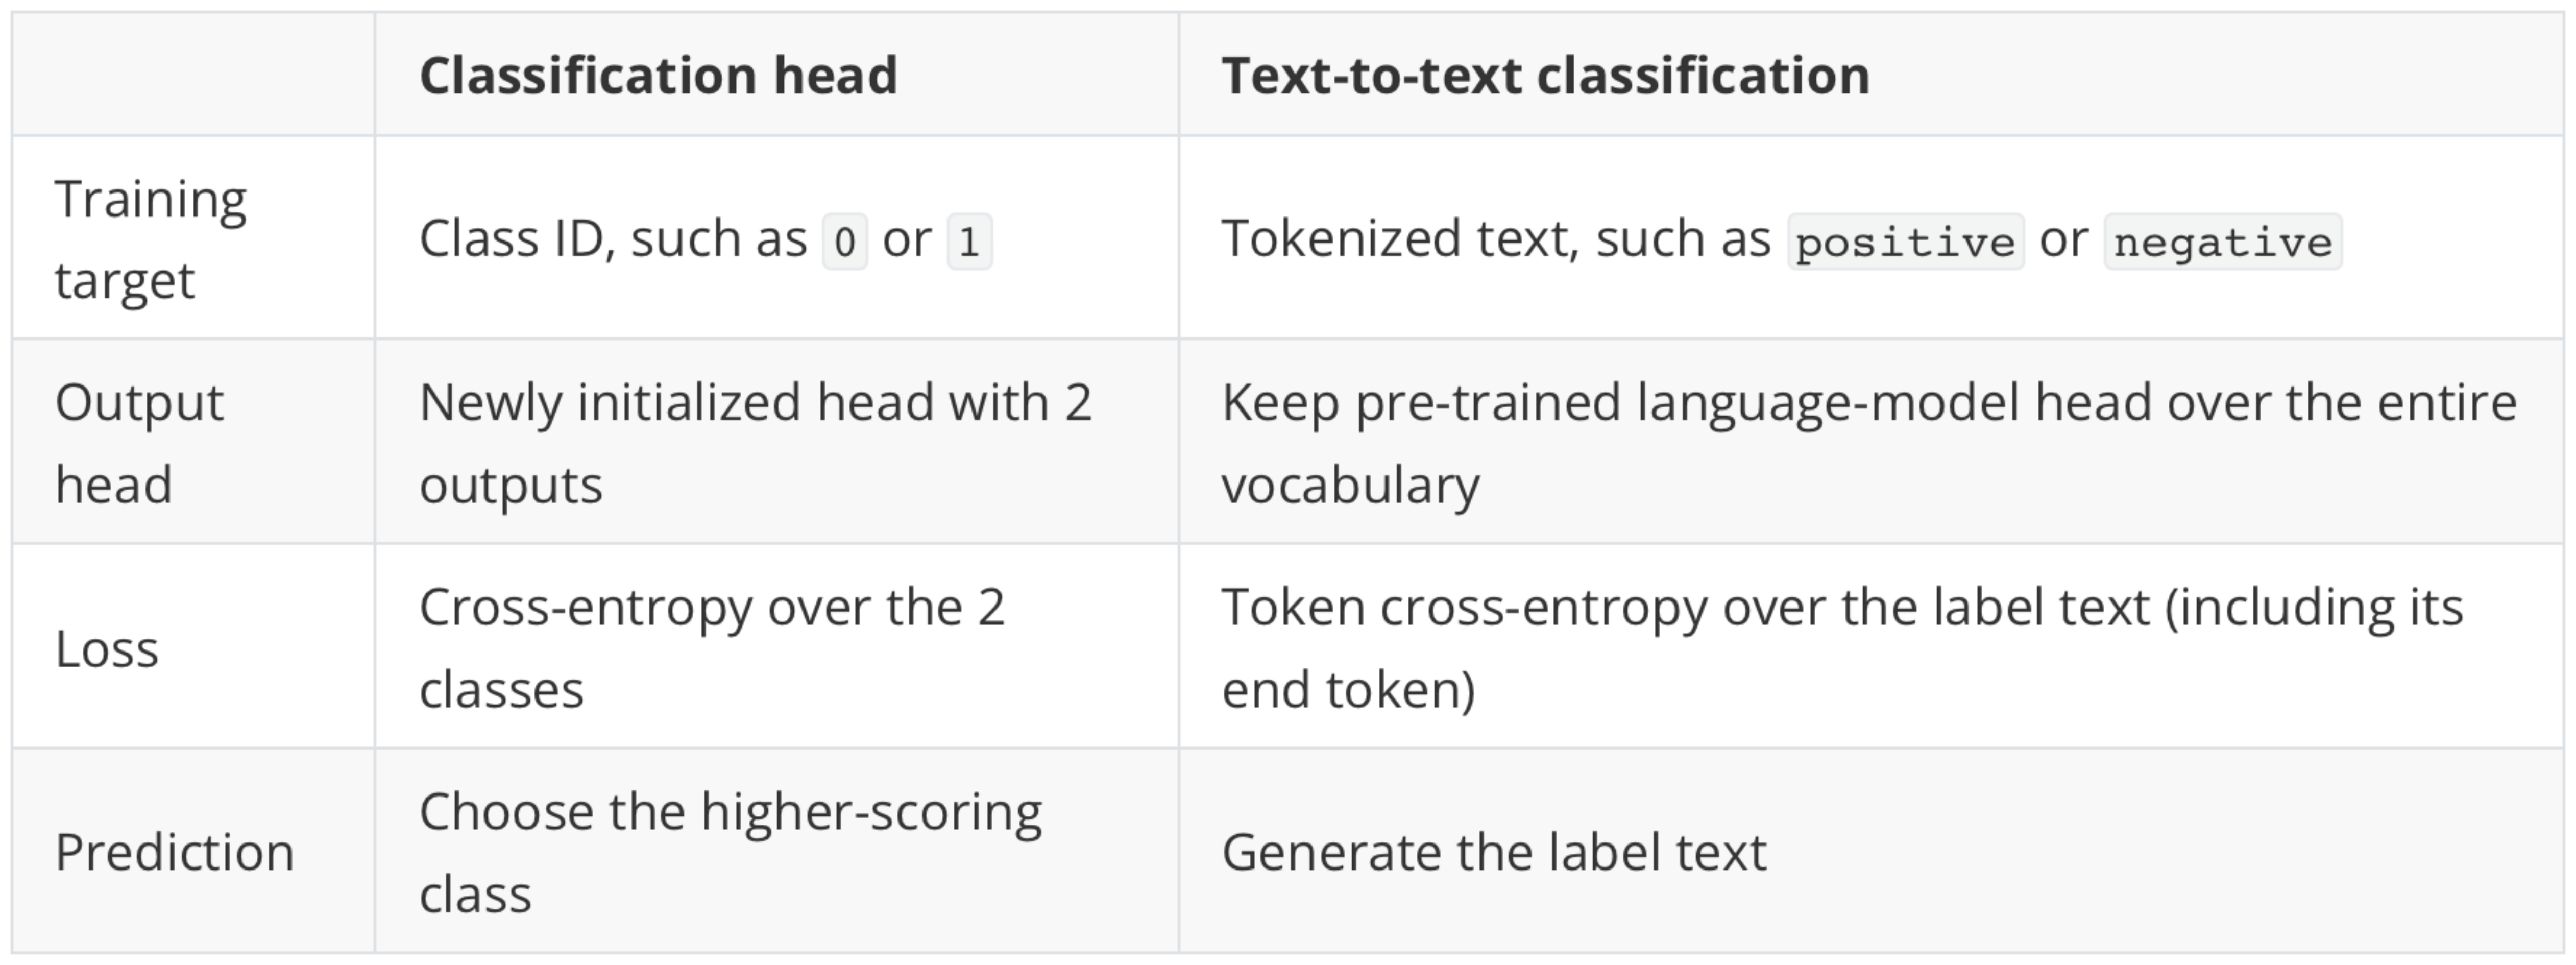
Now, we can use T5 similar to the other RNN, CNN, and transformer approaches above, by adding a classification head.
Additionally, we can also (train to) have the decoder output the class label prediction (like “positive” or “negative” in the IMDb movie review dataset case), similar to regular LLMs. Let’s call this approach text-to-text classification.
While GPT-style LLMs are trained on massive amounts of text, they usually perform text-to-text classification well out of the box, as shown earlier (the figure below is inserted here again for convenience).
However, in the case of T5, it is common to further fine-tune the decoder to do well on these types of tasks in a given target domain.
For T5, both approaches work. Here’s a summary:
3. Jev overview
So far, we have seen that there are plenty of approaches to text classification, from traditional methods like logistic regression and naive Bayes with bag-of-words representations to prompting the latest frontier LLMs like GPT-6 or fine-tuning any open-weight LLM with a classification head (or text-to-text classification).
At first, I (almost) dismissed it as “just a classifier,” something that I build routinely for classification tasks with natural language inputs (e.g., see my AI Detector article as a recent public example).
3.1 Jev vs existing text-to-text classification
Before continuing this discussion, though, let’s start with a quick Jev overview. Jev is a new model released by TypeSafe AI, which just came out of stealth a few weeks ago and got a lot of attention (at first, it seemed a bit bizarre because it looks just like a classifier).
Jev is a proprietary model (although the release was followed by a huge number of quick open-source clones, but we will get to this later) that is relatively cheap to use and claims to be on par with GPT-5.6 Luna (for decision-making) while being orders of magnitude faster and cheaper:
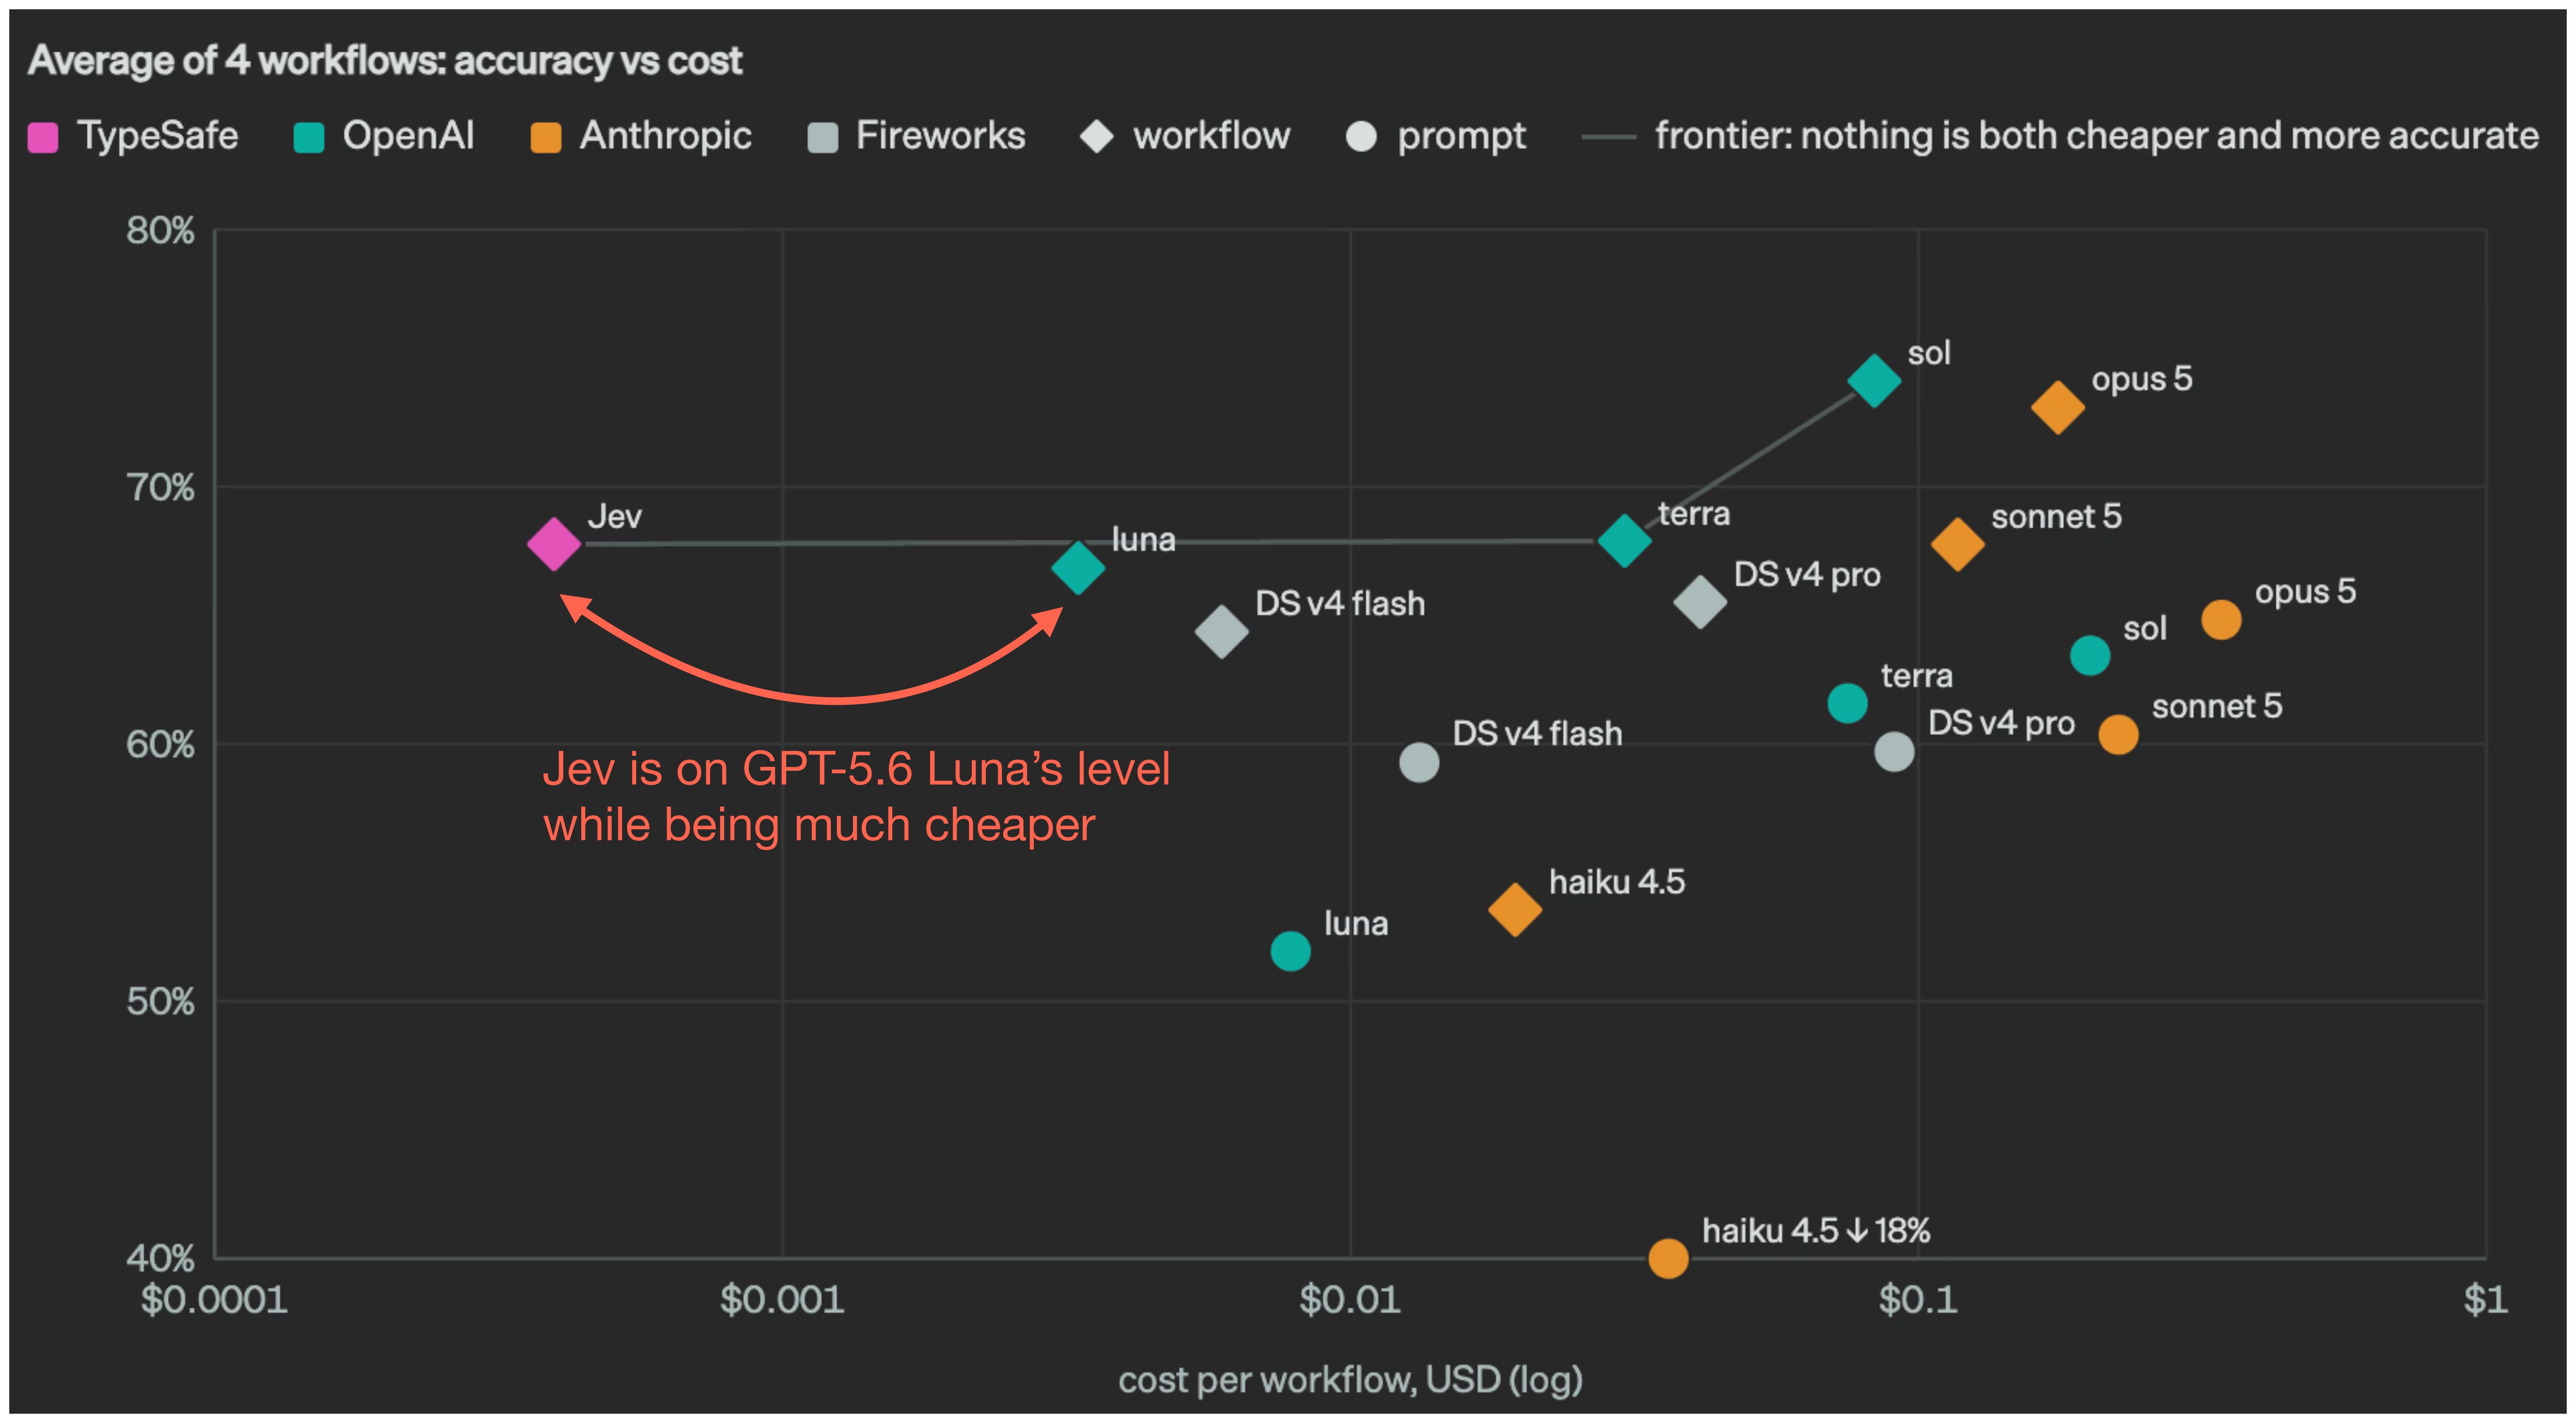
Here, regarding GPT-Luna, think of this as the text-to-text classification approach discussed earlier.
So why all this hype? I think it’s partly because of the nice API and that it performs so well on all kinds of tasks, so it doesn’t require custom fine-tuning.
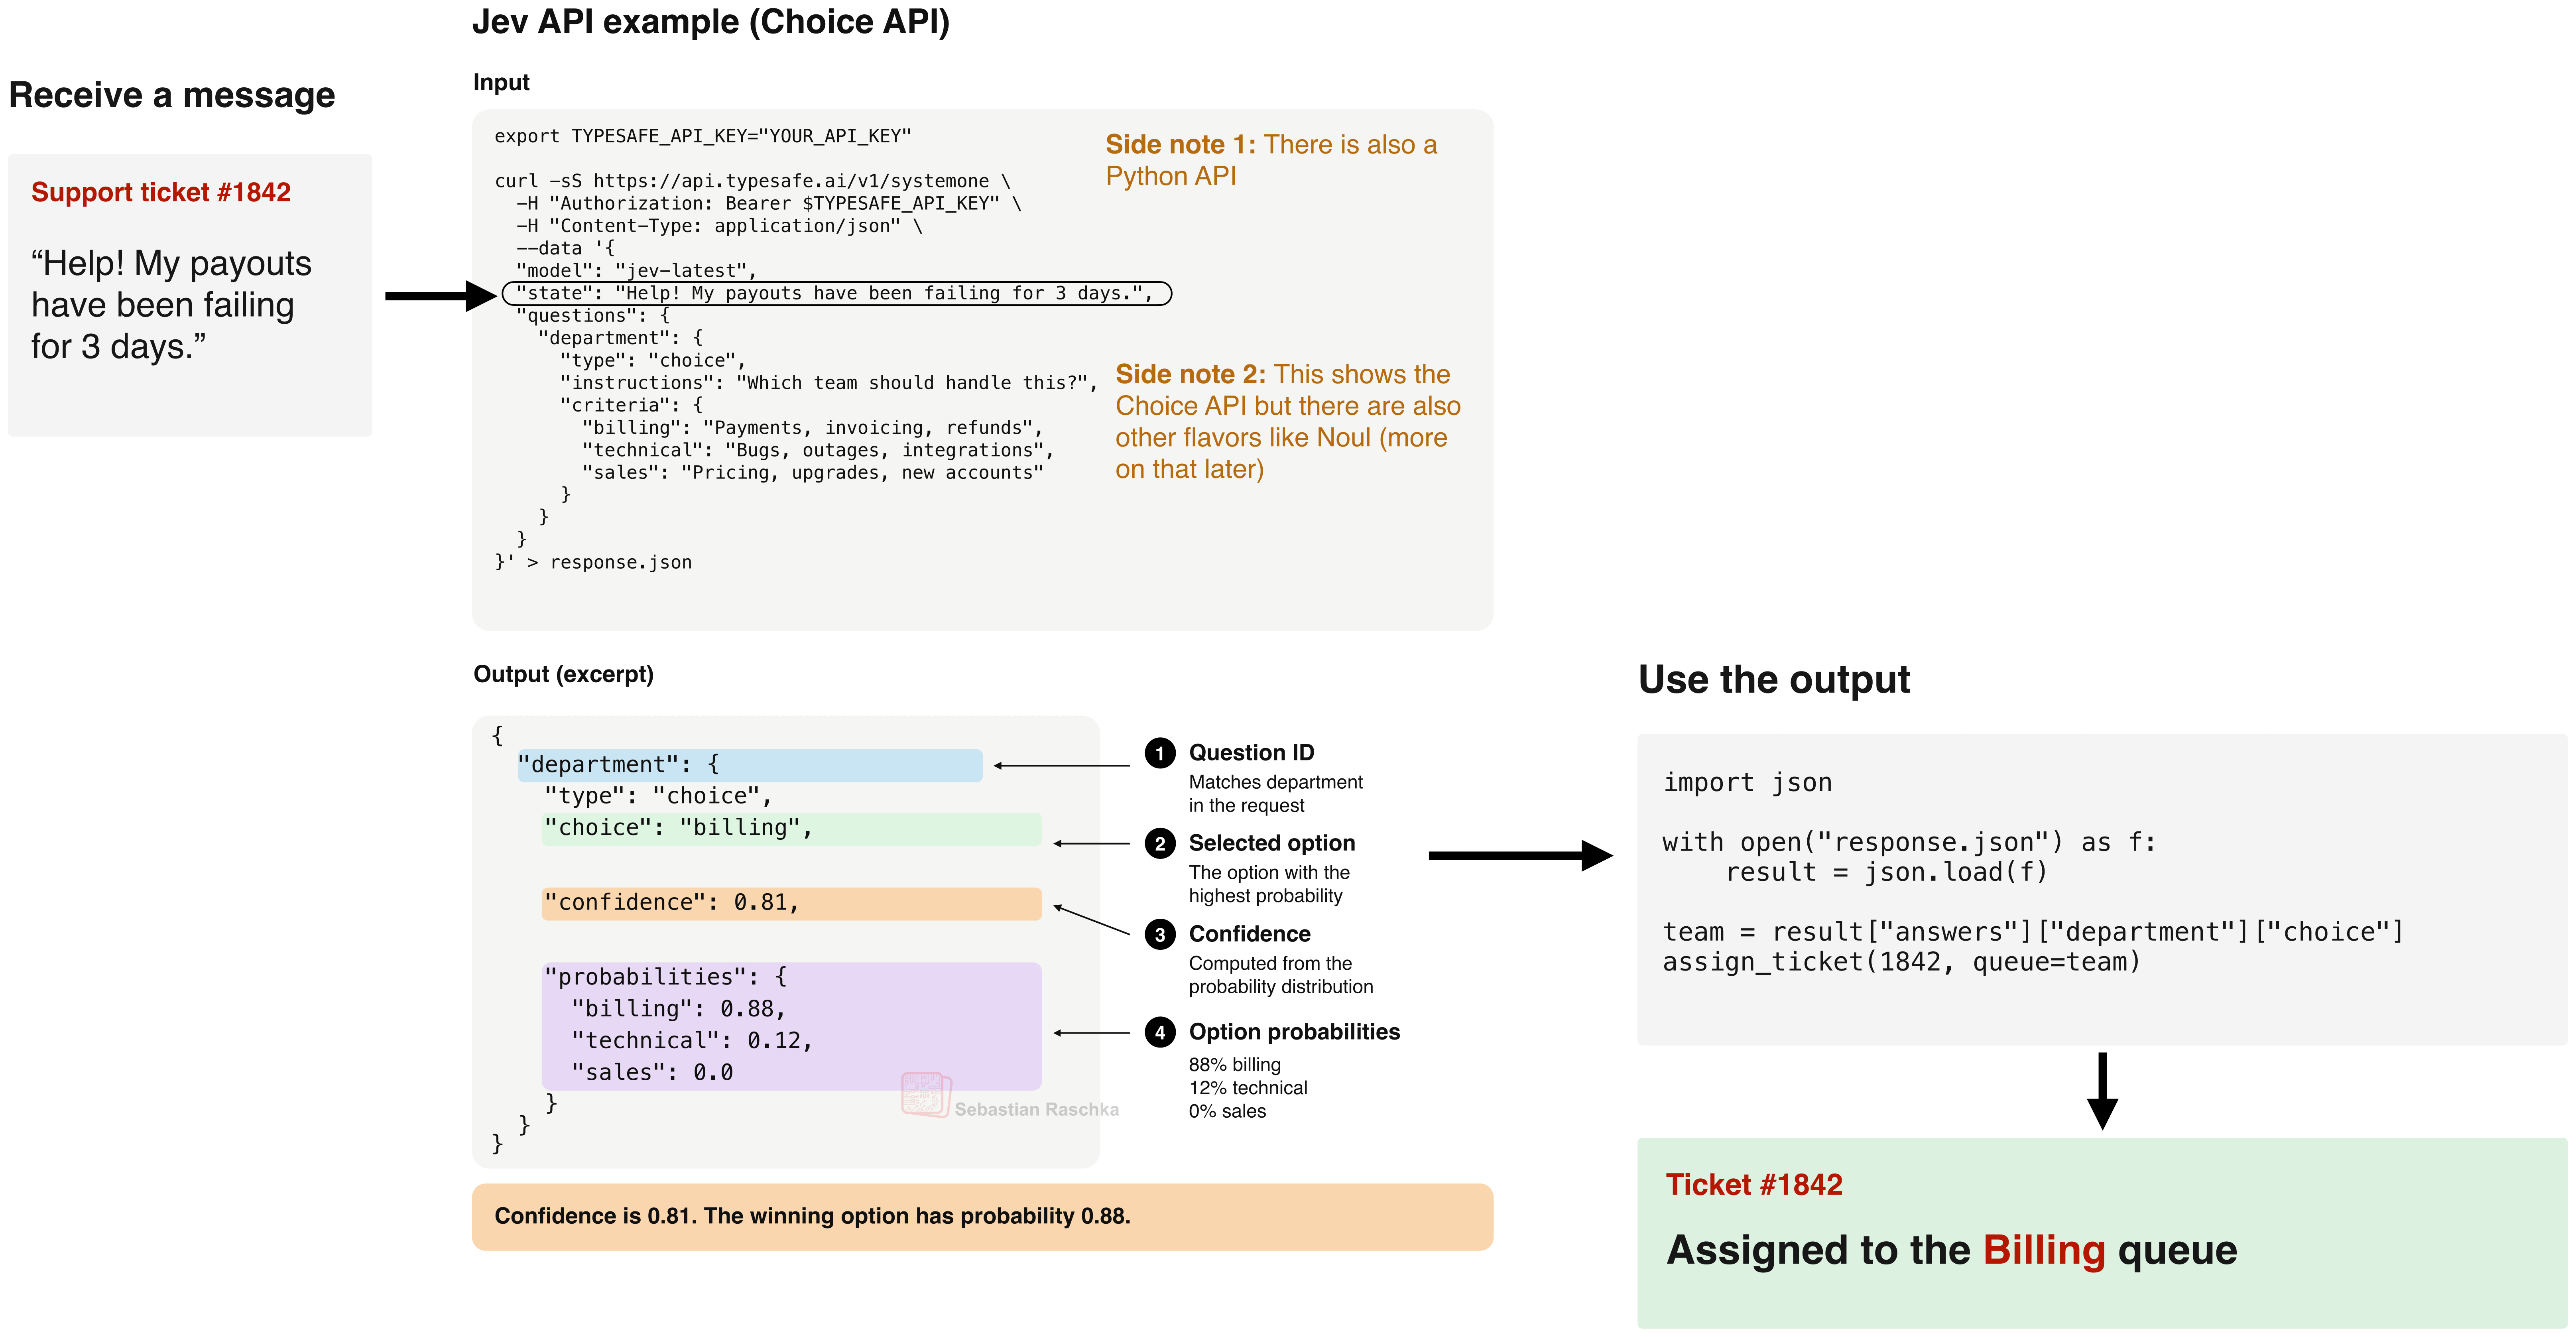
For example, I can use it to categorize support tickets/emails (I made a video version to show the response time):
Or, I can have the same model play Tetris in real-time (here, I am using the Choice API):
Maybe the best way to succinctly explain it (before getting into technical details) is as follows: Like ChatGPT in 2022 was exciting because it was a general-purpose chat model that could generate all kinds of texts, one of the reasons the tech community is excited about Jev is that it is the ChatGPT moment for classification, where it can cheaply classify all kinds of text inputs without having to fine-tune a custom classifier for each task.
(As of this writing, there’s not much known about the architecture and exact training algorithm, except that one of the founders said it was trained via “Reinforcement Learning for Calibrated Decisions”, but more on that later.)
3.2 The Jev API
Over the past few years, we’ve gotten used to throwing bigger, better, and more expensive GPT-style LLMs at all kinds of problems, and for targeted decision-making or classification tasks, a cheap & fast approach like Jev may feel refreshing to most. Especially for one-off tasks where collecting training data and fine-tuning a custom ModernBERT sounds too tedious, we might just throw a Luna-like model at it.
But on top of being popular for its versatility (that is, performing well on different target domains out of the box), Jev also has a relatively nice API which we can use via curl in the terminal or via its Python API.
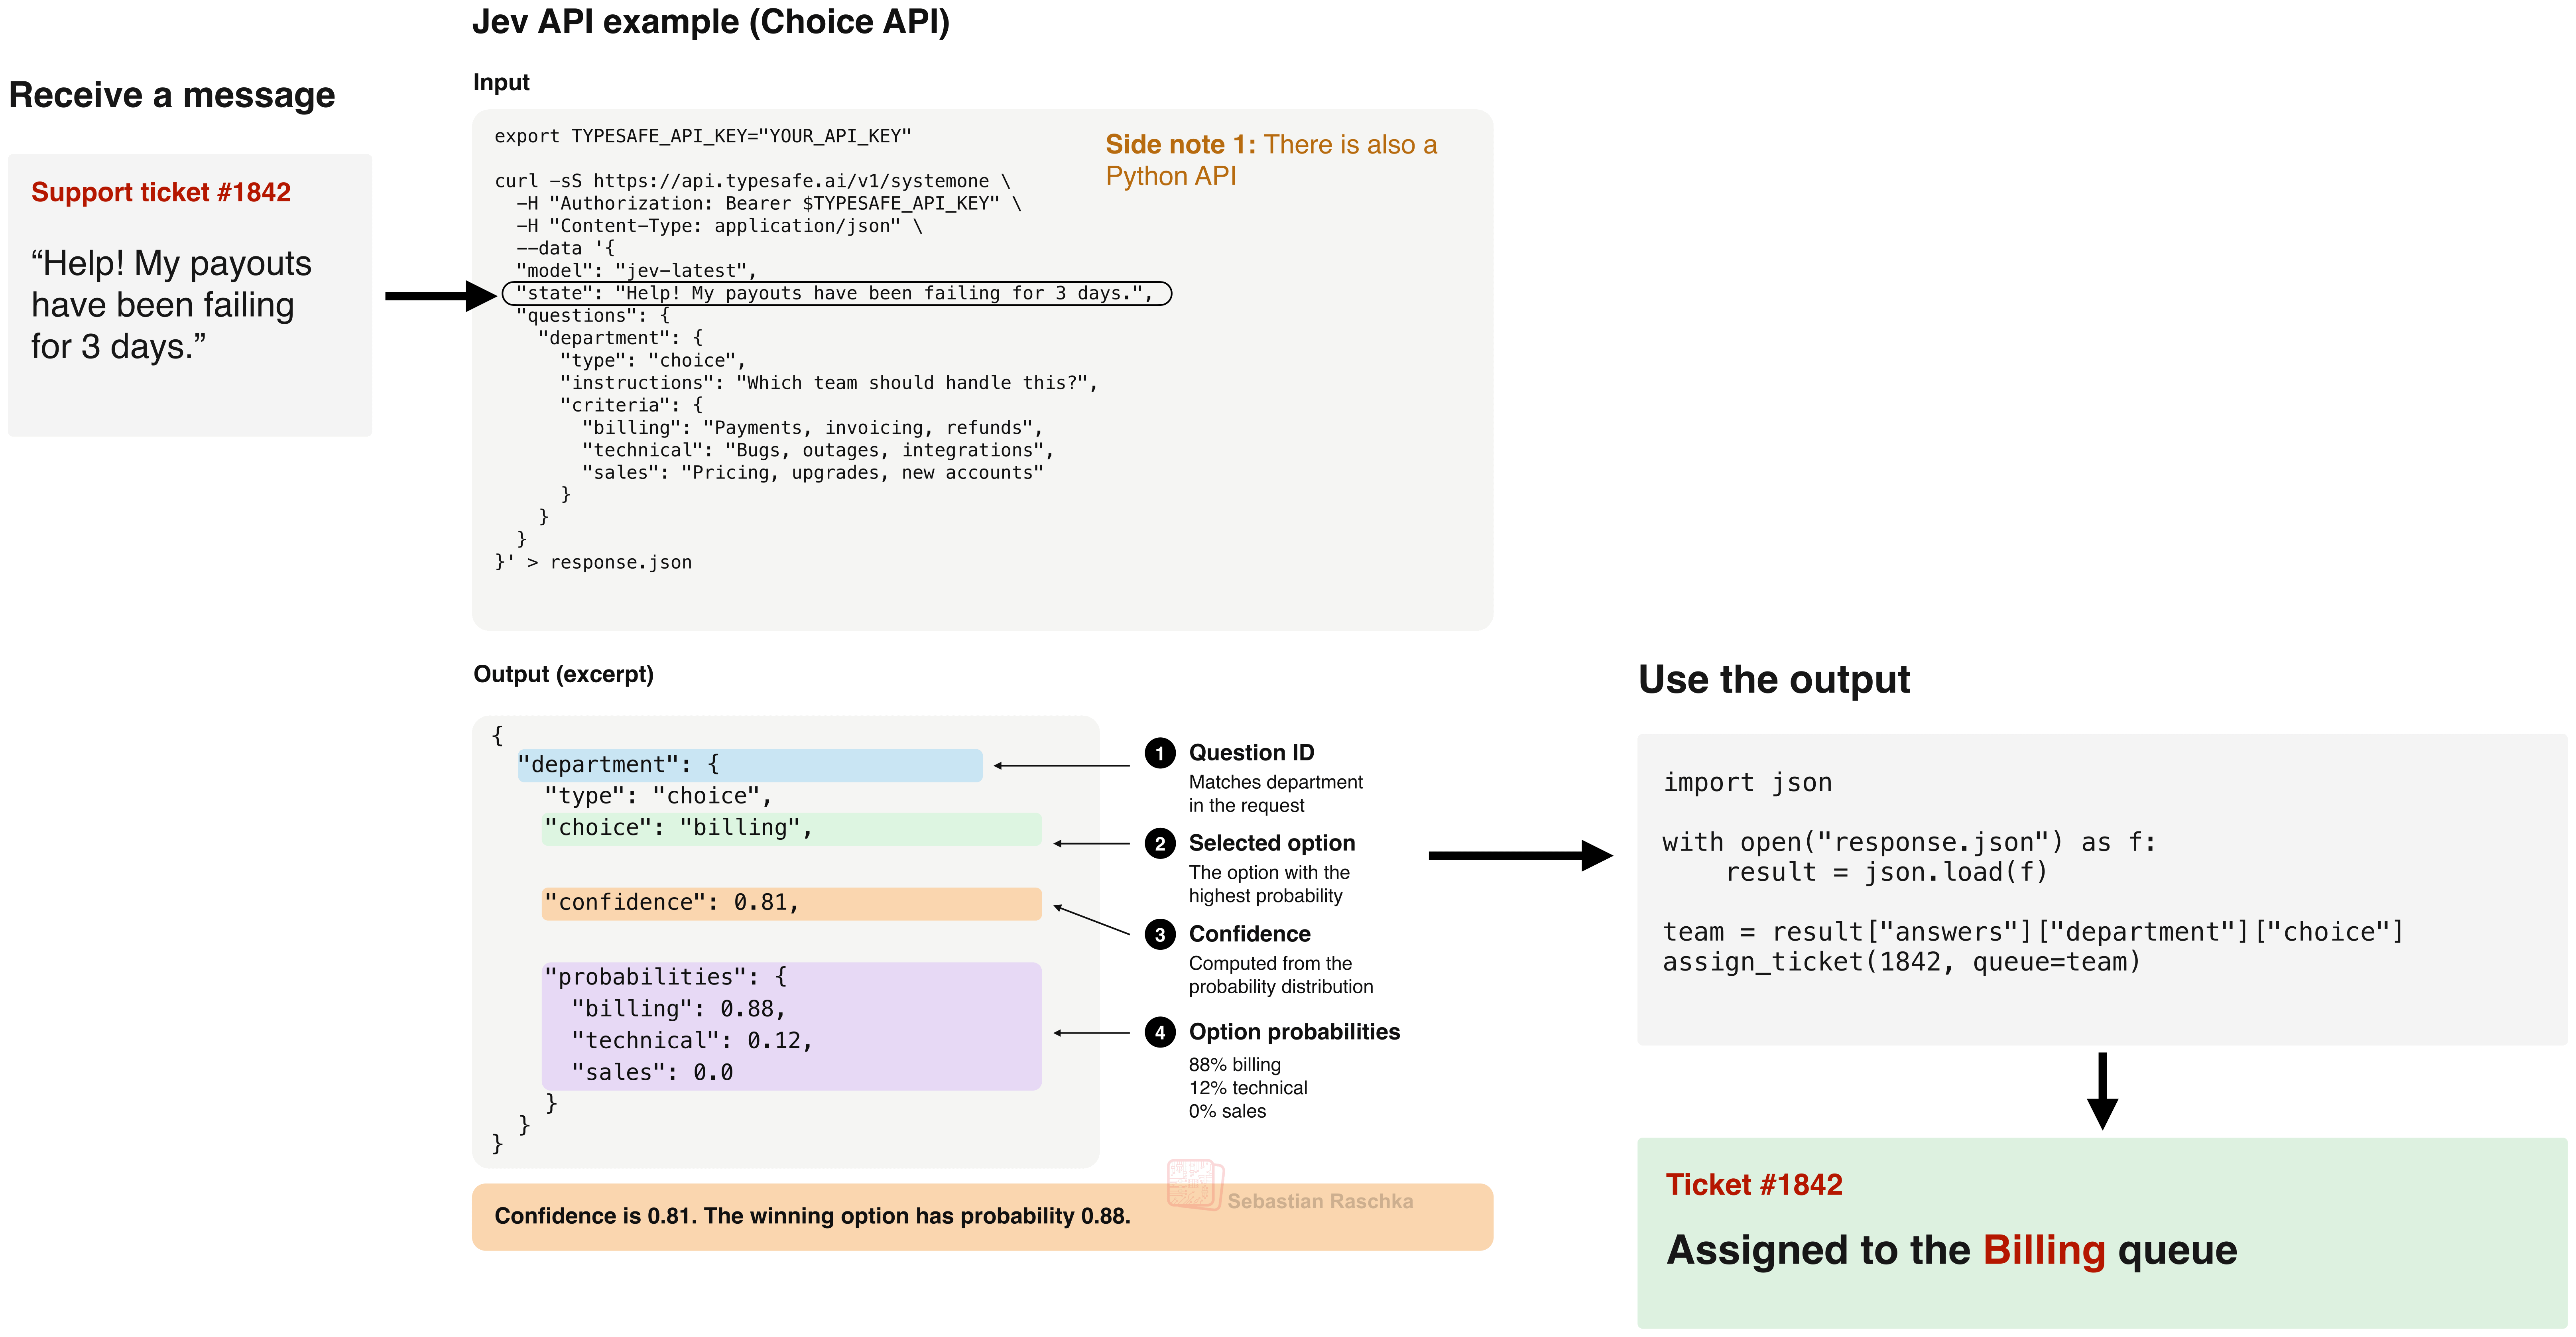
In short, there are three main API types illustrated below. Let’s start with the Choice API, which is convenient for multi-class classification.
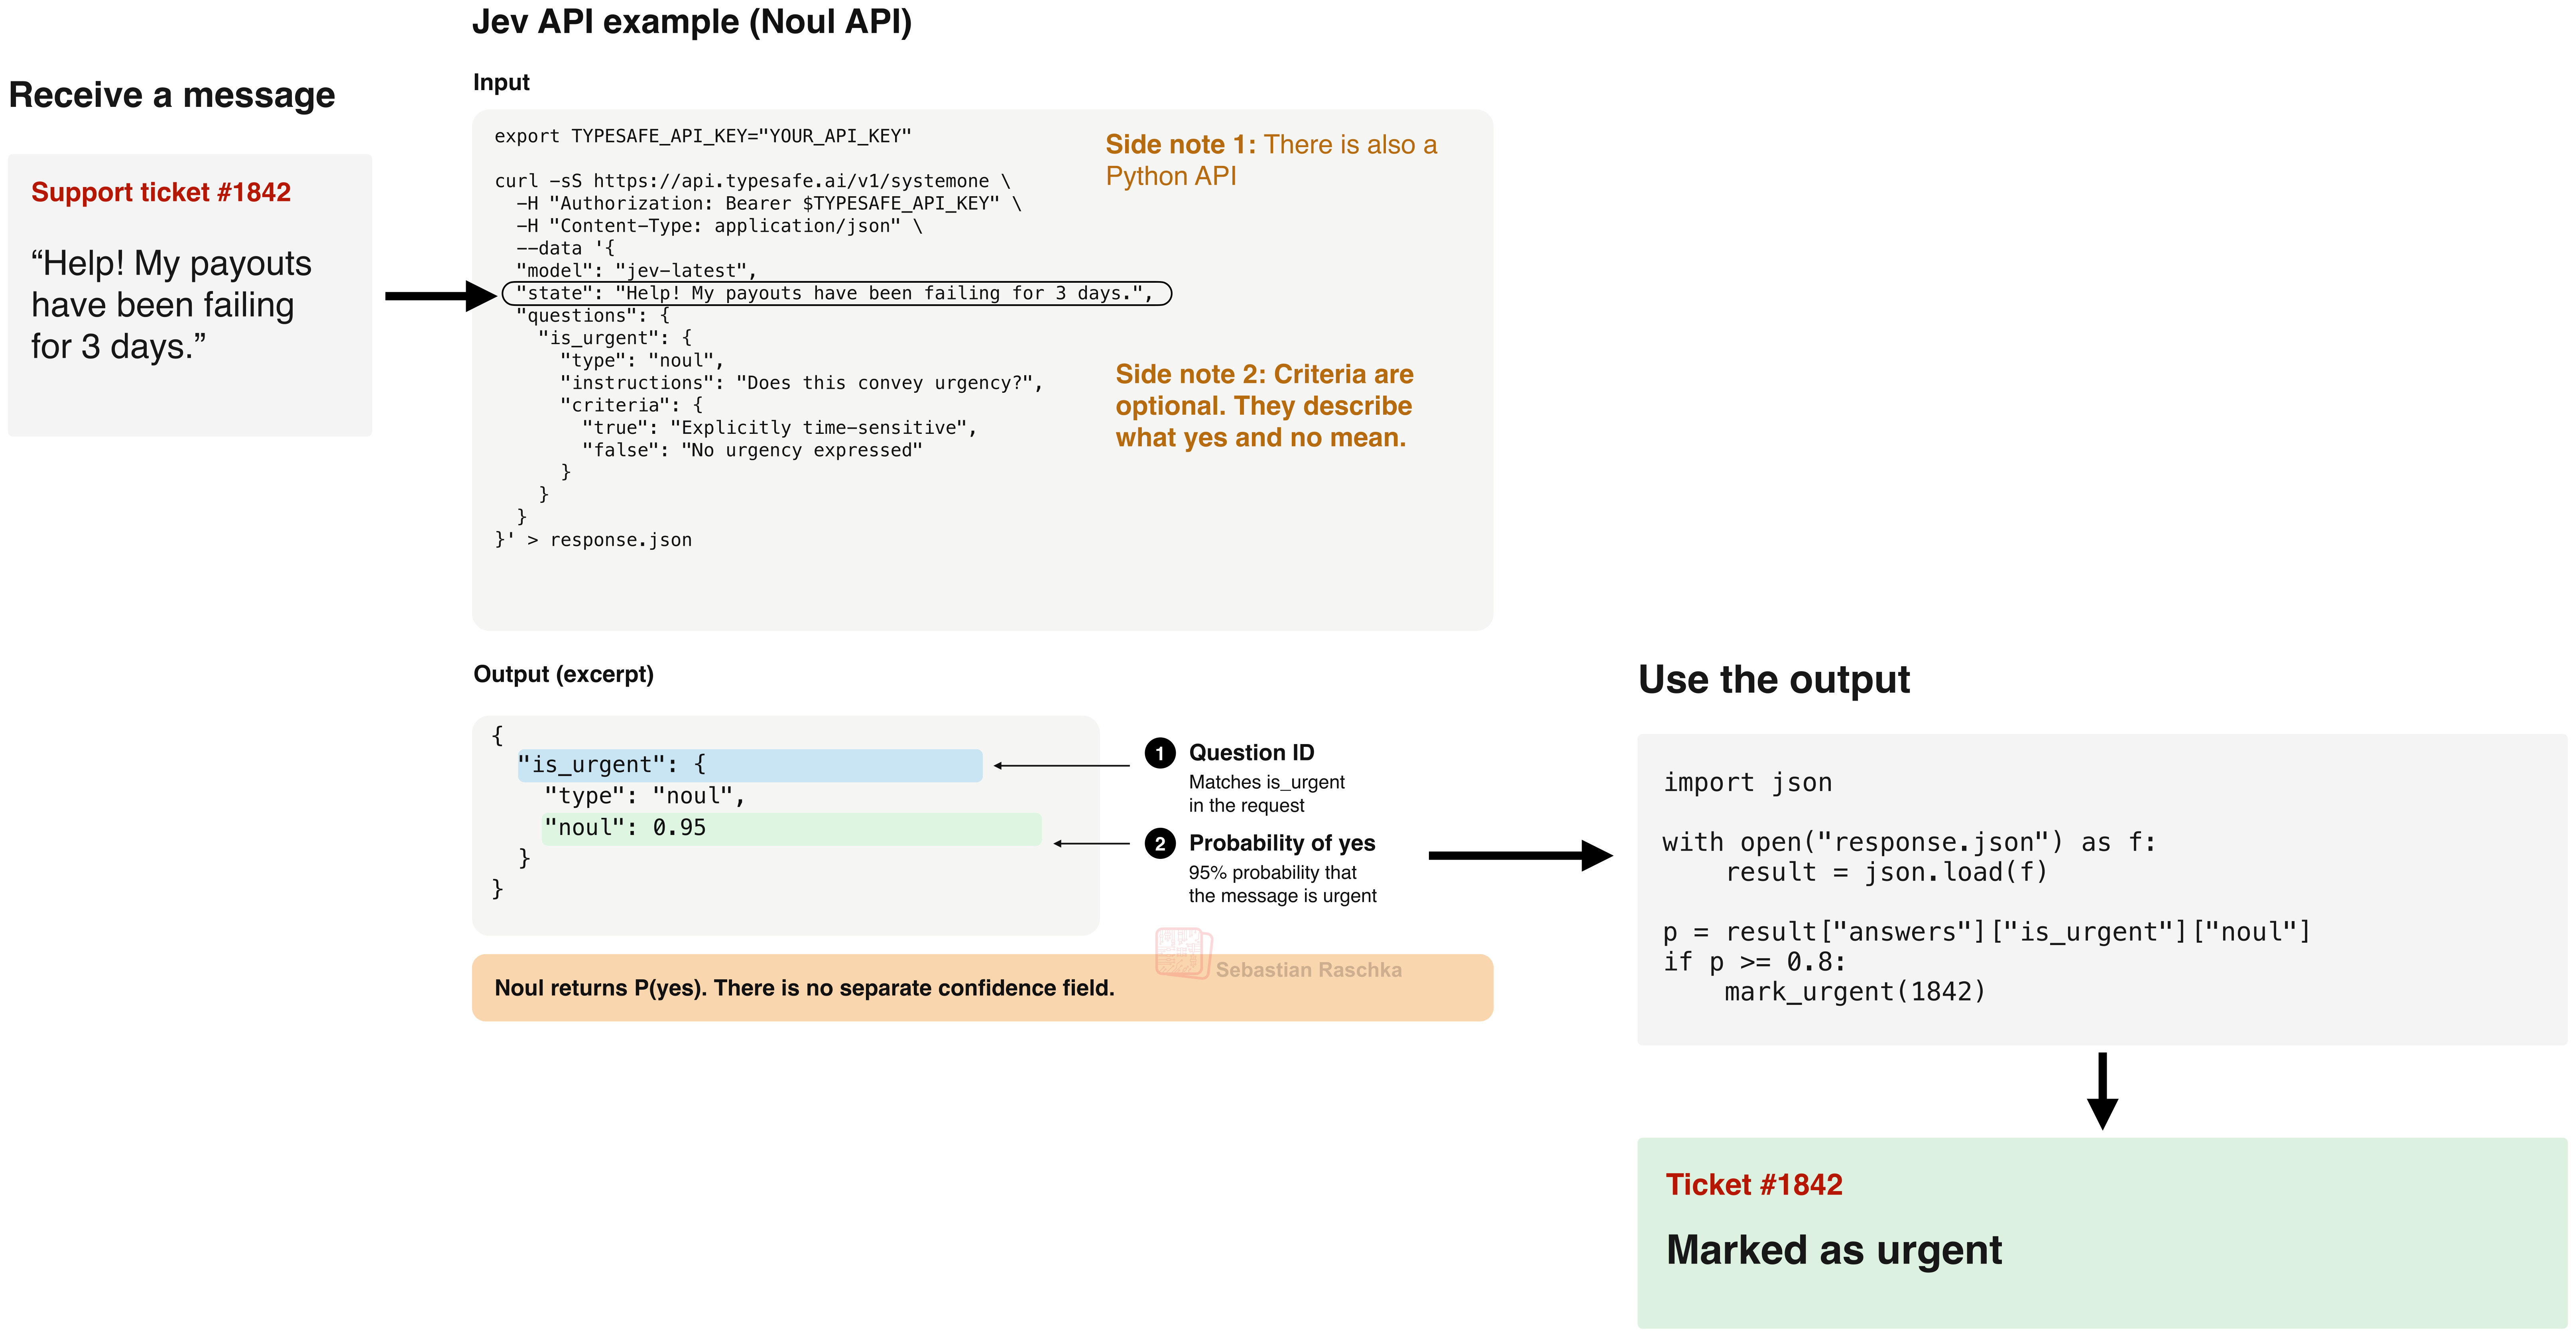
Next is the Noul API, which is simpler and assigns a “yes” probability to a question.
Lastly, the Score API assigns a score based on a rubric level (in the example below, 0, 1, 2).
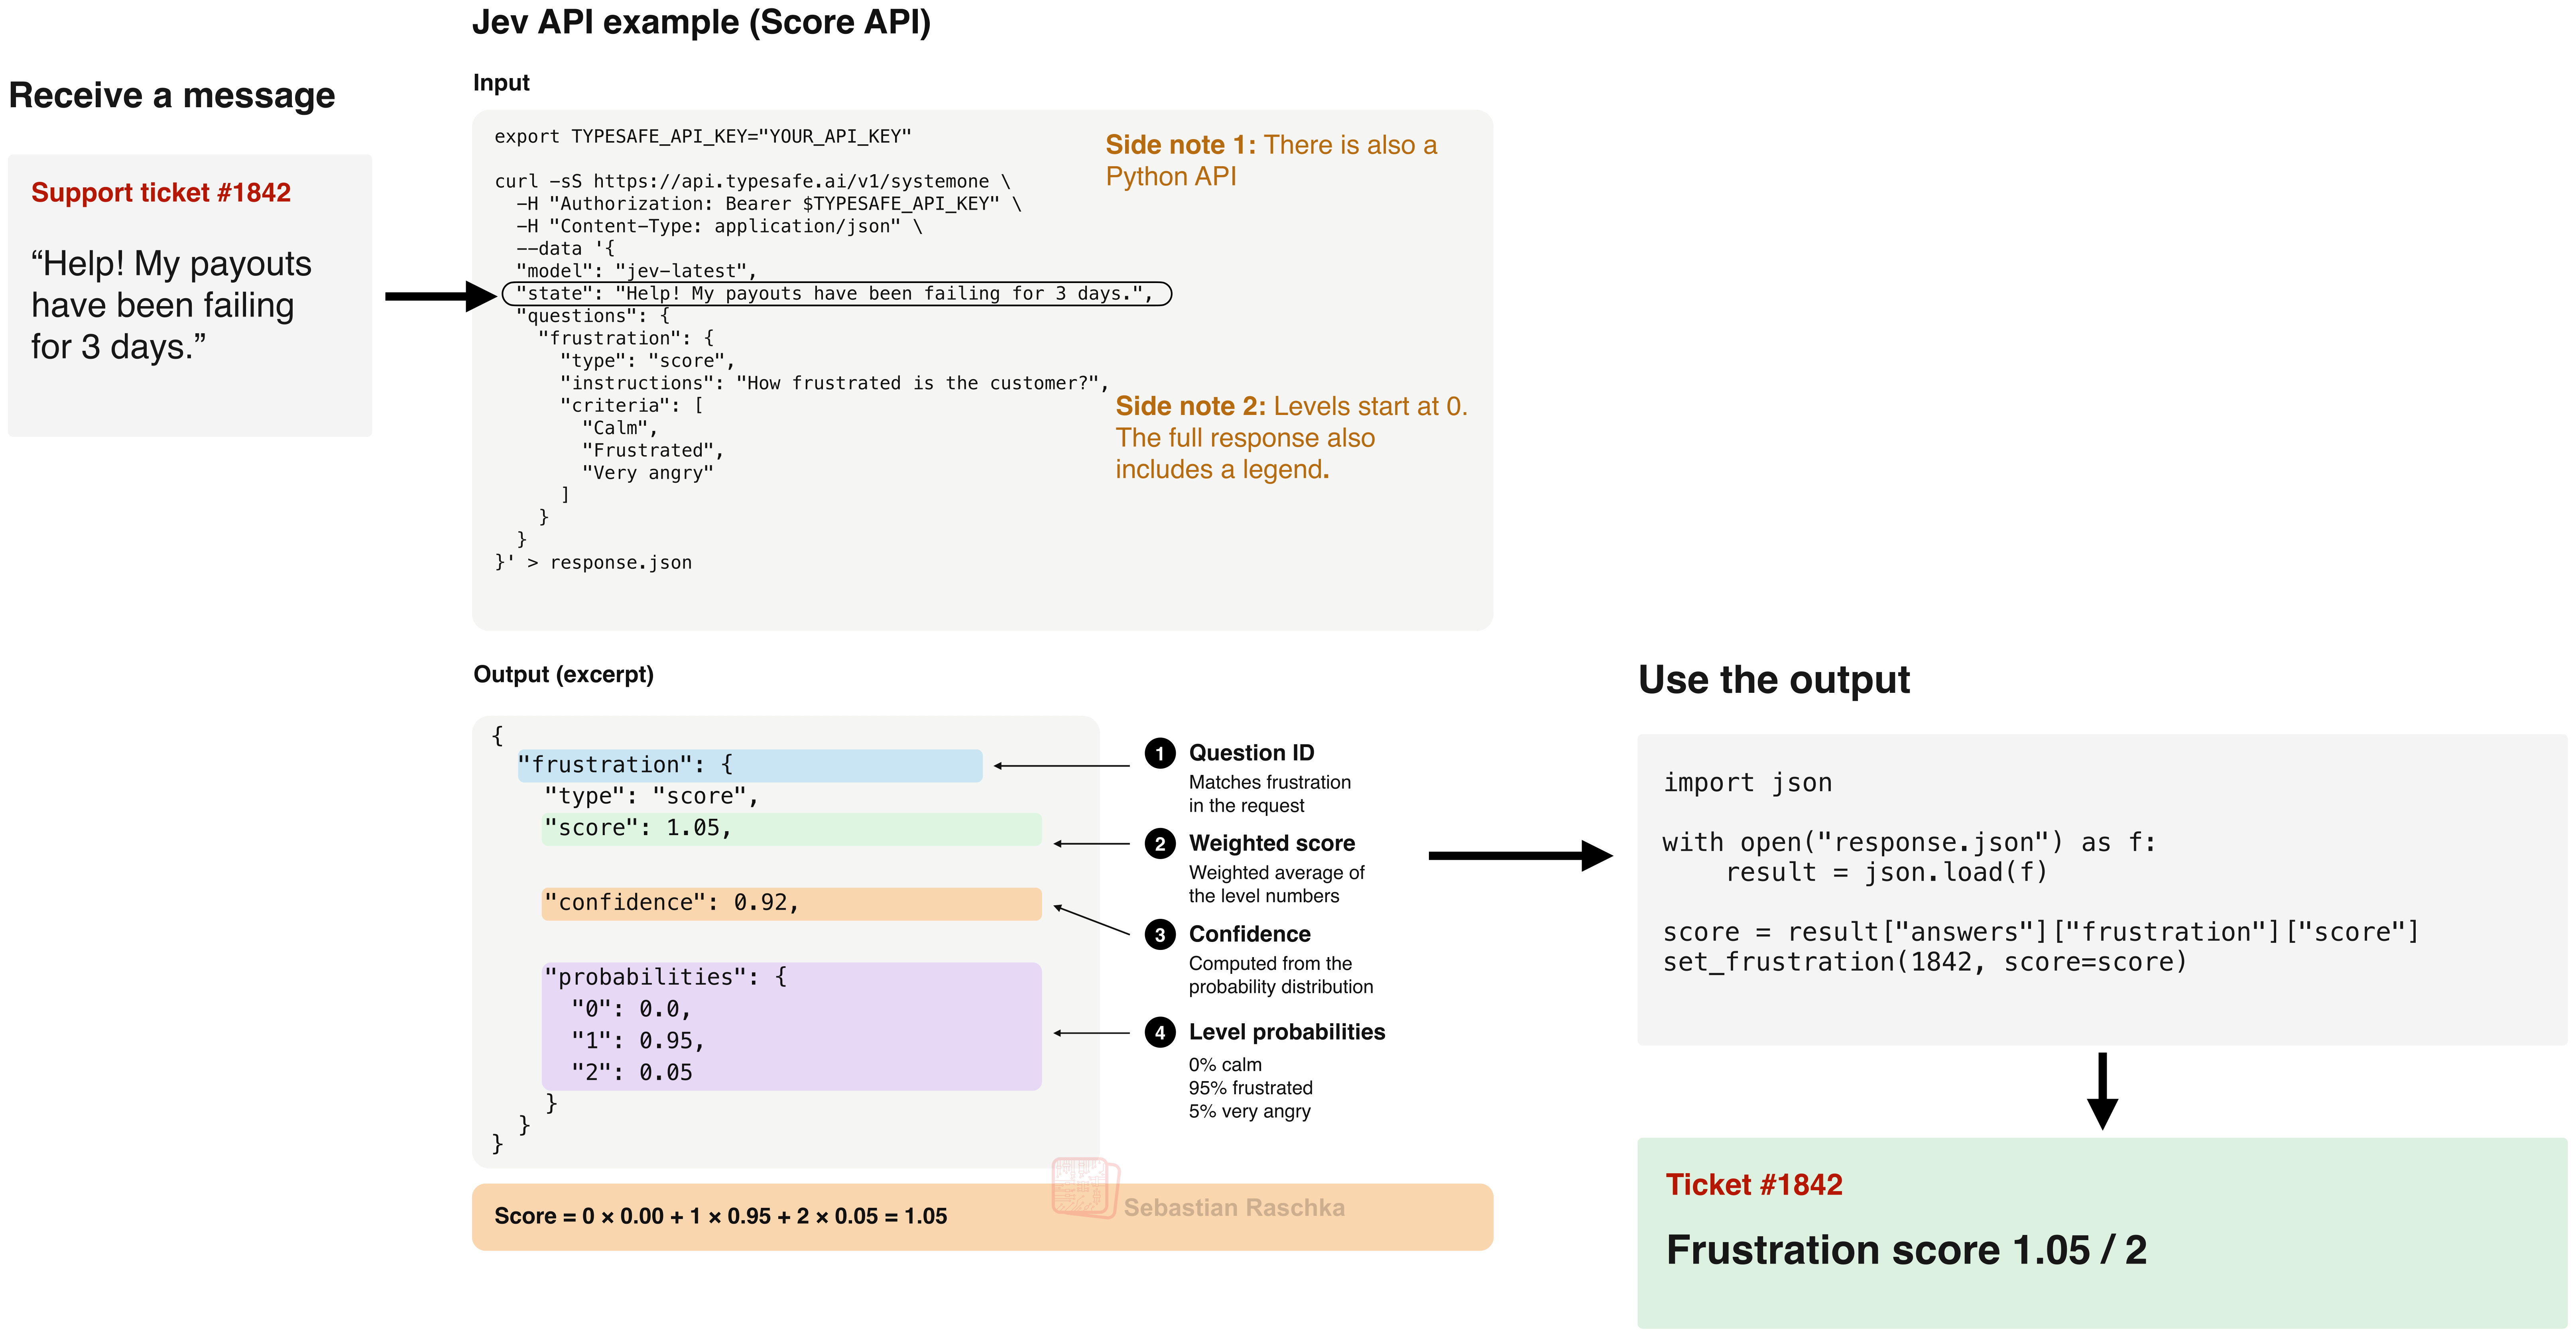
To sum it up, the different APIs and use cases are as follows.
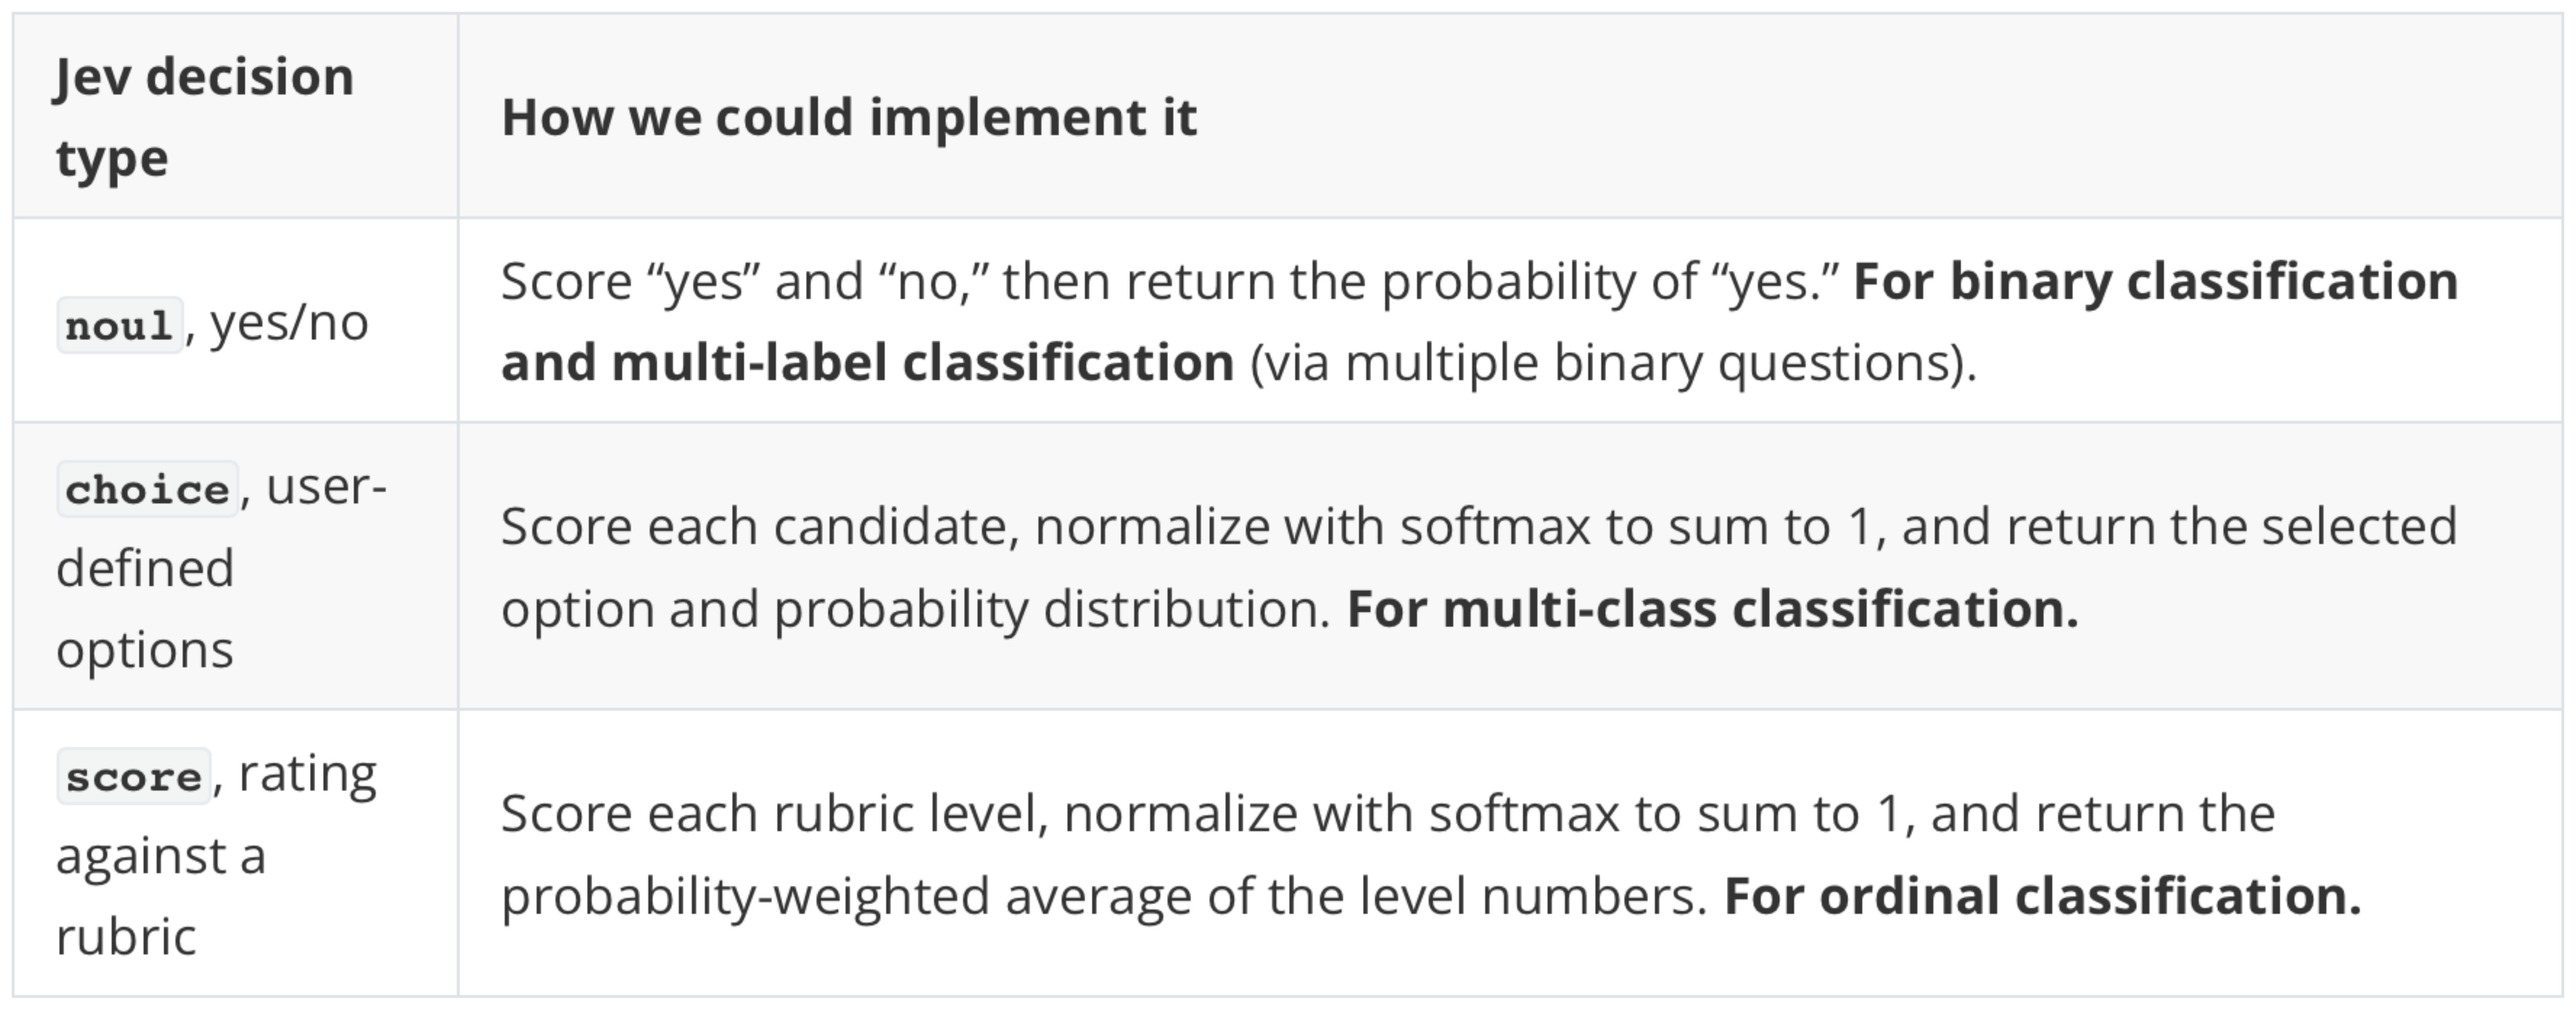
3.3 Jev classifying IMDb
To make these APIs more concrete, and to answer the question of how well Jev might do on the aforementioned IMDb dataset, we can run it with either the Choice or Noul API.
Let’s start with the Choice API first. Each review would be formatted as follows:
export TYPESAFE_API_KEY="YOUR_API_KEY"

curl -sS https://api.typesafe.ai/v1/systemone \
  -H "Authorization: Bearer $TYPESAFE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "jev-1.13.0",
    "state": "The acting was excellent and the story kept me engaged throughout. I would happily watch this movie again.",
    "questions": {
      "sentiment": {
        "type": "choice",
        "instructions": "What is the overall sentiment of this movie review?",
        "criteria": {
          "negative": "An overall unfavorable opinion of the movie",
          "positive": "An overall favorable opinion of the movie"
        }
      }
    }
  }'
This Choice API is convenient if we want to use explicit labels for binary (here) or multi-class problems.
An actual response might look as follows:
{
  "model": "jev-1.13.0",
  "answers": {
    "sentiment": {
      "type": "choice",
      "choice": "positive",
      "confidence": 1.0,
      "probabilities": {
        "negative": 0.0,
        "positive": 1.0
      }
    }
  },
  "usage": {
    "input_tokens": 342,
    "output_tokens": 32
  }
}
Along with the "choice": "positive" label, we also get the confidence for this prediction, which can be really useful in real-world applications, as well as the probabilities for each class. (The confidence field summarizes how concentrated the probability distribution is. It is different from the probability assigned to the winning class.) One of the selling points of Jev is that, according to the documentation, these are well-calibrated (but more on calibration later).
Alternatively, we can also use the Noul API here to classify the reviews. Using the same movie review classification context, the format would be as follows:
curl -sS https://api.typesafe.ai/v1/systemone \
  -H "Authorization: Bearer $TYPESAFE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "jev-1.13.0",
    "state": "The acting was excellent and the story kept me engaged throughout. I would happily watch this movie again.",
    "questions": {
      "is_positive": {
        "type": "noul",
        "instructions": "Does this review express an overall positive opinion of the movie?",
        "criteria": {
          "true": "An overall favorable opinion of the movie",
          "false": "An overall unfavorable opinion of the movie"
        }
      }
    }
  }'
And the answer via the Noul API is:
{
  "model": "jev-1.13.0",
  "answers": {
    "is_positive": {
      "type": "noul",
      "noul": 0.98
    }
  },
  "usage": {
    "input_tokens": 328,
    "output_tokens": 21
  }
}
(Interestingly, it gives 0.98 instead of 1.0 for the positive class, even though it’s the same text.)
We can also apply the Noul API to multiple classes by asking one question per class, for example:
“Is this article about finance?”
“Is this article about politics?”
“Is this article about technology?”
Here, each question (independently from each other) returns a probability, and these probabilities don’t have to sum to 1. So, for a multi-class classification where each text can have multiple labels, we may prefer Noul, and for classification problems with only one final answer, Choice adds more convenience.
Now, running Jev with either Choice or Noul on the 25,000 movie reviews on the test set gave the following results:
Choice:
Accuracy 96.47% (24,117 correct)
Total runtime: 22 minutes 24 seconds
15,456,663 input tokens, $0.6492 total cost
Noul:
Accuracy 96.20% (24,050 correct)
Total runtime: 23 minutes 3 seconds
15,106,663 input tokens, $0.6345 total cost
Note that the small difference in performance and runtime between Choice and Noul could be due to random fluctuation since, similar to other LLMs, the runs are not fully deterministic.
For instance, I ran the Choice API a second time over the same test set and got slightly different results, as shown below.
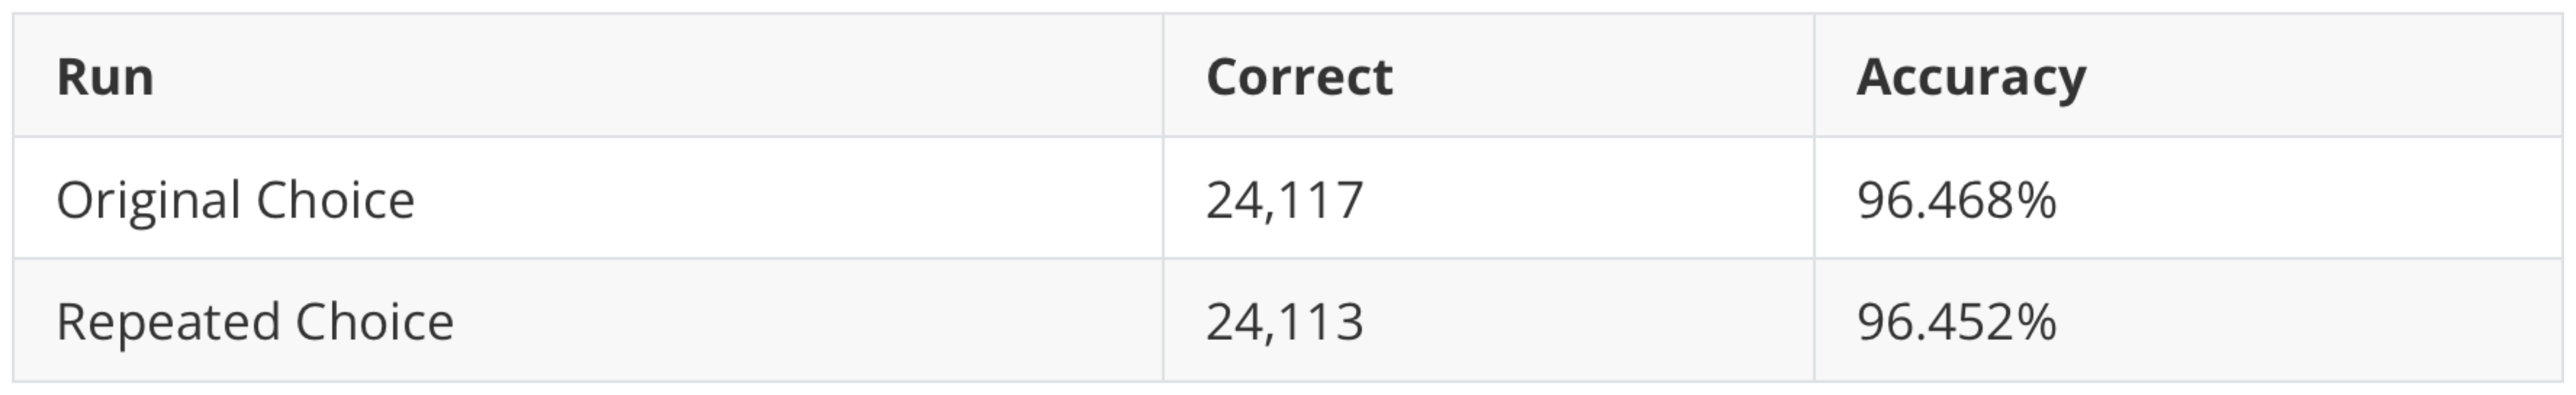
(The non-determinism when serving LLMs and other models at scale is likely due to batch-dependent GPU kernel execution changing the order of floating-point operations, as laid out in a nice blog post by Horace He last year.)
Anyways, the results look quite good overall (caveat: we don’t know if the IMDb test set was part of the training set).
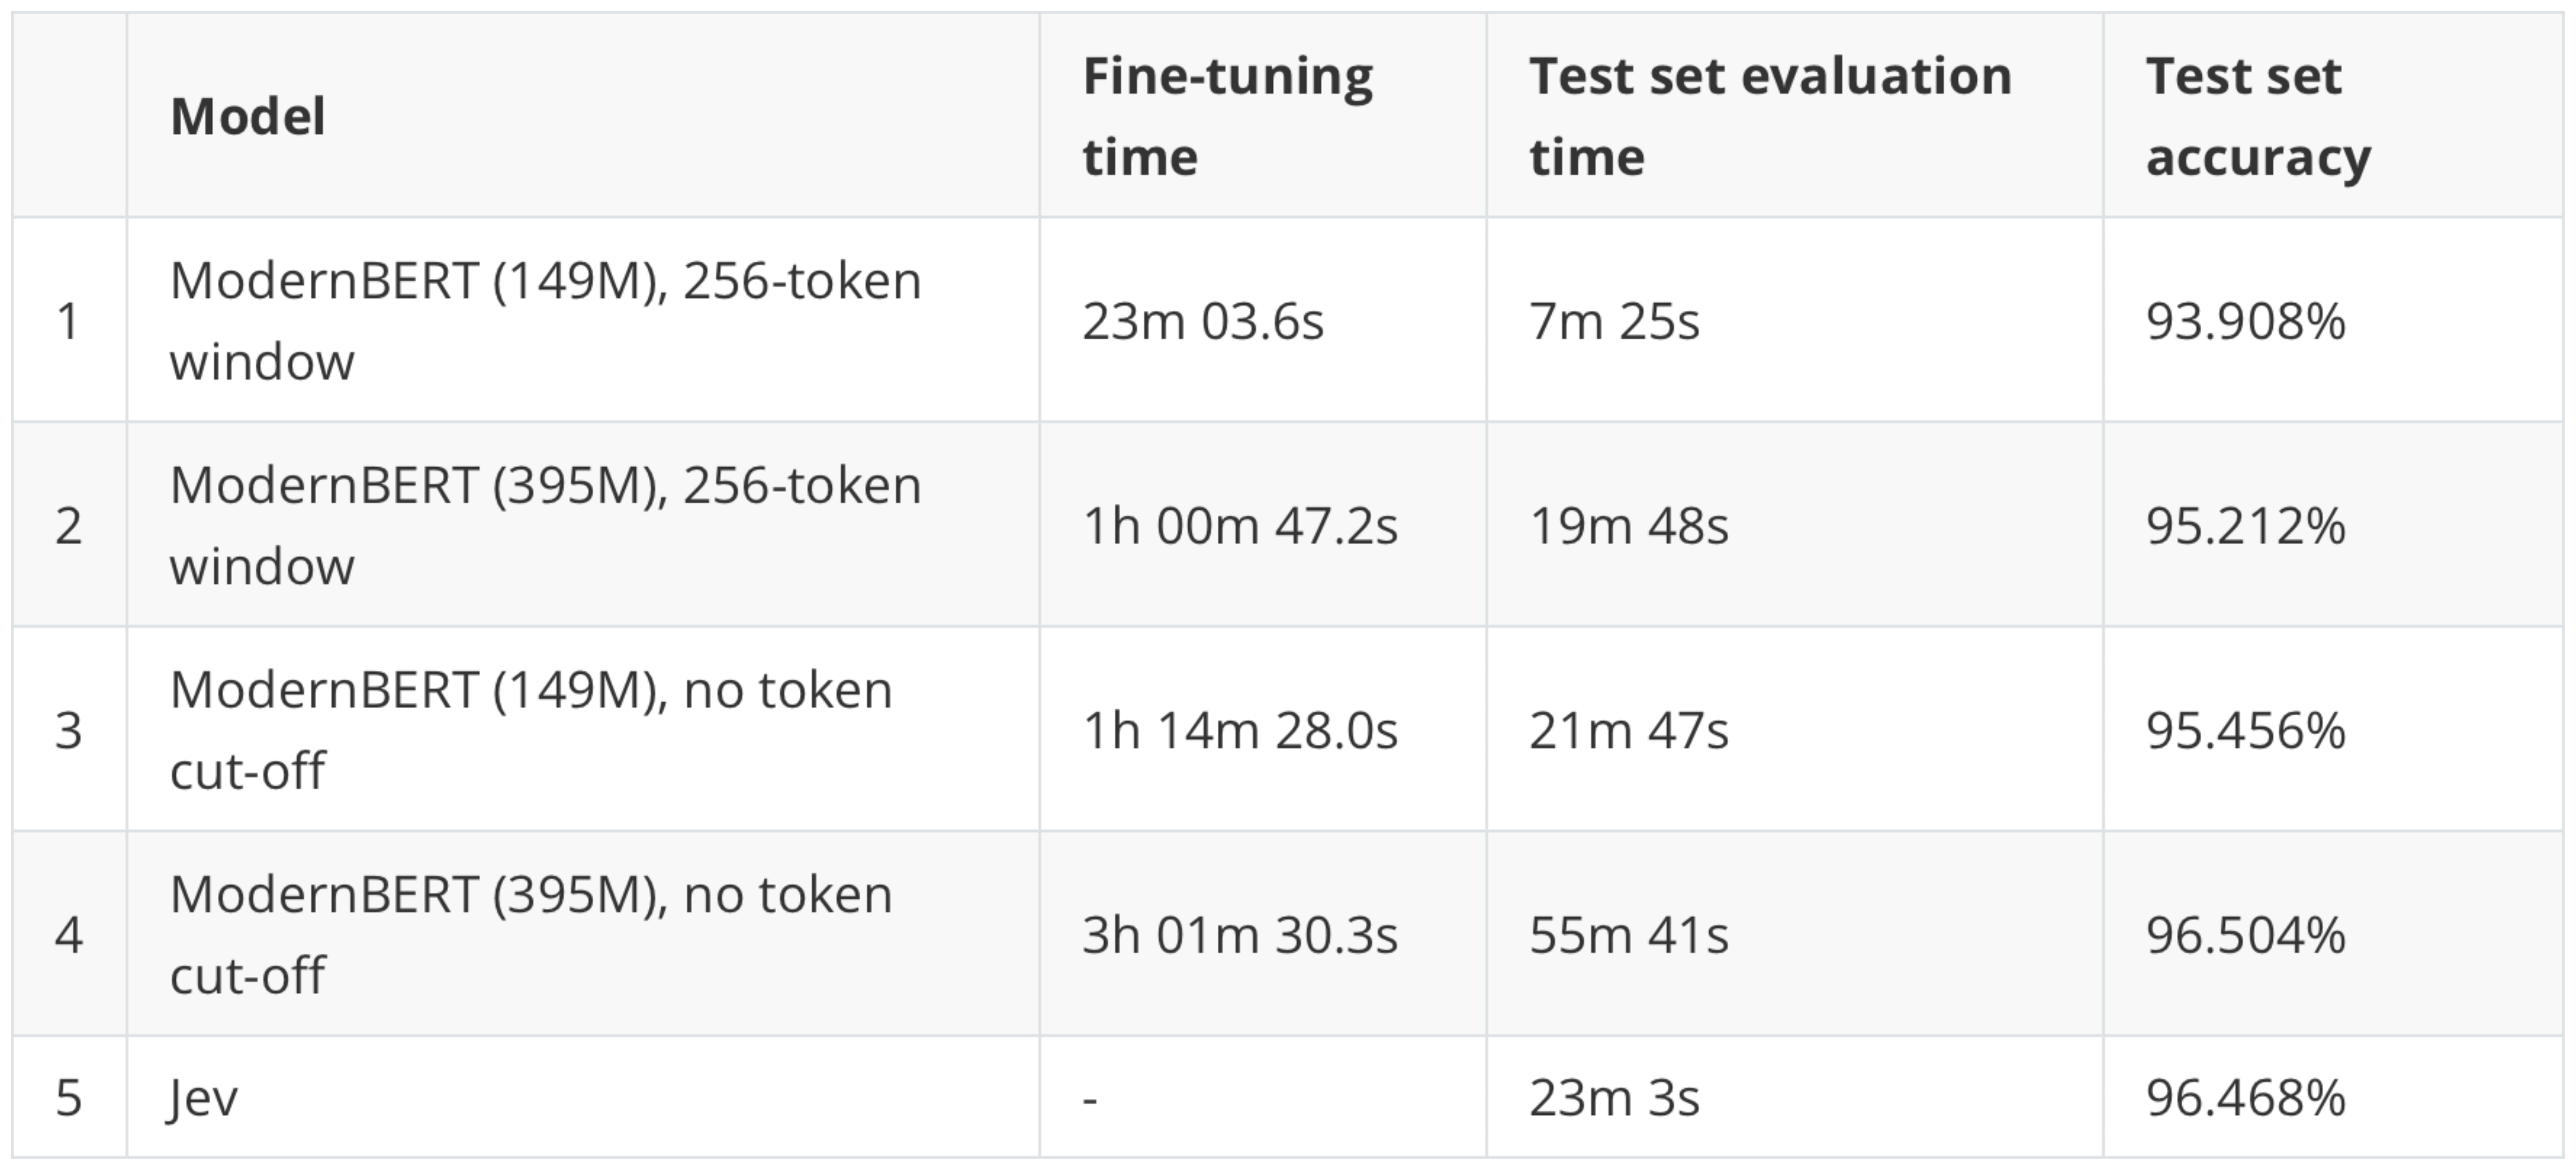
For reference, a ModernBERT model took
23 min to fine-tune on the training set;
7 min to evaluate on the test set.
For comparison, the best ModernBERT model has similar accuracy, as shown below (I expect you can still get 1-2% higher accuracy with additional hyperparameter tuning). Note that this was run on a DGX Spark, and it’s possible to get faster inference performance with quantization and faster hardware.
But our ModernBERT model can’t play Tetris, for example, or do anything else besides movie classification without us fine-tuning it for the new task. But we could then throw a GPT-5.6 Luna or GPT-6 Luna model at it (which is a bit slower and also more expensive).
A classic rule of thumb was:
Use a cheap LLM (like GPT-6 Luna) for one-off decision-making tasks;
Fine-tune a custom classifier if we want to do this task repeatedly.
Now, something like Jev could take the place of the above to a) reduce latency and save money over Luna and b) save us the work of fine-tuning a custom model. (Although if we have a very high-volume task and we want to maximize speed and accuracy on a very specific task, it, of course, still makes sense to fine-tune.)
4. BERT- and GPT-style models with Jev API
Of course, we could also be adding a Jev-like API on top of a (Modern)BERT or any GPT-style model. Adding a Jev-like API is pretty straightforward. In fact, as soon as Jev was released, I built a Jev-like ModernBERT model to show how simple it is to build your own Jev model.
I decided not to release my Jev clone because I changed my mind in the meantime. I.e., it’s trivial to put a Jev-like API on top of ModernBERT, and it’s trivial to fine-tune it on a bunch of classification tasks. But it’s not trivial to make this model work well on all different kinds of tasks (like Tetris) without extensive training and testing. (Also, there are already enough quick Jev clones riding on the hype train by now; the world doesn’t need another quick clone, but a strong open-weight version would be nice, of course.)
However, if you are interested in how that retrofitting would work, here is a quick overview. For example, we can implement a Jev-like Choice API by adding a small classification head to any BERT-, GPT-, or T5-style model as illustrated earlier. But instead of having the output nodes in this head match the number of classes, we have it with only 1 output node, as illustrated for the modified GPT model below.
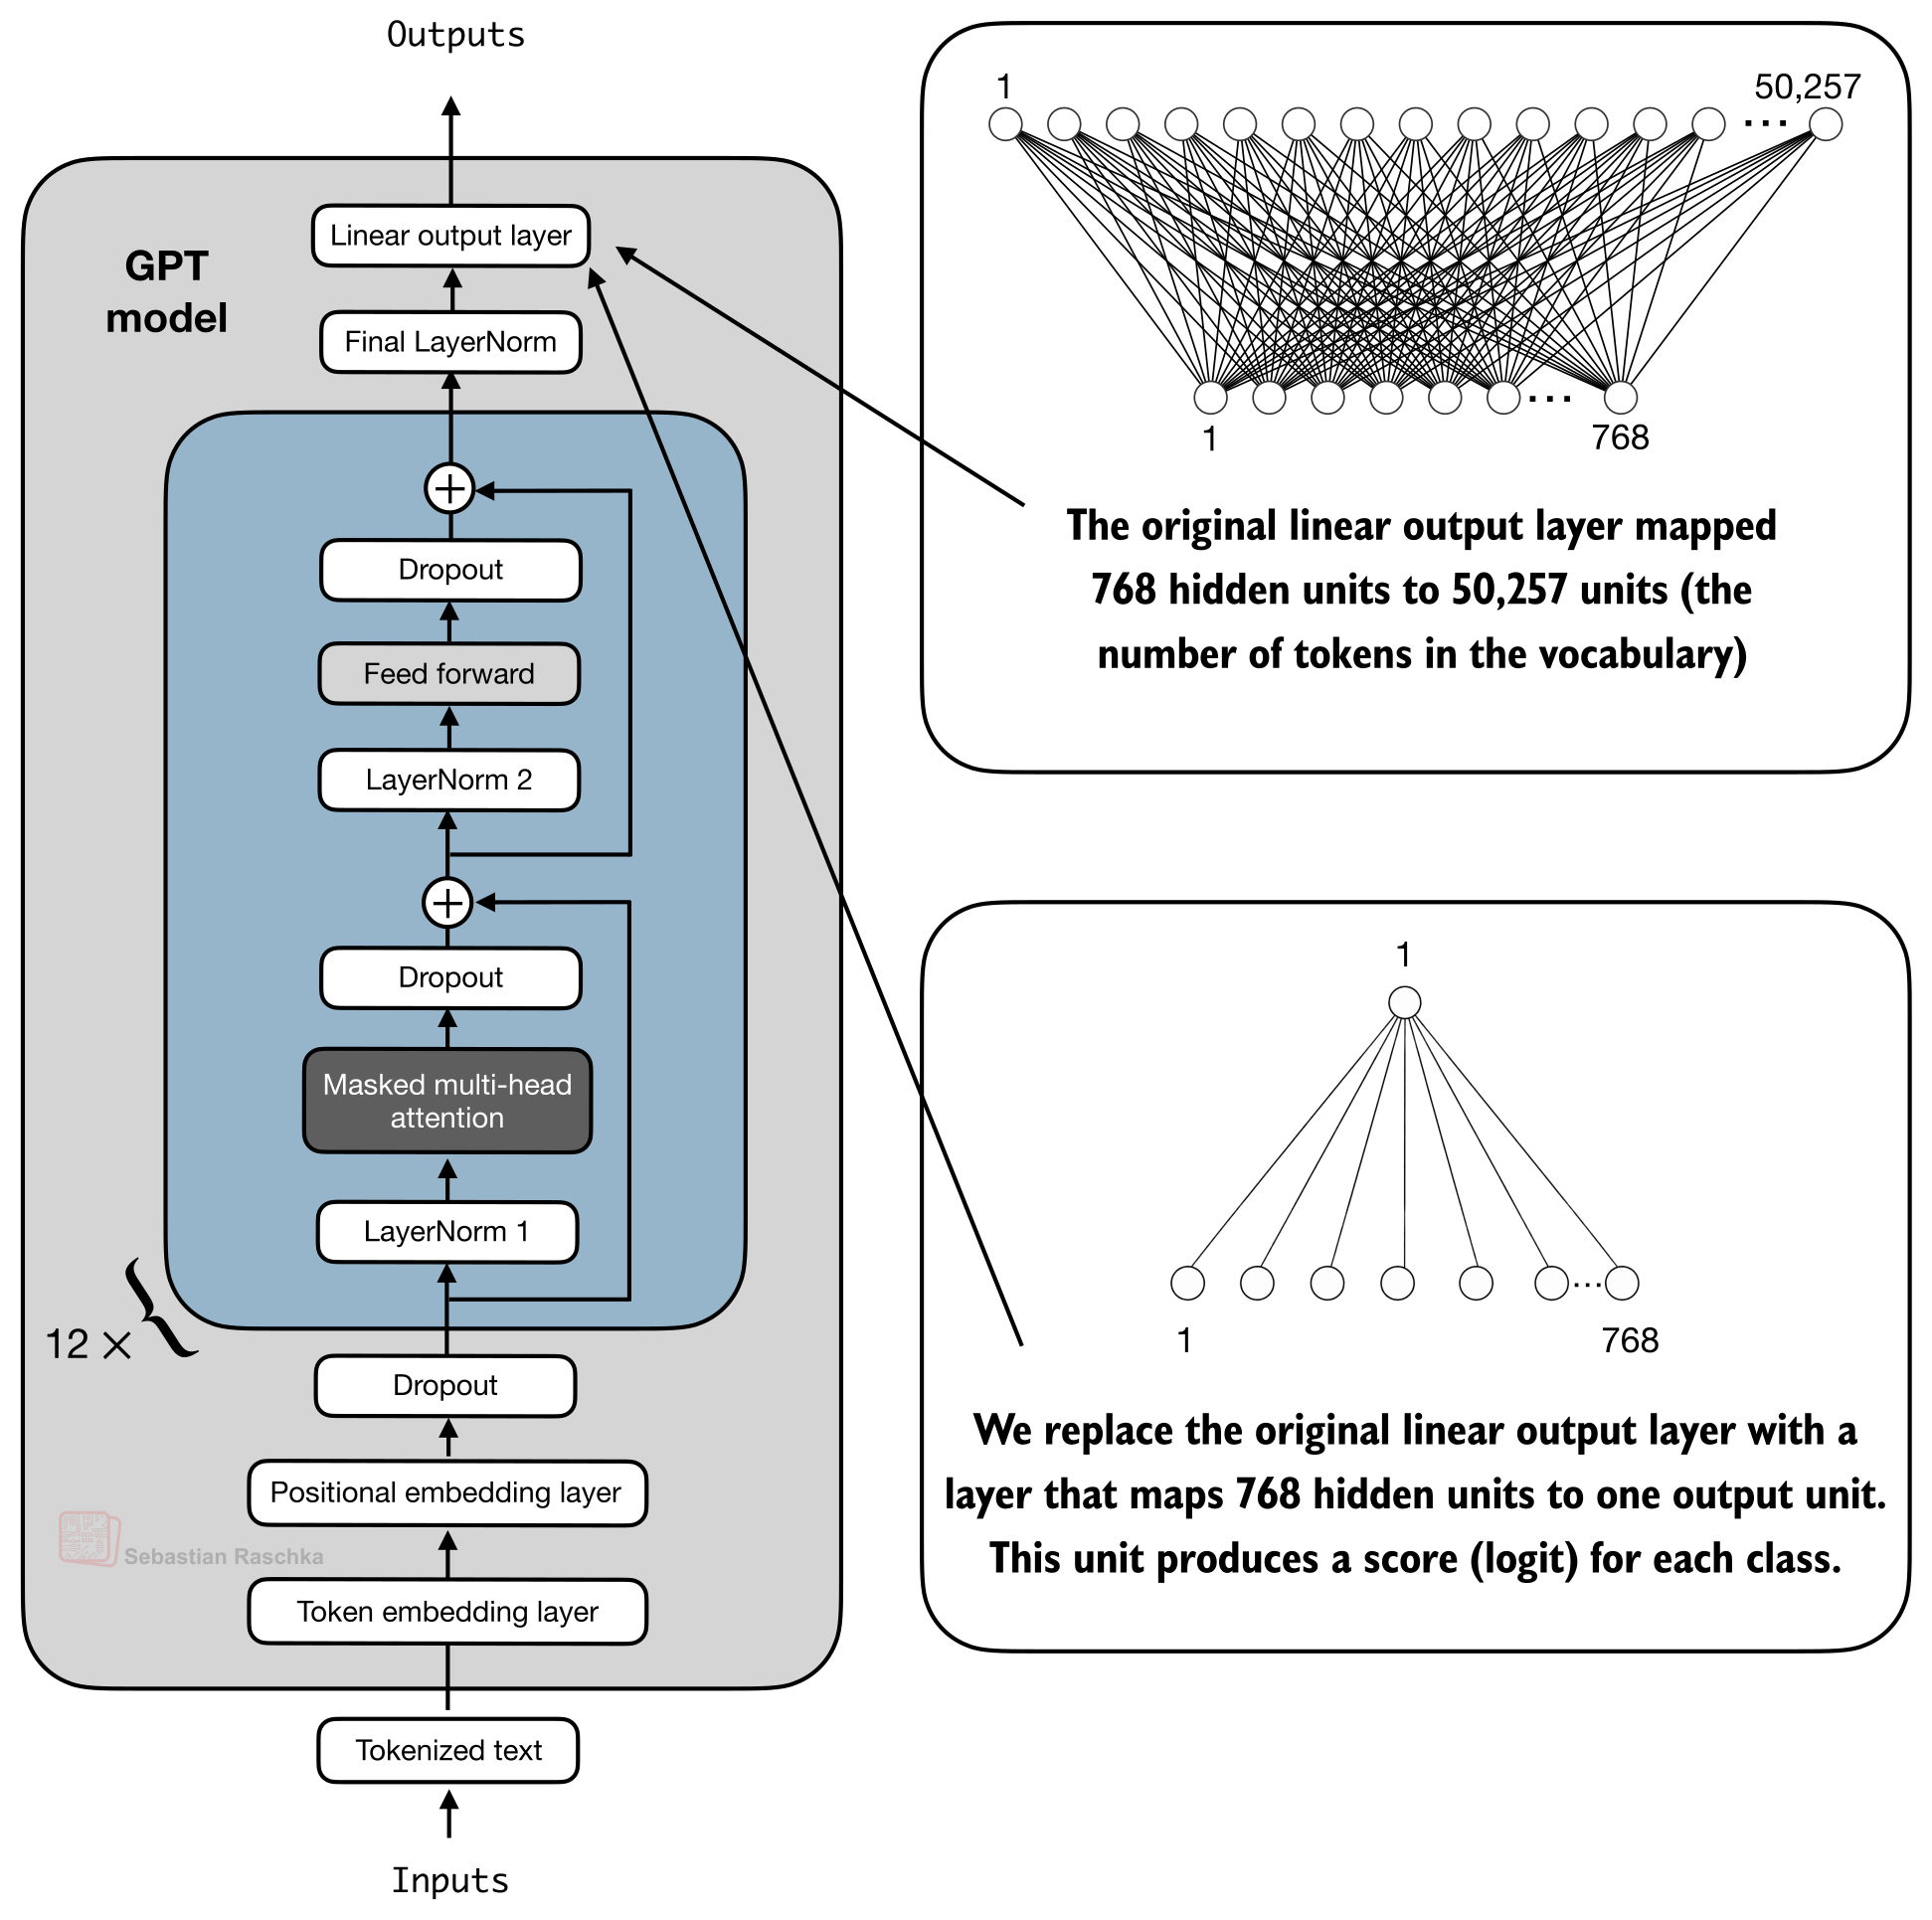
Earlier, we discussed fine-tuning these models for a specific task like movie review classification with a pre-defined number of class labels (here, “positive” and “negative”). With this “1 output node” setup, we can actually extend this to a flexible and arbitrary number of classes.
To extend this to an arbitrary number of classes (let’s consider the 3-class case of categorizing a customer ticket into the three categories “billing”, “technical”, “account”), we can do so as shown in the figure below.
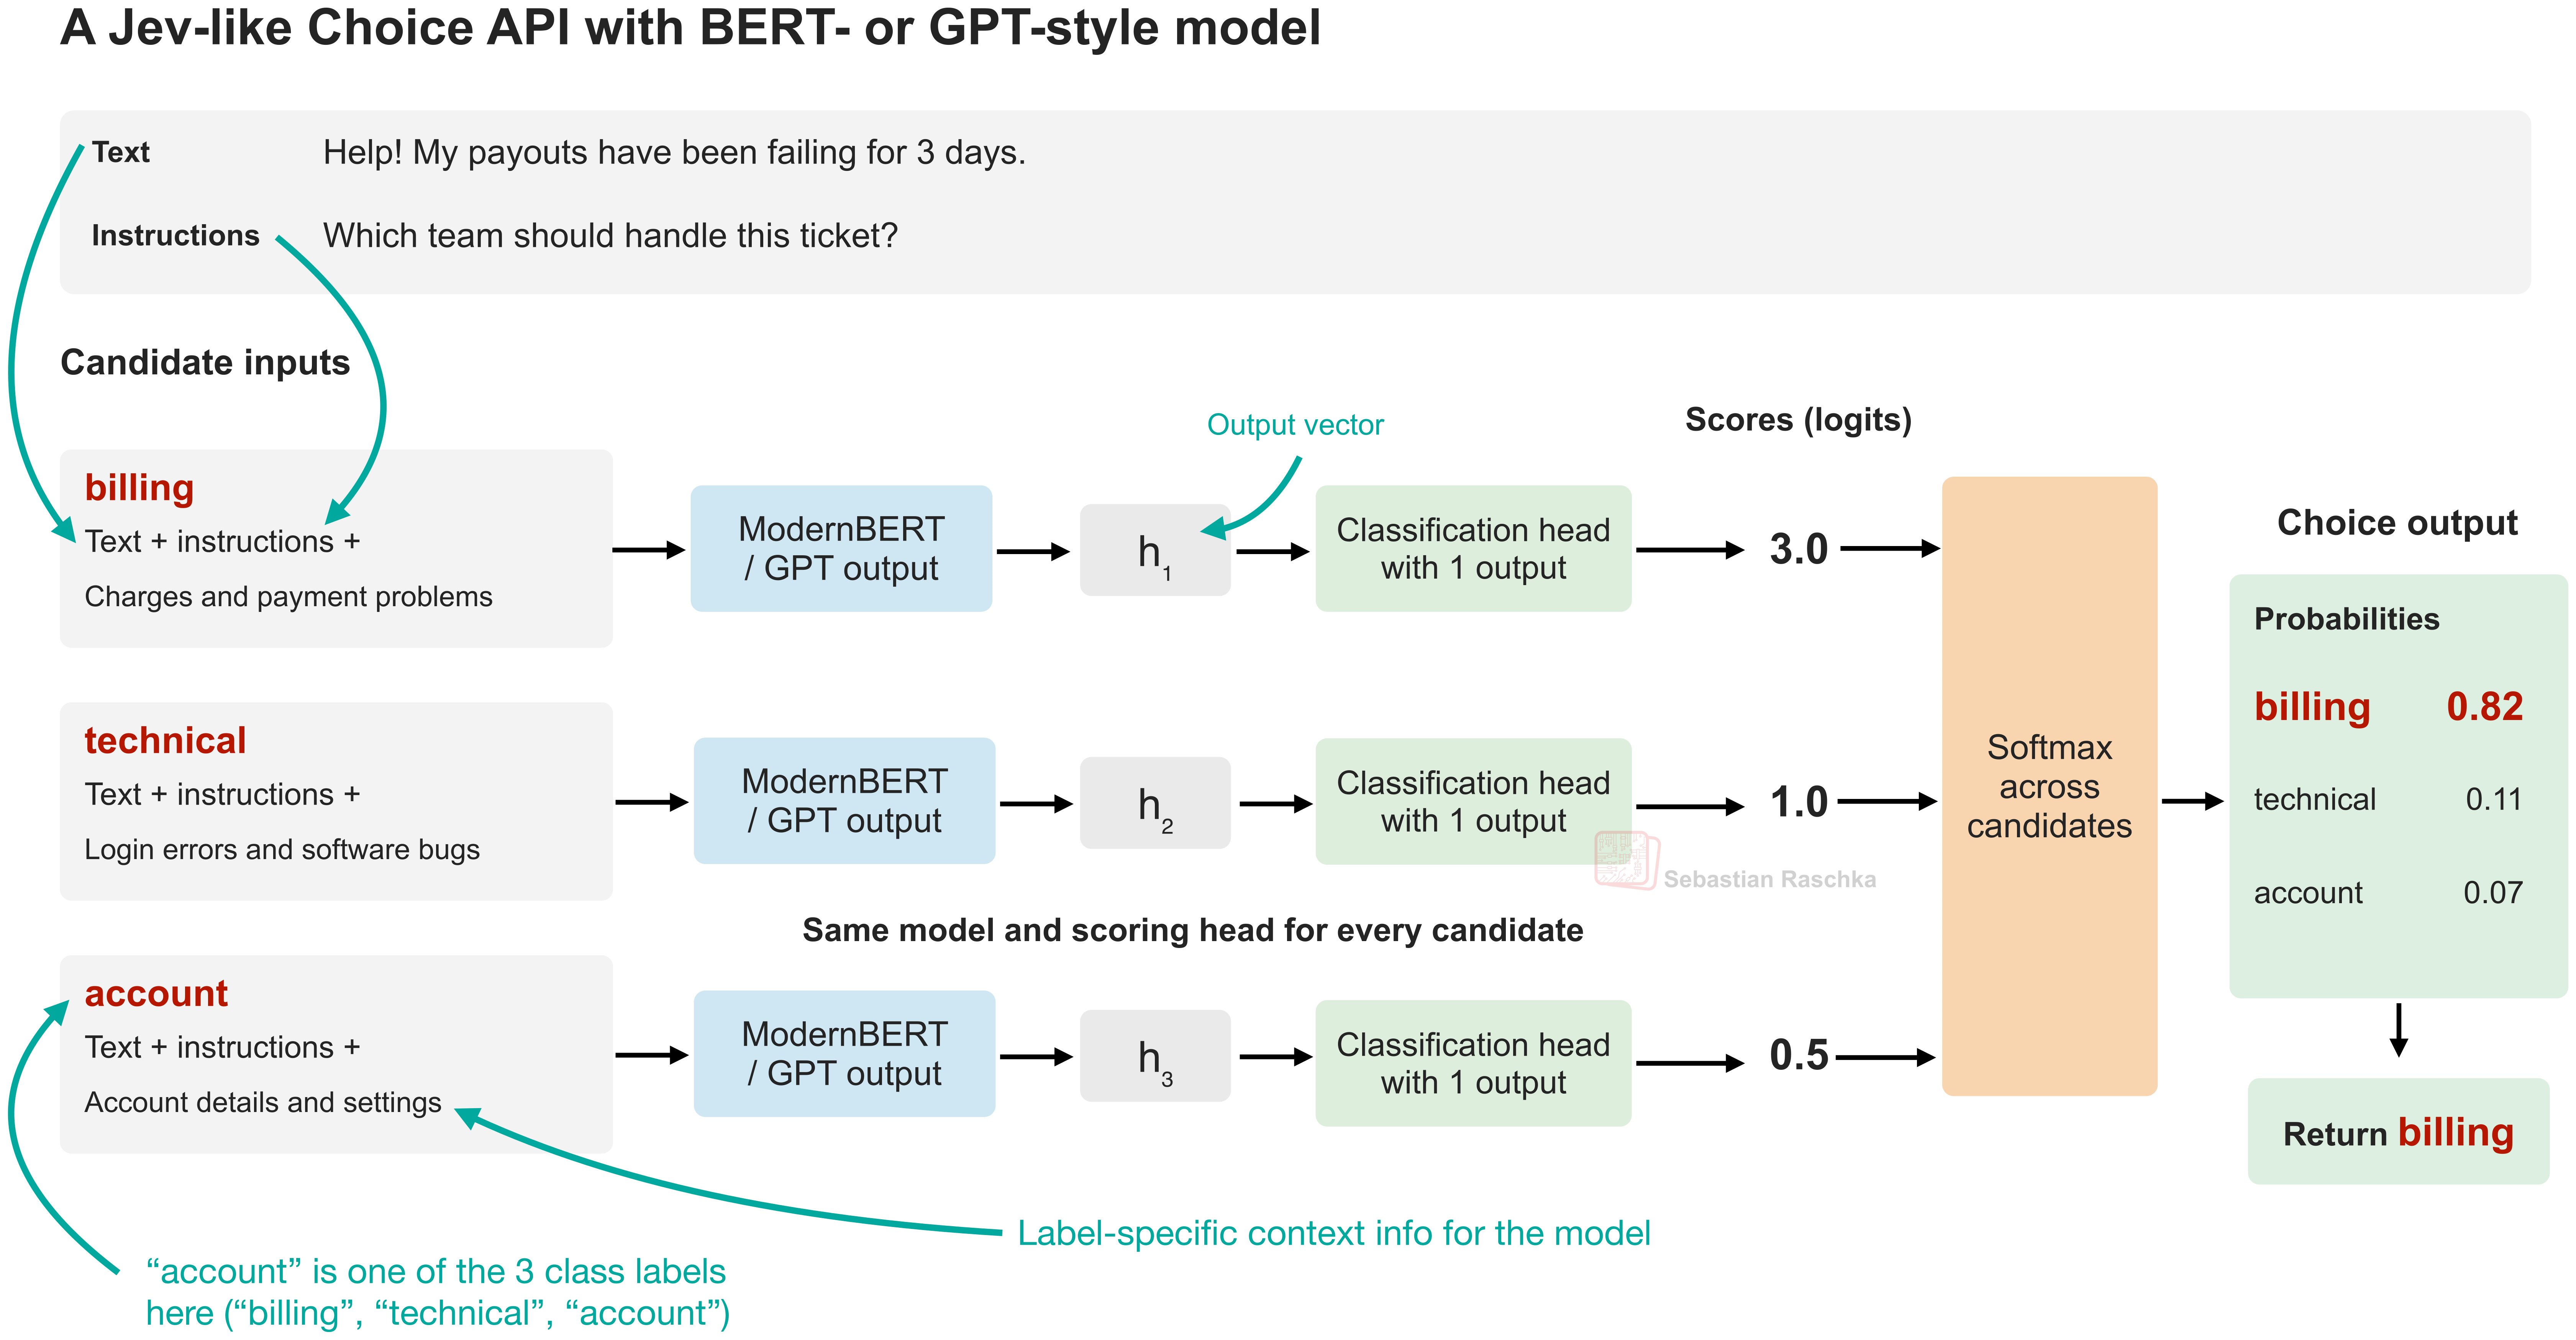
As shown in the figure above, for each candidate option, we feed the model the input text, the task instructions, and the candidate’s description. The classification (scoring) head maps the output representation to a single scalar score. We then apply softmax across the candidate scores to obtain a probability distribution and return the highest-probability option.
The main point here is that the proposed head has one output per class. Each class description produces its own representation, which the same head scores via the output layer (which is essentially a logistic regression model):
where
si is the scalar score for class label i;
w is a learnable weight;
b is a learnable bias unit;
hi is the output of the transformer before the classification head.
For N candidates, this produces N scores. Softmax then returns N probabilities. The learned parameters and stay the same when N changes.
Note that for hi:
BERT-style encoder models use the final hidden state of the
[CLS]token (optionally passed through a pooling layer);GPT-style autoregressive models typically use the final non-padding token’s hidden state, which we need because of the autoregressive nature as discussed earlier (the last non-padding token can attend to the preceding text, instructions, and candidate description).
Then, we fine-tune the model and the scoring head jointly using cross-entropy loss against the correct option. Since all candidates share the same scoring head, we can change the number and descriptions of the options without changing the architecture. But again, how well this works on unfamiliar tasks depends on the training data.
By the way, why BERT- or GPT-style transformer-based models over simpler RNN and CNN architectures mentioned earlier? From a technical perspective, the approach outlined above works with either. But transformer-based models scale really well, meaning they can be pre-trained on larger datasets and benefit more than other models. Also, they can make good use of the information provided in the context (thanks to attention). So, if we want our model to generalize well to different target tasks without explicit fine-tuning on each one, pre-training a transformer-based model on a high-quality dataset likely gets us closer than RNN- or CNN-based models.
5. Jev architecture and training algorithm
So, how come Jev does so well on so many different tasks (from movie reviews to something arbitrary like playing Tetris)? Unfortunately, the architecture, algorithm, and training data details are not public. Also, keep in mind there’s a whole team and multi-million-dollar company behind it that specialized in and worked really hard on this model; we can’t expect to match that level of performance by training a ModernBERT-like model for a week on some open datasets.
That being said, if I had to make an educated guess, architecture-wise, I’d guess that they are using something small similar to ModernBERT, hence, the low latency.
For the training data, as mentioned before, the TypeSafe AI CEO said the following:
100% of our data is synthetic (but not the type of crap that is just spit out from an LLM obviously)
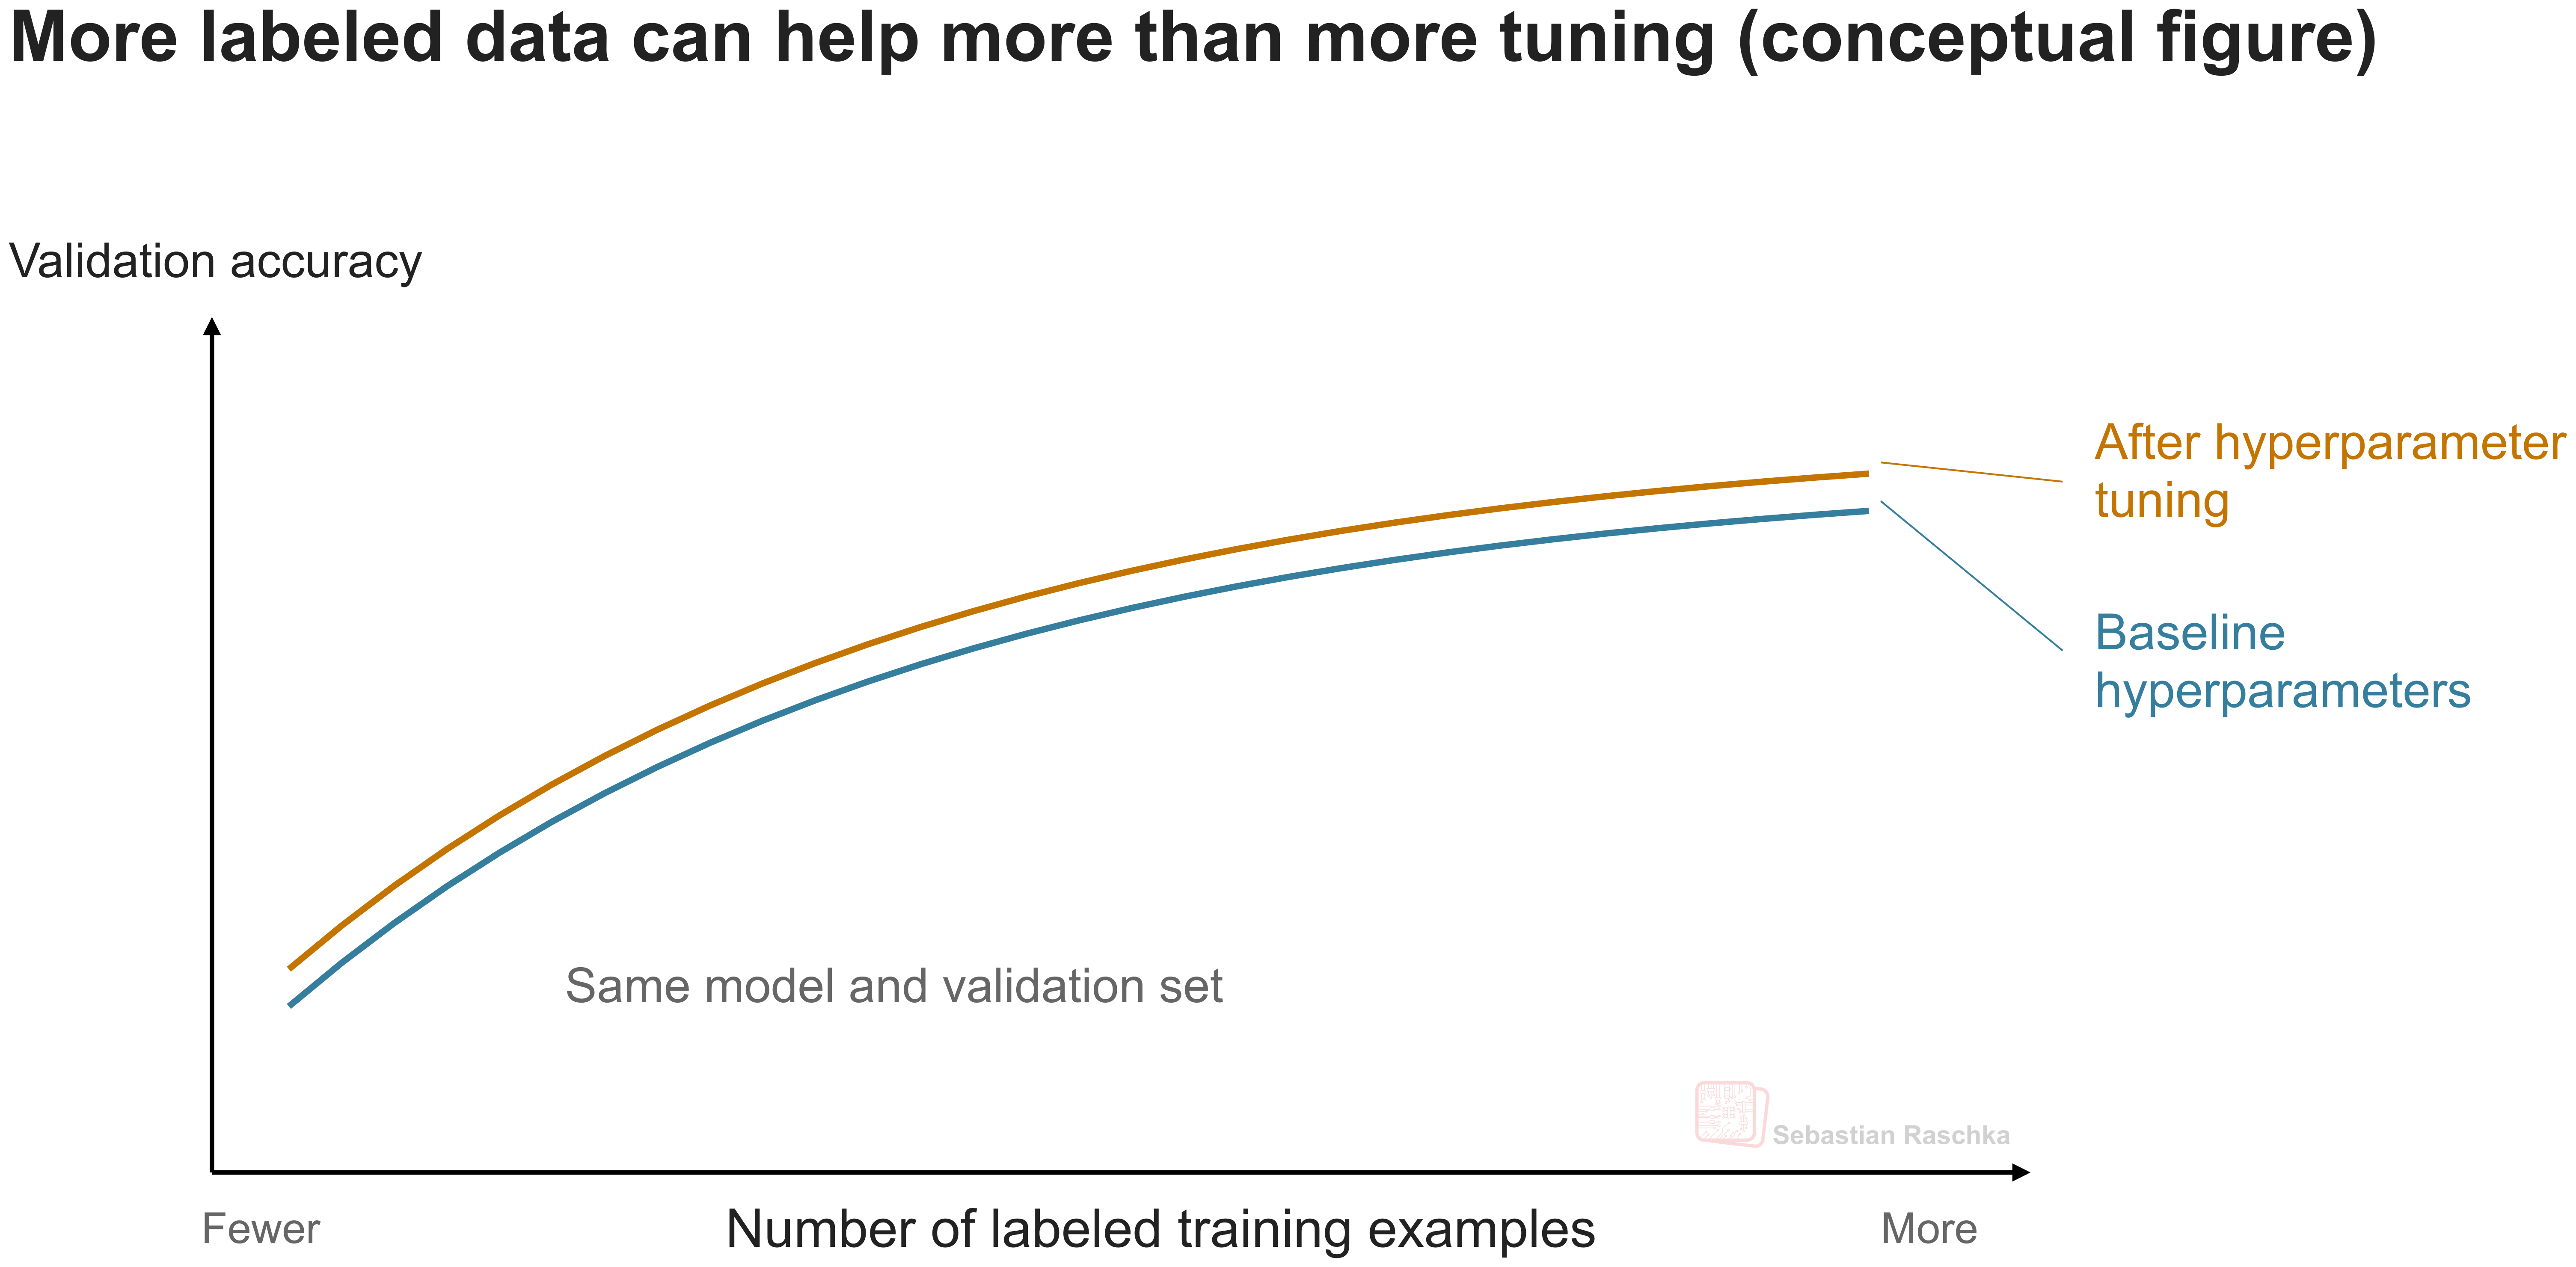
So, yeah, I think most of the effort went into curating this dataset. It’s something I’ve also been preaching to students and collaborators for many years. As a short anecdote, about 8 years ago, I was collaborating with another professor in the social sciences department and helped to design the experimental setup for a text classification problem. Her student spent many days hyperparameter tuning both a bag-of-words baseline and a BERT model to eke out ~2-5% accuracy. Then I suggested we each sit down for a few days to hand-label more data (I think our original dataset was around 300 samples, and we doubled the size), which resulted in a >10-20% accuracy boost. Yes, it’s important to plot learning curves for that purpose :).
Finally, the training algorithm. Again, the details are not known, but TypeSafe AI’s blog post states that they were using a new algorithm called Reinforcement Learning for Calibrated Decisions (RLCD):
“We built a new stack entirely focused on automation: with a new model architecture, parallel sampler for maximum efficiency, and training method we call Reinforcement Learning for Calibrated Decisions (RLCD).”
This method is not public. A published method with a similar calibration objective is RLCR (Reinforcement Learning with Calibration Rewards), from the 2025 paper Beyond Binary Rewards: Training LMs to Reason About Their Uncertainty. Before providing more details, the next section gives a brief overview of calibration in general.
5.1 On calibration
Calibration is not a new topic and a step I recommend for any production model where you want to use and evaluate the class-membership probabilities. In short, calibration adjusts the model’s probability estimates so they better match observed class frequencies.
For example, consider once more our IMDb movie classification problem. A model might assign a review 74% positive and 26% negative. These are probability estimates, but the model may be overconfident or underconfident. We cannot assume that the numerical values are reliable without evaluating calibration. I.e., predictions of 74% positive and 54% positive both yield the class label “positive” at a 50% threshold, although the model expresses more confidence in the 74% case.
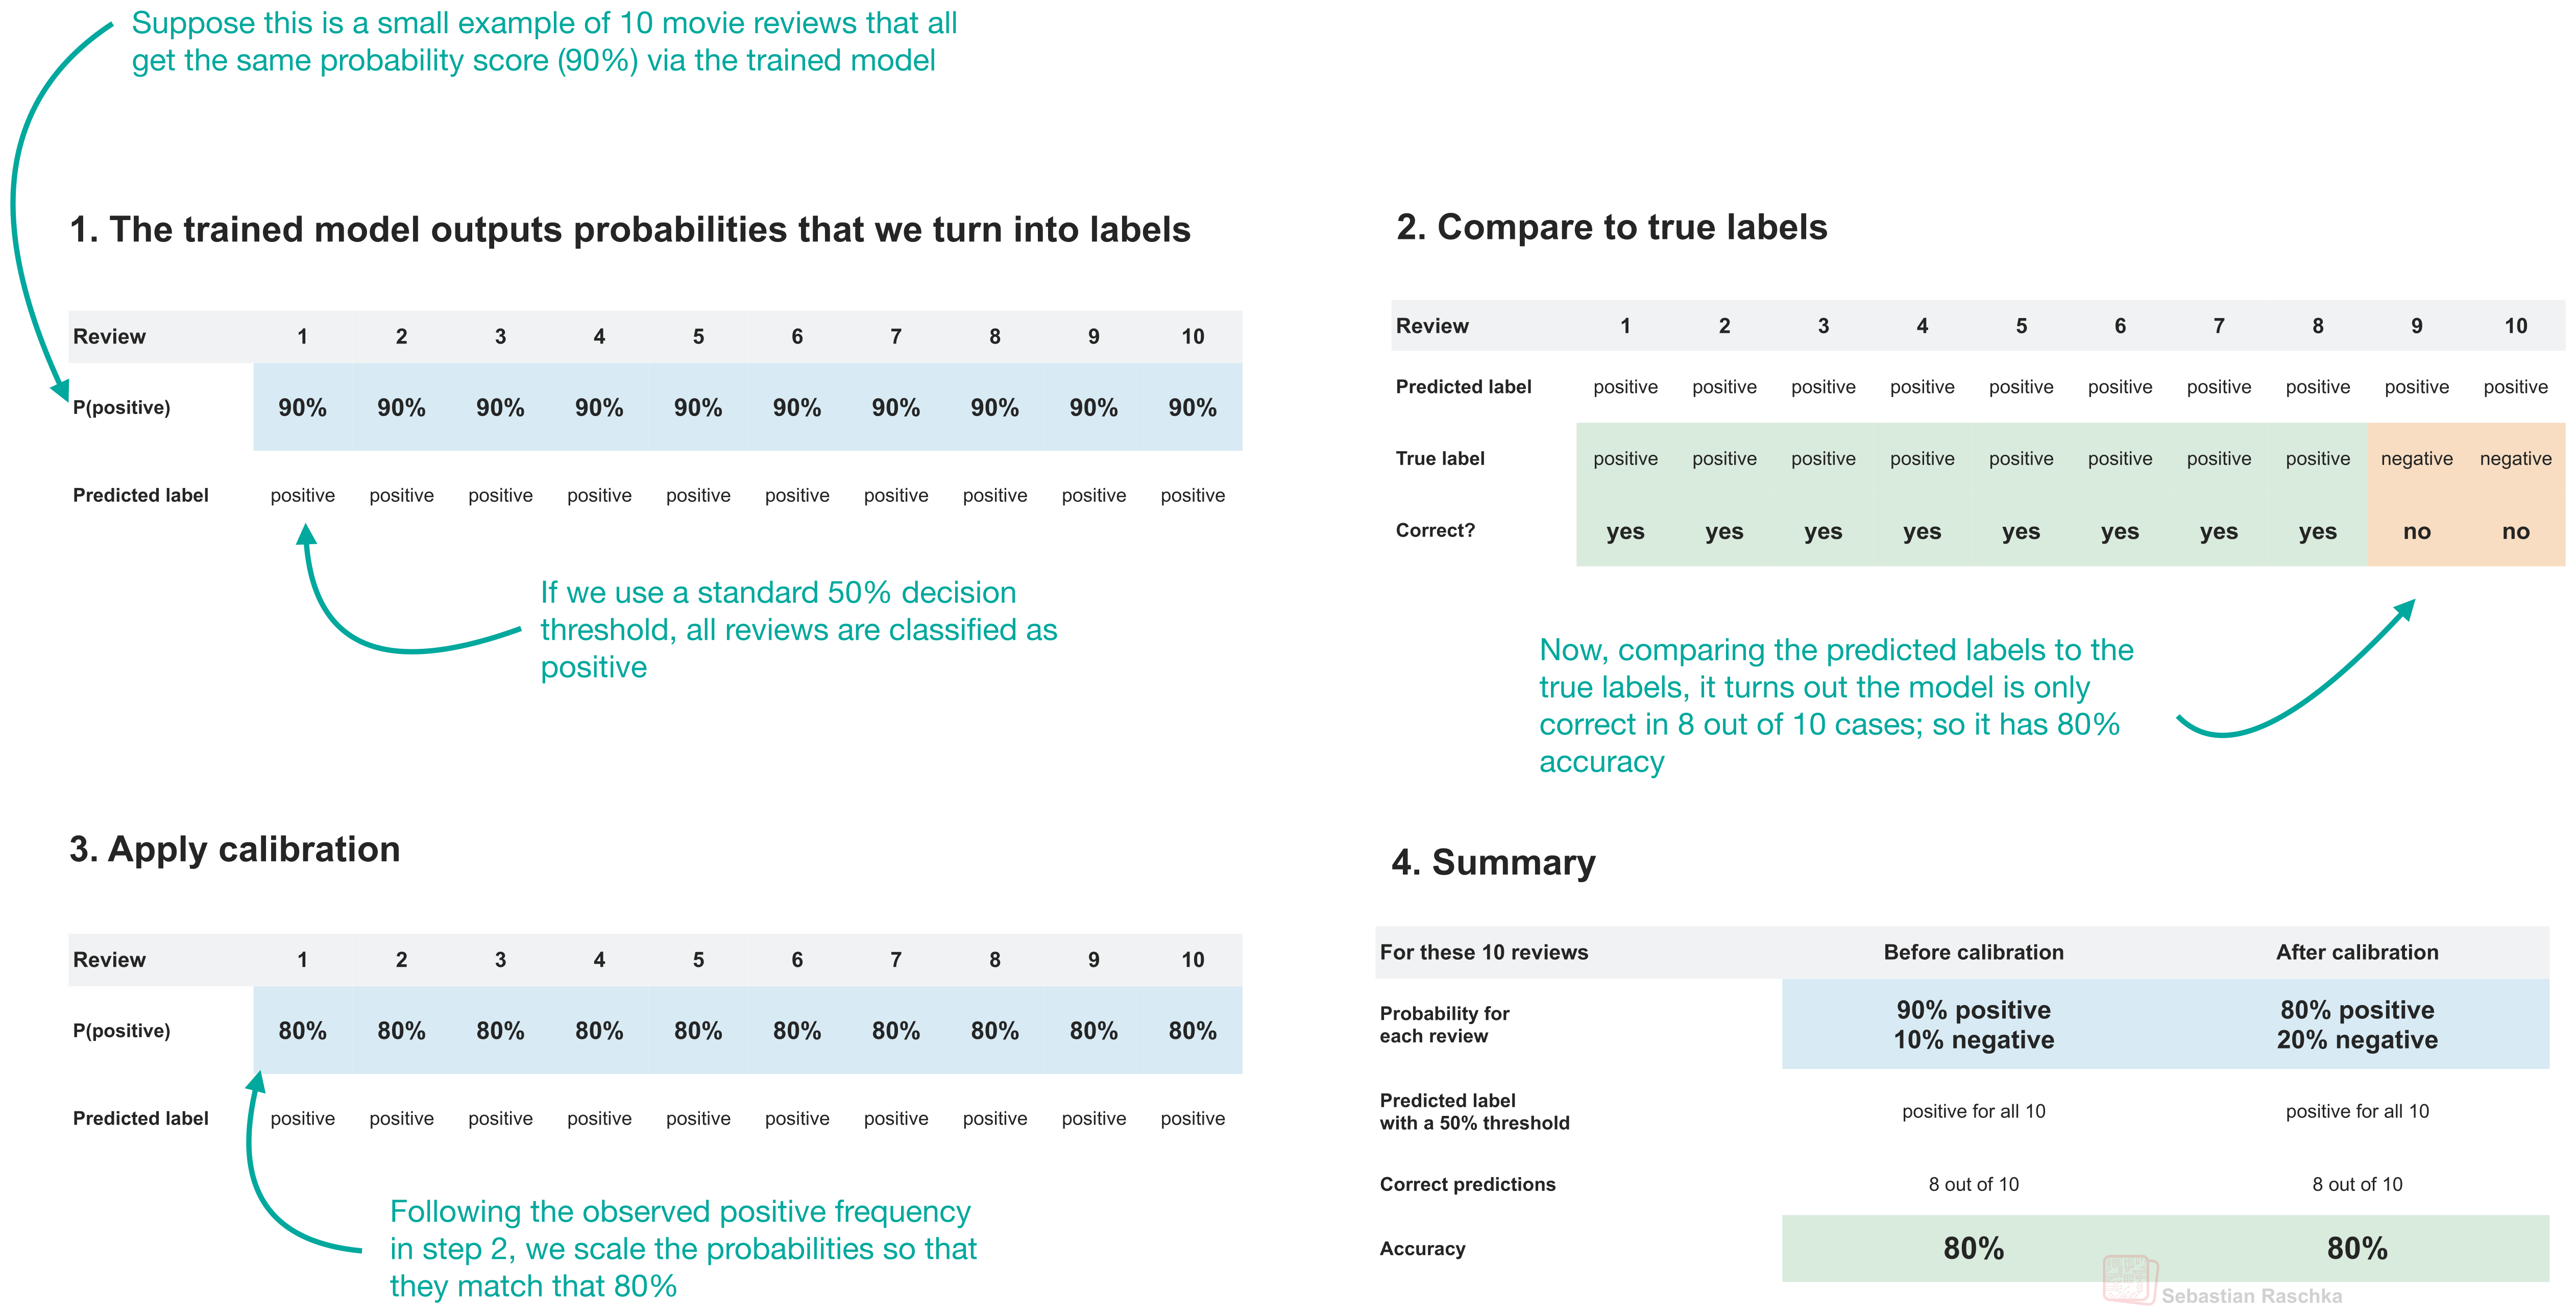
Calibration techniques use a separate labeled dataset, e.g., a held-out validation set, to adjust these probability estimates. After successful calibration, among many reviews assigned a positive probability of approximately 74%, roughly 74% should actually be positive. For more information, I recommend the good old scikit-learn documentation.
There are many approaches for this. For example, one that I used in my AI detector project is temperature scaling. Temperature scaling divides the model’s logits by a temperature (T) value before applying softmax. We learn T (a positive number) by minimizing the cross-entropy loss on the calibration dataset while keeping the model weights fixed. A temperature above 1 reduces confidence in the highest-probability class, while a temperature between 0 and 1 increases it. We then use this same temperature for new predictions. Because this scaling preserves the ordering of the logits, the predicted class remains unchanged when we select the highest-probability class.
5.2 Reinforcement learning with calibration rewards (RLCR)
Jev’s RLCD training method remains proprietary, but a related idea we can discuss is Reinforcement Learning with Calibration Rewards (RLCR), which was introduced in the 2025 Beyond Binary Rewards: Training LMs to Reason About Their Uncertainty paper. (Note that there is no officially established connection between the two methods, but I am assuming that they could be related.)
Reinforcement learning with verifiable rewards (RLVR) typically rewards a correct answer with 1 and an incorrect answer with 0. (For a comprehensive explanation and implementation, I recommend checking out my Build A Reasoning Model (From Scratch) book :)).
In short, RLCR adds an additional penalty for inaccurate confidence estimates.
So, in the conventional RLVR method, the reward R is either 0 or 1 based on the answer correctness (we are ignoring an optional formatting reward and length penalty here, for simplicity).
In RLCR, the model generates reasoning and an answer, which is followed by an uncertainty analysis and a numerical confidence (q). This modified reward is
where c is 1 for a correct answer and 0 otherwise. For example, an incorrect answer with 90% (0.9) confidence receives a reward of -0.81, since
At 20% confidence, the reward is -0.04. And a correct answer at 90% confidence earns 0.99. (Readers familiar with evaluating calibrated models may notice that the squared-error term is the Brier penalty for the stated probability that the answer is correct.)
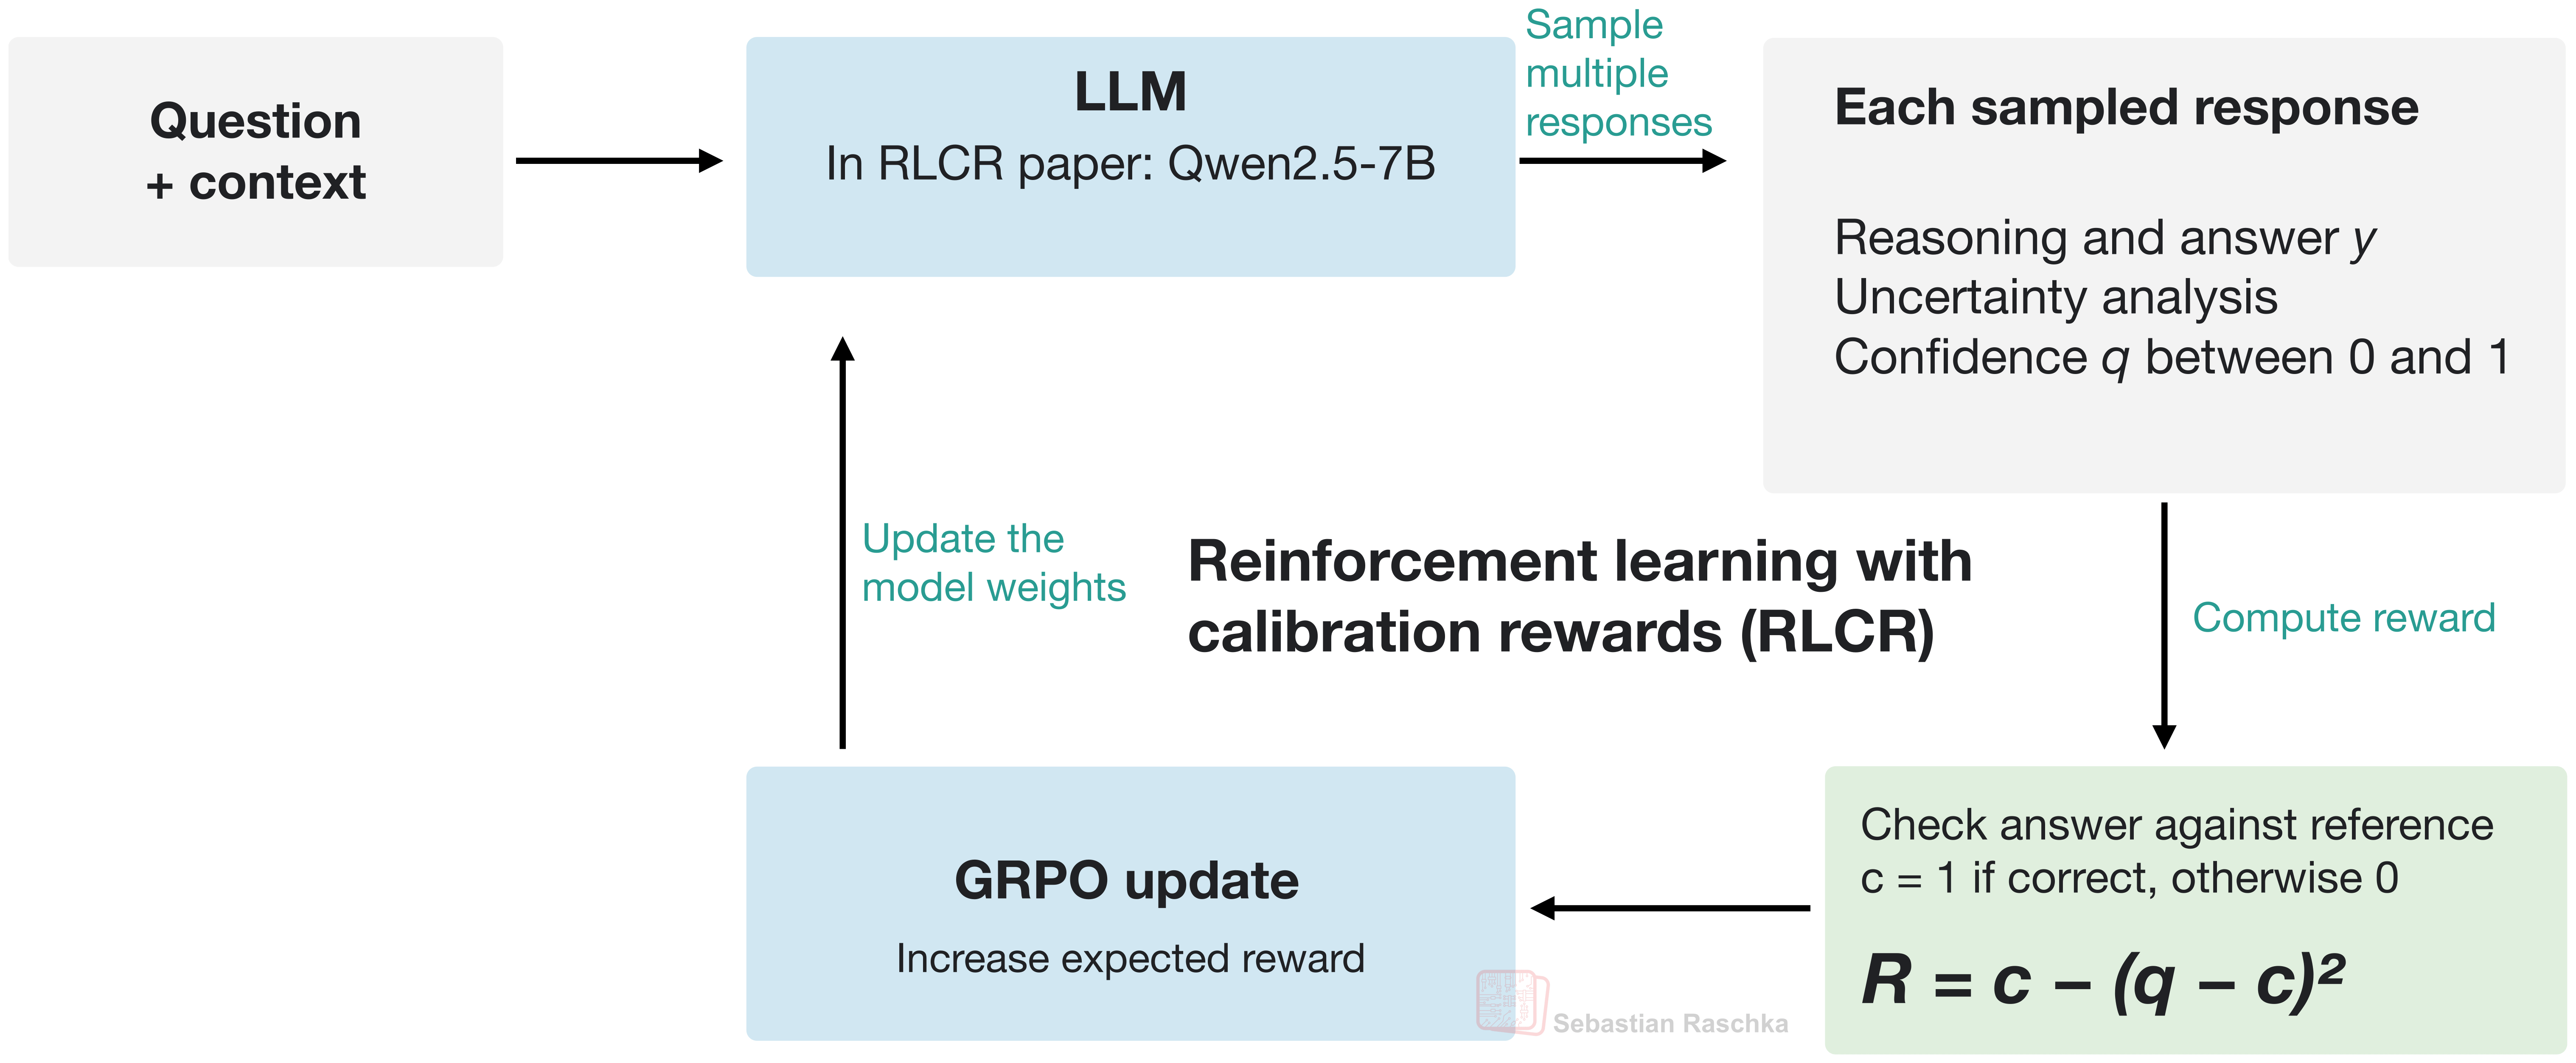
Note that the same (here, Qwen2.5-7B) model generates the uncertainty analysis and q as part of its response.
The uncertainty analysis is a written assessment of where its answer could be wrong. After answering, the model examines missing evidence, ambiguous wording, questionable assumptions, or possible reasoning errors. The paper’s prompt asks it to identify specific uncertainties rather than propose corrections.
Also, the system prompt explicitly asks for q, a number between 0 and 1 inside tags. It represents the model’s estimated probability that its answer is correct. The system generates all these parts sequentially in the same response.
For illustration purposes, the model answer could be as follows:
<think>...reasoning about the question...</think>
<answer>positive</answer>
<analysis>
The passage mentions a positive movie review, but the connection to the second paragraph is unclear.
</analysis>
<confidence>0.6</confidence>
Below is an annotated figure from the paper that illustrates how it improves the expected calibration error over regular RLVR with temperature scaling.
On HotpotQA, RLCR reduces expected calibration error (ECE) from 0.37 to 0.03 compared with RLVR, with similar accuracy (62.1% versus 63.0%). Across six other datasets, average ECE falls from 0.46 to 0.21, while accuracy rises from 53.9% to 56.2%. These are the results in the paper’s Table 1(a).
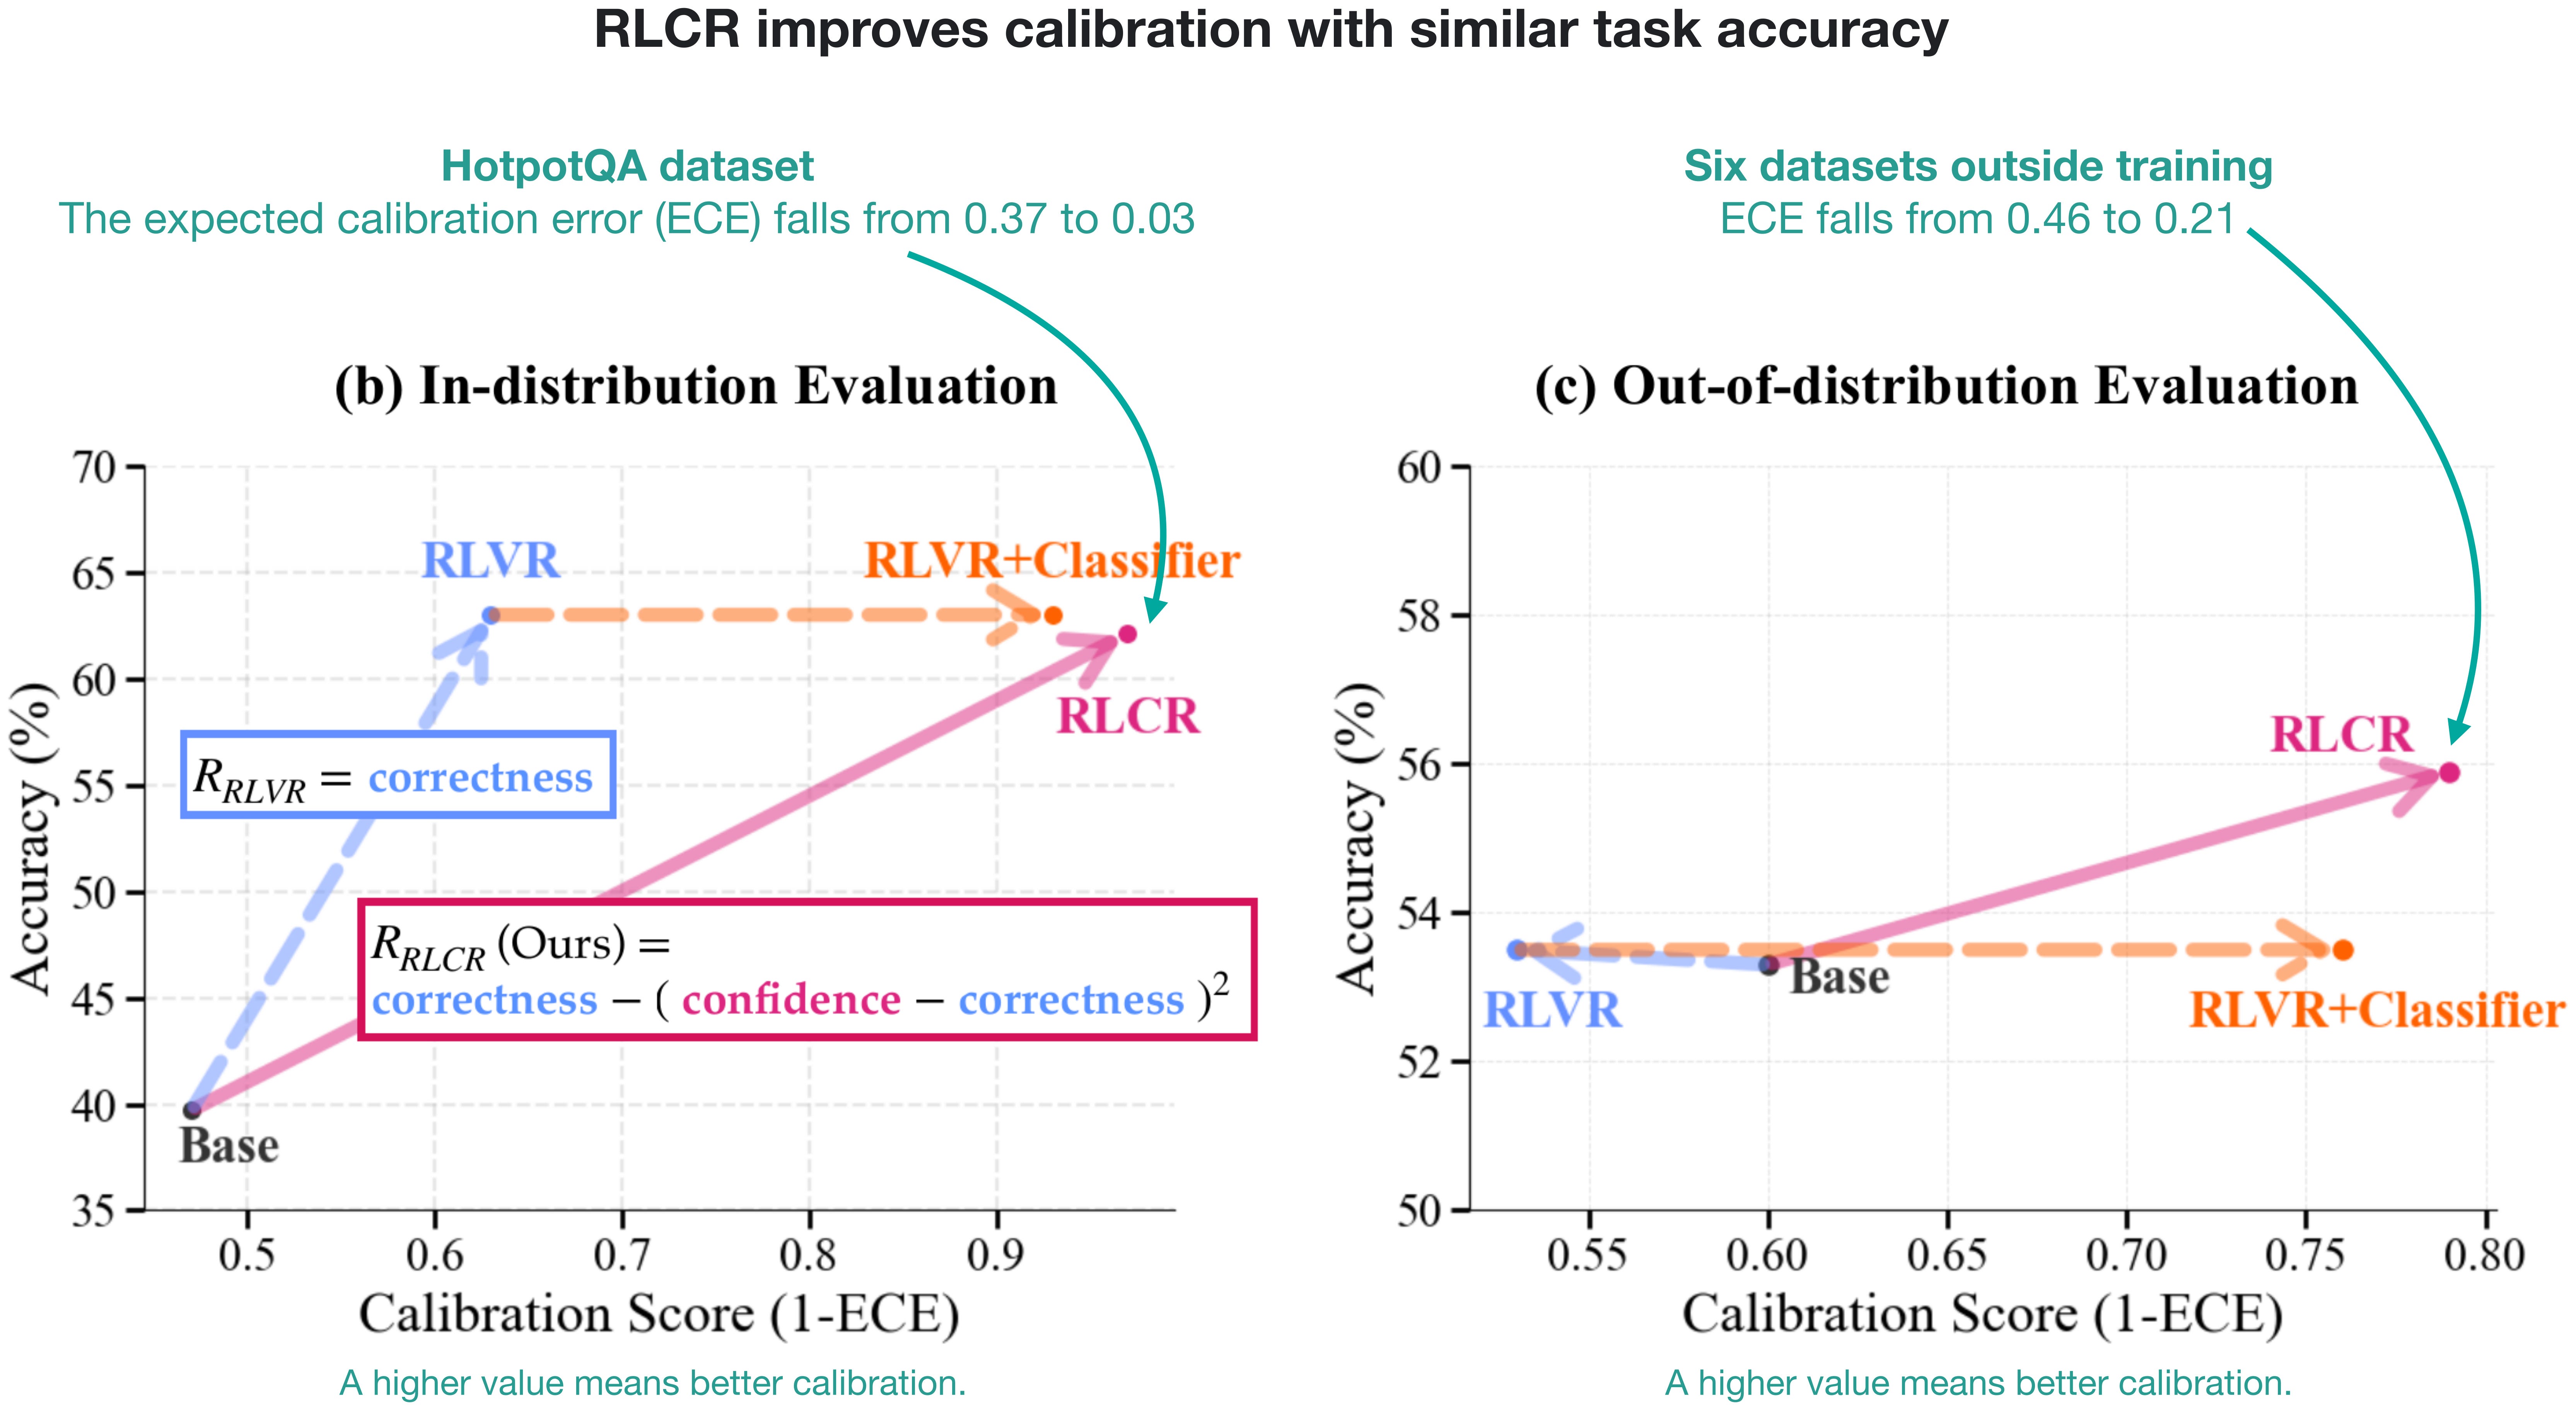
Conceptually, the “Classifier” in “RLVR + Classifier” is a supervised binary classifier that predicts whether the generated answer is correct.
For Jev, I could apply calibration rewards directly to typed decisions, without generating reasoning text. For example, we could equip a GPT-style model with the classification head illustrated in Section 2.2 and adapt the RL training objective to reward accurate decisions and calibrated probabilities. We would train the backbone and classification head together. This would be an adaptation inspired by RLCR, and it remains unclear whether Jev’s RLCD works this way.
Alternatively, since Direct Policy Optimization (DPO) is a cross-entropy (CE) alternative to Reinforcement Learning with Human Feedback (RLHF), we could also directly minimize CE + Brier loss on the classifier’s probabilities. I did this with the ModernBERT model, and there was a modest improvement over regular temperature scaling.
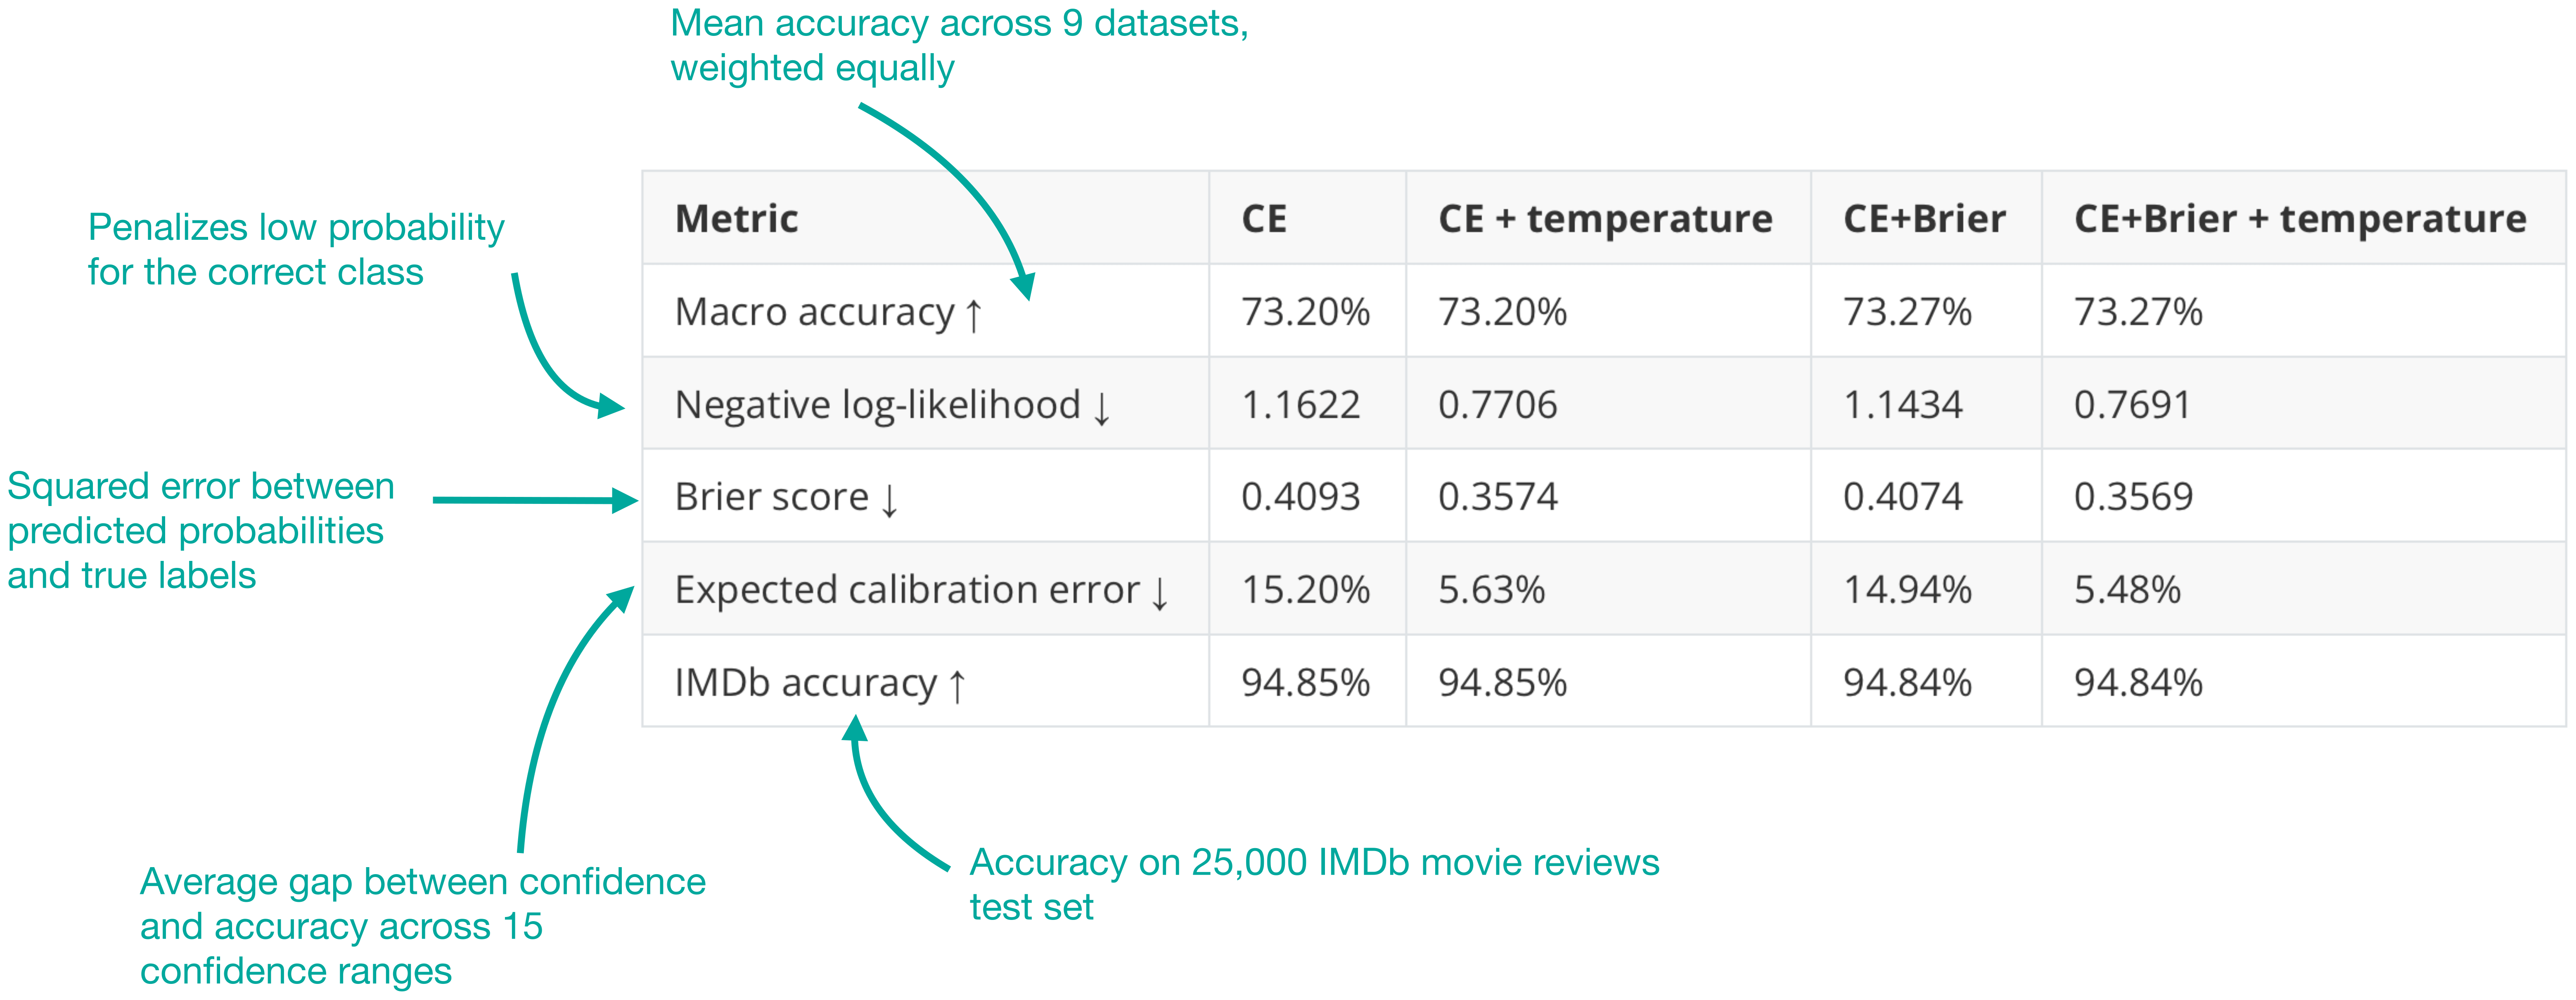
(For simplicity, the figure above only shows the average results over nine datasets. Overall, as can be seen, calibration was beneficial on average. However, it slightly worsened the ECE on one out of the nine datasets.)
5.3 Side note: Is calibration necessary?
Cross-entropy already encourages accurate probability estimates. Under ideal conditions, that is enough to obtain calibrated predictions without an additional penalty.
I.e., using a simple coin flip example analogous to the movie review classification, the two classes are “heads” and “tails.” If it’s a biased coin that lands heads 80% of the time (in expectation), the true probabilities are 80% heads and 20% tails. On a representative training set, when we optimize cross-entropy, the model will already learn these as a side-effect of minimizing cross-entropy (negative-log-likelihood).
So, in short, if the model learns the true class probabilities, its predictions are calibrated and an additional penalty is unnecessary. (And Brier loss has the same theoretical optimum as cross-entropy, as described in Strictly Proper Scoring Rules, Prediction, and Estimation by Gneiting and Raftery, 2007.)
In practice, however, we never train to the real optimum (in expectation) but train on a finite dataset.
So, once a neural network correctly classifies most training examples, it can further reduce cross-entropy on the training set by becoming more confident. These confidence estimates may then generalize poorly to the test set and new data.
For example, in On Calibration of Modern Neural Networks, Guo et al. (2017) observed “neural networks can overfit to NLL without overfitting to the 0/1 loss.”
That means test accuracy can still improve while test cross-entropy worsens. So overfitting can show up in the probability estimates even when classification accuracy continues to improve.
Adding Brier loss changes how prediction errors are weighted during training. But whether this improves calibration needs to be checked on held-out data, of course. (The modest improvement in my experiment is an empirical observation for this setup, and we should not assume that adding Brier will always help.)
In my experiments (see previous figure), adding the Brier loss to cross-entropy provided only a very small additional calibration benefit.
But the motivation is more direct in RL contexts, such as described in RLCR, where we measure answer correctness and don’t already minimize cross-entropy. So, in RL contexts, the Brier term adds an incentive to report accurate confidence alongside the reward for answer correctness.
6. Who is Jev for?
Now that we covered Jev in reasonable detail, who is Jev for? Based on my assessment, it’s a pretty big target audience that intersects between people who a) want to save time by not having to fine-tune a custom classifier for every decision task and b) want to save money over using “the big guns” like GPT-6 and similar LLMs.
There are also lots of interesting use cases to think of. In the section below is a short list of ideas.
6.1 Jev use cases
The list of use cases is seemingly endless. Sure, there are flashy examples like having it play video games like Tetris (as I showed in my earlier video above to demonstrate the low latency of the API). However, sorting emails is a more practical choice for most. For example, one could use Jev as an additional spam filter, prioritization, and so on.
But beyond things like that, it could also serve as a tool to augment LLM-agent harnesses. Here it could be used as
a pre-screener for regular LLM-agent harnesses to scan our contexts for prompt injection;
select the reasoning effort level for a model;
select a skill.md from your registered skill library;
use it as a judge for evaluation or self-refinement;
find relevant files for context building.
The list is practically endless. Someone even posted a survey on arXiv analyzing 2,170 Jev-related projects that have sprung up recently in just a few days.
6.2 About Jev clones and local Jevs
Since Jev’s launch, 100s, if not 1000s, of quick Jev clones have sprung up. Most of the ones I checked out were just quick examples fine-tuning a ModernBERT or Qwen model with SFT and adding a Jev-like API.
Based on what I can tell, none of them achieves the same level of performance as Jev on such a breadth of tasks. Comparing these projects to Jev is like comparing Alpaca (the early instruction-finetuned LLM based off of the original LLaMA open-weight model) to GPT-6. Sure, it may work similarly in spirit, but your mileage will vary on real-world tasks.
No offense, but they seem like quick projects to jump on the hype train, and I don’t want to plug a specific one here.
One exception here might be the GLiNER project, which has been around for ~3 years ago, and while it’s not fundamentally the same, it can be used for similar things. However, based on a benchmark, Jev is definitely stronger.
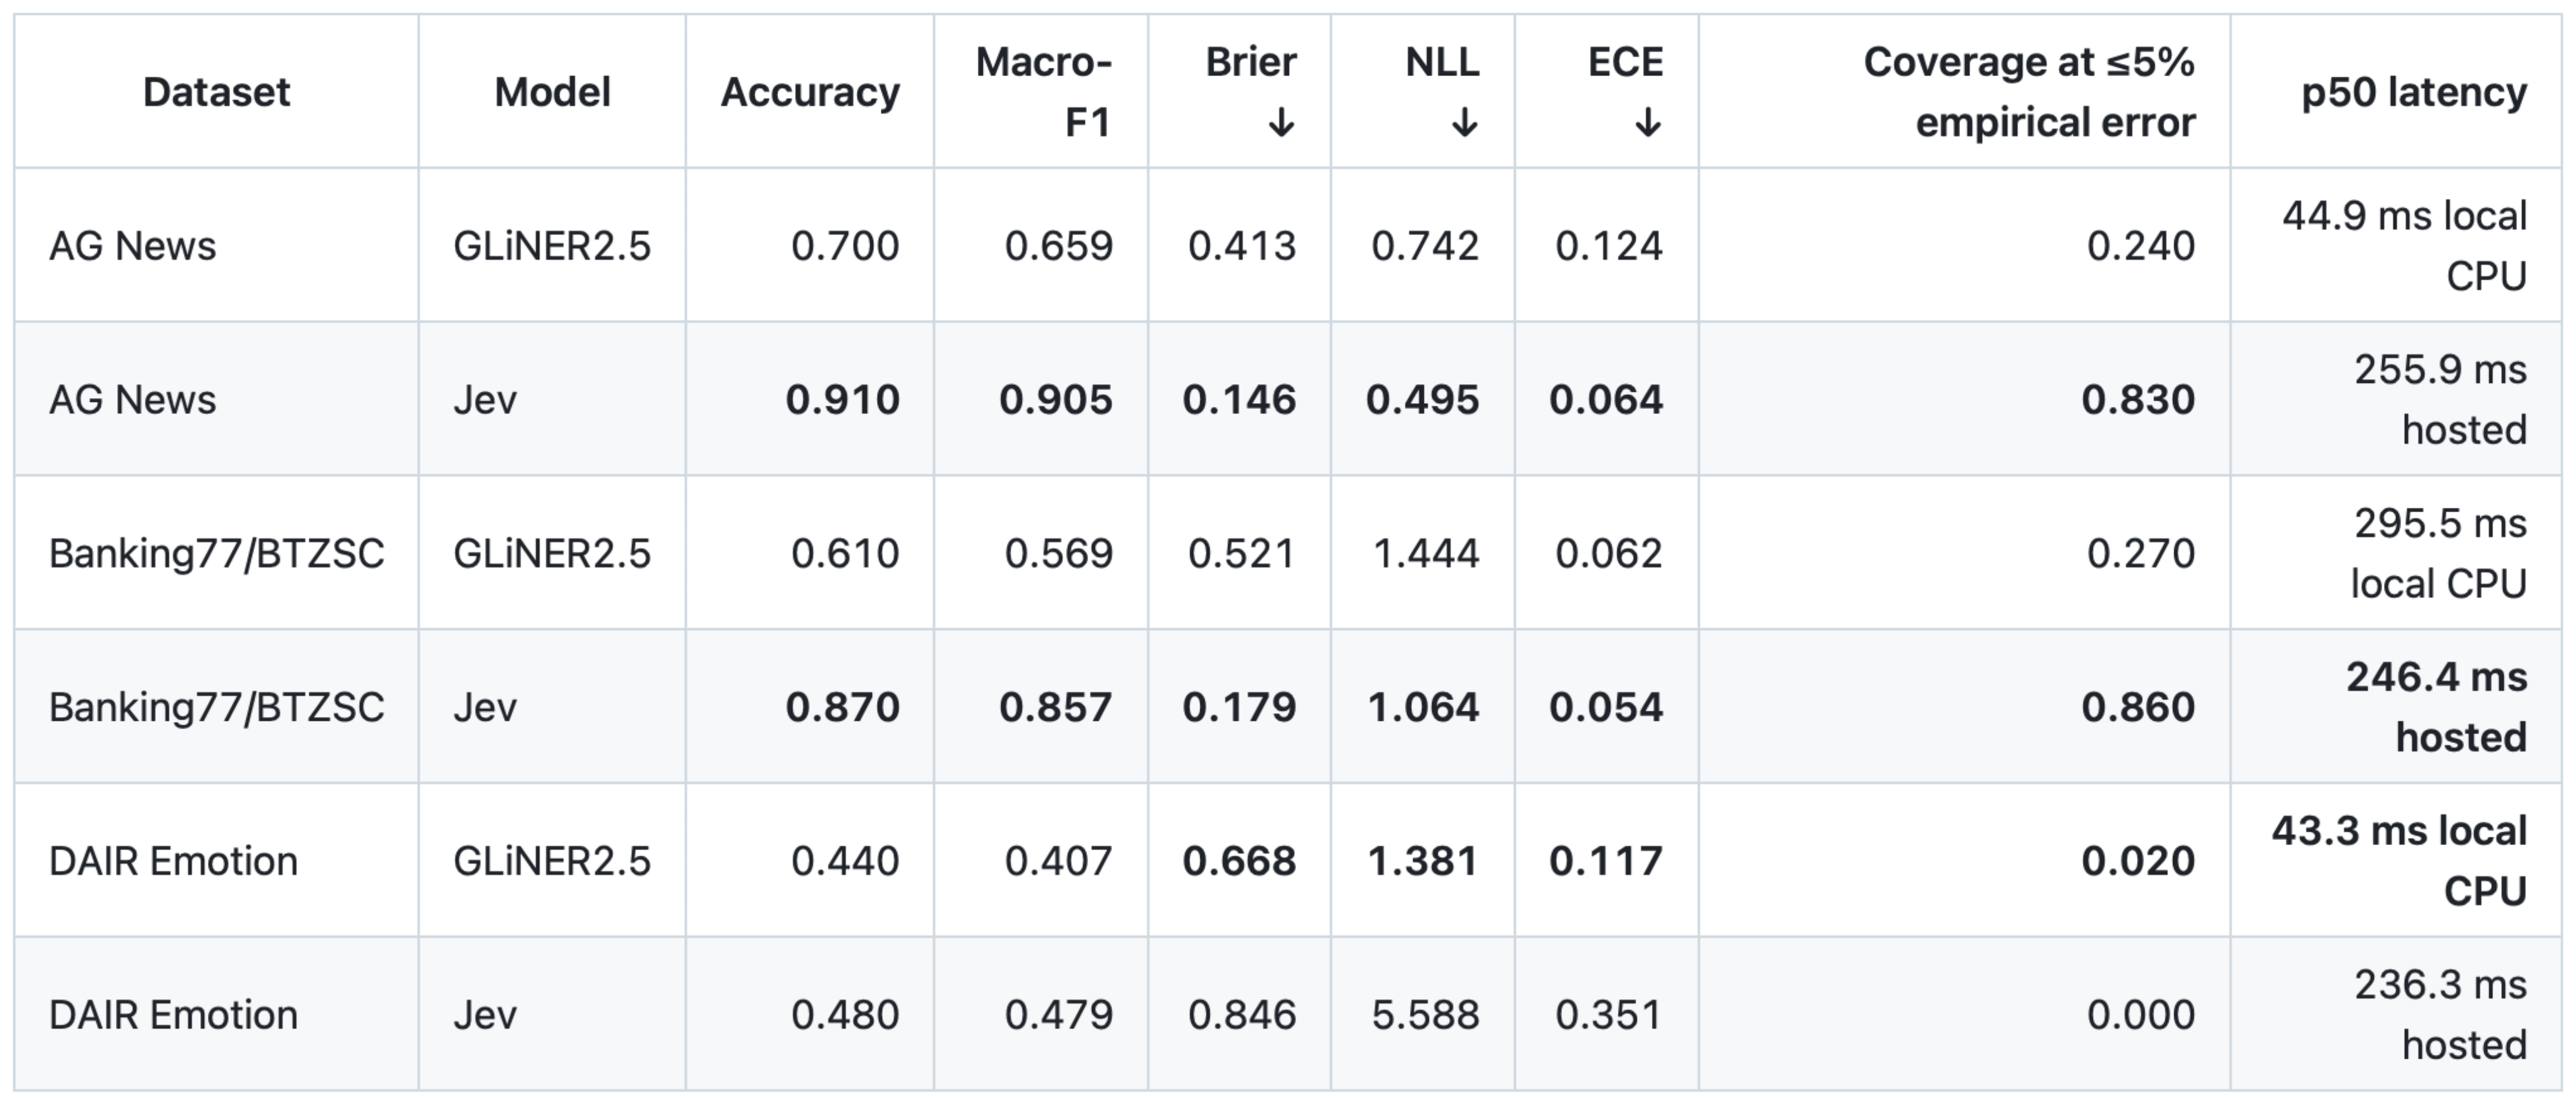
Anyways, there is definitely a genuine need and desire for a good open-weight alternative to Jev. The reason is not necessarily cost (because Jev is so cheap) but privacy. (Also, if Jev is already that fast over the internet, imagine how fast it could be on beefy local hardware.)
So, of course I’d like a DeepSeek (or Kimi, or GLM, or MiMo) moment for Jev. I am sure people are working on this, but it will take some time. TypeSafe AI worked on this for many months with a dedicated team of experts. It’s unrealistic to expect to replicate that development and evaluation work in a week. (However, since this is a smaller and more efficient model than a 1-trillion-parameter model, by nature, it hopefully won’t take that long.)
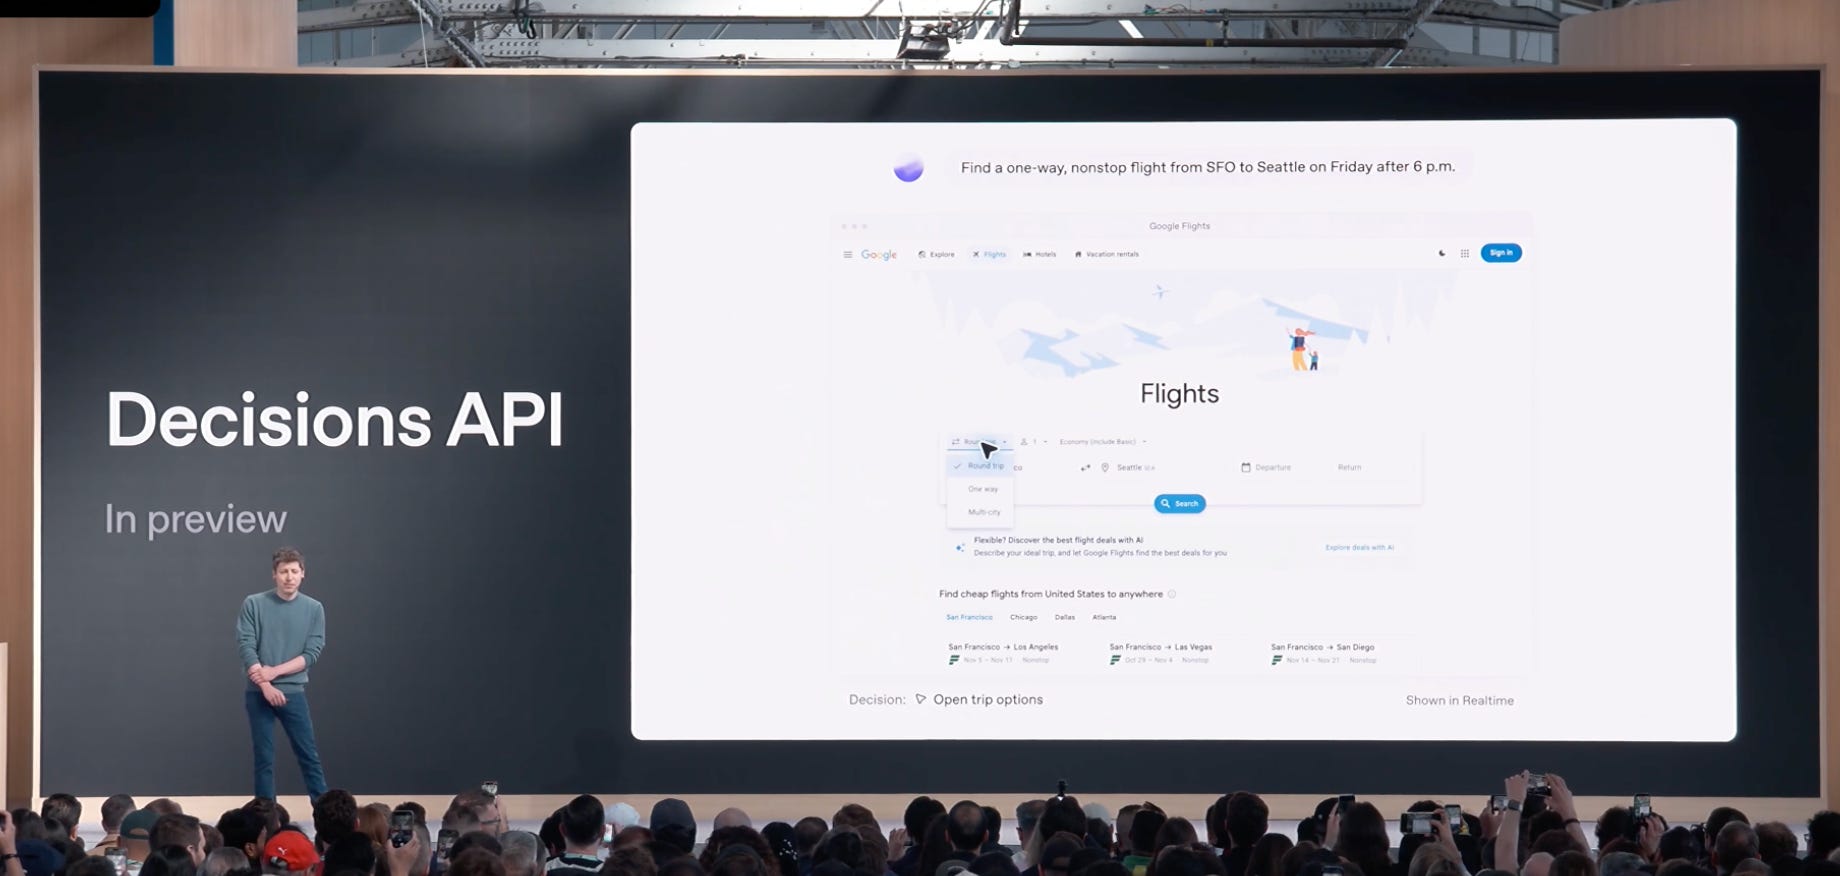
Update 1 (29 September, 10:20 am PT): OpenAI just announced the Decision API at their DevDay 2026 conference (29 September). It appears to be a Jev-like model directly integrated into their platform.
Decisions API enables real-time decision-making by focusing Luna’s intelligence on a specific set of user-defined questions with finite pre-defined answers. Developers supply context using text or images, and get back answers they can use to classify content, route requests, or choose an agent’s next action.
Available in limited preview today with a broad release planned in the coming days.
Update 2: A reader shared the Contrastive Language Models project with me in the comments below. It’s one of the nicer-looking Jev-likes. When I tried it, its IMDb test accuracy is just 82.90% (over 96.47% in Jev), and it fails the Tetris test.
Another reader wrote in about Laya, another strong contender. It did better at IMDb (92.33% test accuracy) but then failed the Tetris test even worse.
So, my point still stands. There are many solid alternatives. But what makes Jev so popular is not a unique idea (as mentioned before, classifiers existed for a long time) but the fact that it performs so well at so many diverse tasks. The only task where it allegedly doesn’t do well (as a reader told me) is legal reviews in non-English languages. (But the weak multilingual performance can be circumvented by connecting it to a cheap translation model, e.g., GPT -6 Luna with a small latency overhead.)
Conclusion
All in all, at first glance, Jev doesn’t seem to offer anything fundamentally new. After all, one might say that “it’s just a classifier” (with a nice API on top of it). However, it works surprisingly well across a huge range of tasks. In that sense, it’s the plug-and-play version of dedicated classifiers.
Sure, experts will still fine-tune specialist models, but the bar to justify fine-tuning a specialized model is now much higher, since it’s easy to just throw a Jev or Jev-like at it and get good-enough results.
Also, I don’t expect Jev and Jev-likes to unlock new capabilities or solve previously unsolvable tasks. However, if we make such models part of our agent harnesses to aid the expensive GPT-6 or Opus 5.5 models in decision-making within that harness, using agent harnesses could become much faster and cheaper in the future.
If you found this article useful, consider becoming a paid subscriber to Ahead of AI. Your support helps me spend more time on the experiments and detailed illustrations behind articles like this.
You can also support my work through my books, Build a Large Language Model (From Scratch) and Build a Reasoning Model (From Scratch), if you’d like to implement these concepts yourself. (And if you already have a copy, leaving a review would also help a lot.)
Thanks for reading and supporting my independent research!
I'm a bit confused by the calibration penalty. Isn't a cross entropy loss already self-calibrating? Of course that depends on the data distribution you train on, but assuming it's representative, why do we need a second penalty?
Fun footnote for the bag-of-words section. M. E. Maron was doing naive Bayes-style text classification back in 1961, sorting computer abstracts into 32 subject categories by their clue words.